
Why Global AI Teams Win: The Case for Follow-the-Sun AI Delivery


Introduction
Enterprise AI projects rarely stall because a model underperforms. They stall because delivery slows down between one team's sign-off and the next team's start time. A single-timezone team works eight or nine productive hours a day and then goes quiet. Whatever needs review, testing, or a second set of eyes waits until morning. Multiply that pause across a multi-month engagement, and the lost hours add up to lost weeks. Global AI teams don't have that problem. When one region wraps its shift, another is already awake and picking up the work. This article makes the case for that model directly, using Techtics' own distributed delivery structure as the proof rather than a hypothetical. By the end, the reasoning behind why global AI teams win should be hard to argue with.
What Is a Follow-the-Sun AI Delivery Model?
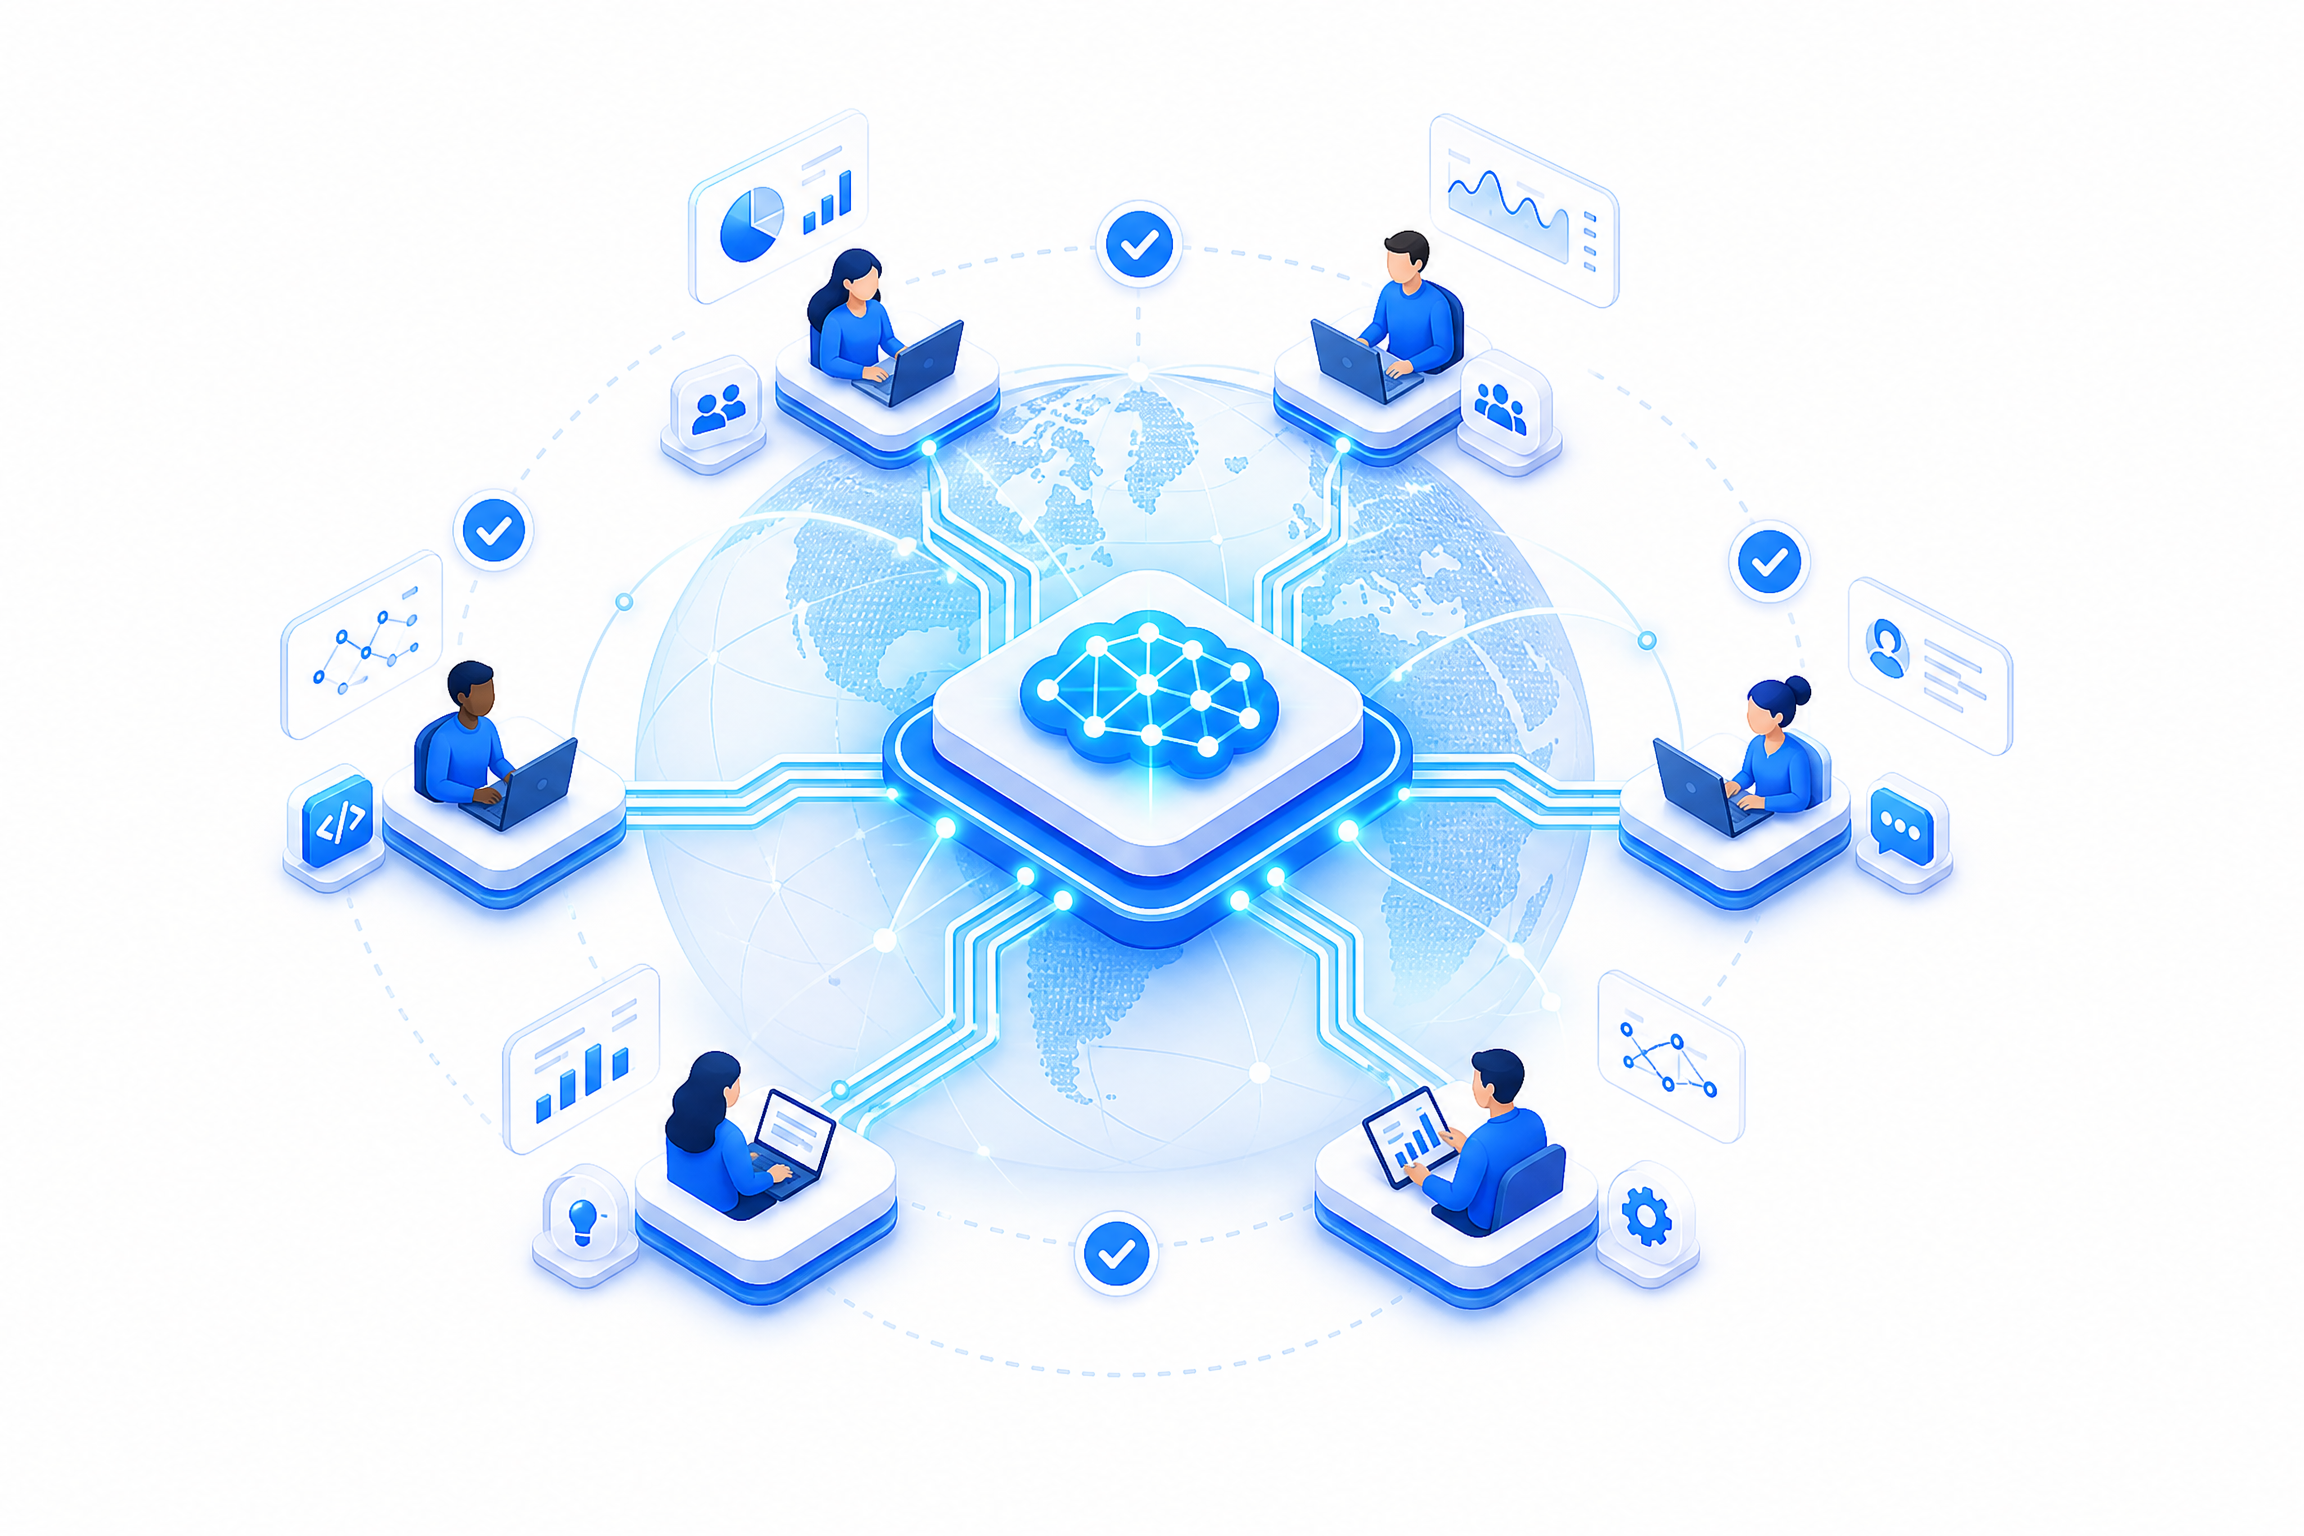
A follow-the-sun delivery model structures a project so that work continues across time zones instead of stopping when one office logs off. A developer in one region hands off a build to a reviewer in another region who is just starting their day. That reviewer hands off testing to a third region several hours later. Nobody is working around the clock individually, but the project itself never fully pauses. This is the operating principle behind global AI teams: distributed people, continuous progress. It's not about speed for its own sake. It's about removing the idle hours that come from staffing a technical project the same way a local retail business staffs a storefront.
Where Single-Timezone AI Teams Lose Time
Before explaining why distributed delivery works, it's worth being specific about where the alternative fails. A single-timezone team isn't necessarily less skilled or less committed. The constraint is structural, not a matter of effort. Three patterns show up consistently on projects staffed out of one location and one working day.
The 16-Hour Dead Zone Between Handoffs
If a team works a standard eight-hour day, roughly two-thirds of every 24-hour period passes with no active progress on the project. A model finishes training at 6 p.m. and sits untouched until the next morning. A bug gets flagged at 5 p.m. and waits overnight for a fix. None of this reflects poor planning. It's simply what happens when a project's clock matches one office's clock instead of the client's actual timeline.
Review Bottlenecks When One Team Owns Every Stage
When the same small group handles build, review, and testing in sequence, each stage waits its turn. A senior engineer can't review code the moment it's written if they're mid-way through their own task list. On a distributed team, review and build can run in parallel across regions instead of competing for the same hours.
Talent Ceiling of Hiring in One Market
Sourcing every engineer, data scientist, and QA specialist from one city or one country limits who's available and what they cost. Local hiring pools have real ceilings on niche AI skill sets, particularly for specialized roles like MLOps or model evaluation. A single-market team either compromises on specialization or waits longer to fill the role. Even a well-funded team in a single city eventually runs into the same wall: there are only so many senior computer vision engineers or agentic systems specialists in any one metro area, and competing local companies are hiring from that same shallow pool. A distributed structure sidesteps the problem instead of trying to out-recruit it. Hiring across regions doesn't just widen the applicant list; it changes the ceiling itself, since a specialist gap in one market can be filled from another without the project timeline absorbing the delay.
None of these three constraints are failures of a single-timezone team's discipline or work ethic. They're a direct consequence of staffing a technical delivery project the way a business might staff a single retail location, with one shift covering one set of hours. Enterprise AI work doesn't run on that schedule, and that mismatch is where the delivery slowdown actually starts.
How Distributed AI Teams Actually Ship Faster
Once the constraints of single-timezone delivery are clear, the advantages of a distributed structure follow naturally. This isn't a claim that spreading people across the map automatically produces speed. It's specific mechanics that change how work moves.
A project team spread across regions can pass work forward instead of letting it sit. That single shift changes the shape of a delivery timeline more than most process improvements do.
Continuous Build Cycles, Not Business-Hours Cycles
Instead of a project advancing only during one region's working day, it advances in relay. Region A builds and hands off. Region B reviews and tests while Region A sleeps. Region C picks up integration work as Region B wraps. The project keeps moving through what would otherwise be dead hours on a single-timezone team.
Specialist Coverage Instead of Generalist Overload
Distributed hiring means a project can draw a data engineer from one region, a computer vision specialist from another, and a deployment engineer from a third, without asking one small local team to cover every skill gap themselves. Coverage becomes a function of the whole talent pool, not just who happens to be hirable nearby.
Built-In Redundancy When a Region Is Down
A public holiday, a local outage, or one engineer taking sick leave doesn't have to stall a project when the work is distributed. Another region can absorb the gap. A single-office team doesn't have that cushion; if the office is closed, the project is closed too.
There's a compounding effect worth noting here as well. Each of these three mechanics, continuous cycles, specialist coverage, and redundancy, reinforces the other two. Continuous cycles only work if the handoff quality is high, which depends on having the right specialist available at each stage. Specialist coverage only holds up if the team has enough regional depth to provide redundancy when someone is unavailable. None of the three functions well in isolation. Together, they explain why global AI teams win on delivery speed rather than simply working more hours in total; the hours are the same, but the gaps between them close.
Inside Techtics' Distributed Delivery Model
None of this is theoretical for Techtics. The company operates as an enterprise AI and data consultancy with offices in Austin, Texas, and Lahore, Pakistan, and delivery coverage that extends across time zones spanning the USA and Canada, Europe, the Gulf and UAE, MENA, Pakistan and South Asia, and Australia. That structure isn't a marketing detail. It's the operating model behind how projects actually move.
Engineering Depth Across the Team
Techtics staffs projects with more than 100 certified engineers and over 10 PhDs on its team, supported by two-plus patents in its engineering work. That depth matters for a distributed model specifically because it means specialist coverage doesn't depend on any single office. A client working with Techtics isn't routed to whichever engineer happens to be available locally; they're routed to whichever engineer, in whichever region, is the right fit and the right hours for the task at hand.
One Delivery Standard Across Regions and Time Zones
A distributed team only works if every region follows the same technical standard, the same review process, and the same documentation practices. Otherwise, handoffs introduce friction instead of removing it. Techtics runs delivery this way deliberately: engineers in Austin and Lahore, and the teams coordinating across the broader coverage regions, work from a shared process rather than region-specific workflows. That consistency is what lets a build move from one time zone to the next without a translation step in between.
What This Structure Has Meant for Project Turnaround
Distributed delivery is designed to compress the gap between milestones, since work doesn't sit idle waiting for one office to reopen. The specific time saved varies by project scope and complexity, so it's worth evaluating case by case rather than quoting a single blanket figure. What stays consistent is the mechanism: a follow-the-sun structure removes the dead hours that a single-timezone team can't avoid, and that mechanism is what drives faster turnaround, project after project.
What to Look for in a Global AI Partner
Not every vendor that claims to be a "global AI team" actually operates one. Some simply have a sales office in a second country while all technical work happens in one location. For a business evaluating a partner, a few questions separate a genuinely distributed delivery model from one in name only.
- Does the team actually hand off work across time zones, or does everyone work the same shift regardless of location?
- Are engineering standards documented and shared, or does quality depend on which office happens to be staffed?
- Can the partner point to a track record of delivered projects and long-term partnerships, not just a list of office addresses?
These questions matter because "global" has become an easy word to put on a homepage without much behind it. A business evaluating vendors for an enterprise AI engagement is better served by asking a vendor to walk through an actual handoff, region by region, than by taking a map graphic at face value. The gap between a company that operates a genuine follow-the-sun model and one that simply has a second mailing address shows up fast once a project is underway, usually in the form of exactly the dead hours a distributed model is supposed to eliminate.
Delivery Overlap, Not Just Office Locations
A partner with offices in multiple countries isn't automatically running a follow-the-sun model. What matters is whether work genuinely passes between regions during the project, or whether the second office exists mostly for sales conversations while delivery stays centralized. Ask directly how handoffs happen and who's accountable at each stage.
Shared Engineering Standards Across Regions
Distributed delivery breaks down fast if each region follows its own conventions. A partner worth choosing should be able to describe, specifically, how code review, documentation, and testing standards stay consistent no matter which region is handling a given stage.
Proof of Scale — Projects, Partners, Products Delivered
Track record is the clearest signal available. Techtics has delivered more than 150 projects, works with over 70 partners, and has built more than 10 products across its portfolio, backed by a team spanning three global offices. That combination of project volume, partner relationships, and shipped products is a more reliable indicator than any pitch about "global reach" on its own.
The Real Advantage: Speed Without Sacrificing Quality
The case for global AI teams isn't that distributed delivery is faster at the expense of quality. It's the opposite. A follow-the-sun model builds in more review, not less, because a second region checks the work of the first before the project moves forward. Enterprise AI delivery speed and quality aren't competing goals under this structure; the structure is what makes both possible at the same time. For a business evaluating vendors, that's the actual question worth asking: not just how fast can this team move, but how many qualified eyes touch this project before it ships. That combination, speed paired with layered review across time zones, is the real reason why global AI teams win.
Frequently Asked Questions
What does "follow-the-sun" mean in AI development?
It refers to a delivery structure where work passes between teams in different time zones so a project keeps advancing through build, review, and testing stages without waiting for one office to reopen the next day.
Are distributed AI teams more expensive than local teams?
Not inherently. Distributed teams can access a wider talent pool across regions, which often controls cost rather than inflating it, while also reducing the idle time that extends single-timezone project timelines.
How do global AI teams maintain consistent quality across regions?
Through shared engineering standards, documented review processes, and consistent testing practices that apply no matter which region is handling a given stage of the project.
Is a distributed delivery model better for large enterprise AI projects specifically?
Larger enterprise projects tend to benefit the most, since they involve more handoffs, more specialized roles, and more review cycles, all of which move faster when spread across time zones instead of funneled through one office.
Recent Articles
Zero-Trust Security Frameworks for AI-First Organizations

For three decades, enterprise security was built around a simple assumption: define a perimeter, secure it, and trust whatever sits inside it. That model made sense when "inside the network" meant employees on company devices, behind a firewall, accessing systems through known applications.
AI-first organizations have quietly broken that assumption. Autonomous agents now query databases, call APIs, trigger workflows, and make decisions without a human clicking anything. The "trusted insider" in today's enterprise might be a piece of software that was prompted into existence an hour ago. Perimeter security has no good answer for that — which is exactly why zero trust has moved from a security buzzword to an operational necessity.
Why Traditional Perimeter Security Fails AI-First Organizations
Perimeter-based security assumes a relatively static, predictable set of actors: known users, known devices, known applications, all operating inside a defined boundary. AI systems violate nearly every part of that assumption.
Agents act with their own credentials, not a human's. An AI agent calling internal APIs, querying a database, or triggering a downstream workflow isn't a person logging in from a recognized laptop — it's a service identity that can be spun up, modified, or duplicated in seconds.
The attack surface is conversational, not just structural. Prompt injection attacks don't exploit a network vulnerability; they exploit the model's interpretation of input text. A malicious instruction embedded in a document, email, or web page can manipulate an agent into taking unauthorized actions, and a firewall has no visibility into that kind of attack at all.
Excessive agency creates new blast radii. When an AI agent is granted broad permissions to "get the job done" — access to multiple systems, the ability to execute code, the ability to send communications — a single compromised or manipulated agent can cause damage across every system it touches, not just the one it was originally deployed for.
Workloads move and scale dynamically. Containers, serverless functions, and orchestrated AI pipelines spin up and tear down constantly, which makes a fixed network perimeter nearly impossible to define in the first place.
None of this means perimeter security is worthless — but it means it's no longer sufficient on its own. Organizations deploying AI agents at scale need a model that doesn't assume safety based on location inside a network boundary.
What Zero Trust Actually Means
Zero trust is often summarized as "never trust, always verify," but the more useful framing for AI-first organizations is this: assume any identity, device, workload, or data request could be compromised, and require continuous verification before granting access — regardless of where the request originates.
This is a meaningful shift from perimeter thinking. Instead of asking "is this inside our network," zero trust asks "is this specific request, from this specific identity, for this specific resource, legitimate right now." That question gets asked every time, not once at login.
The Four Pillars of Zero Trust for AI Systems
A practical zero-trust architecture for AI-first organizations rests on four areas of continuous verification.
Identity
Every human user, service account, and AI agent needs a distinct, verifiable identity — not shared credentials, not generic API keys reused across systems. Agent identities should be issued, rotated, and revoked with the same discipline applied to human accounts, and every action an agent takes should be traceable back to that specific identity.
Device
The infrastructure an AI workload runs on — the container, the virtual machine, the edge device — needs to be verified as a known, compliant environment before it's trusted with sensitive operations. This matters more in AI systems than traditional ones because inference often happens across distributed, ephemeral compute resources rather than a fixed set of company-owned machines.
Workload
Each service, model, and pipeline component should be treated as its own trust boundary, with explicit rules governing what it can call, what data it can access, and what actions it can trigger. Microsegmentation — isolating workloads from each other rather than allowing broad internal network access — limits how far a compromised agent or model can reach.
Data
Data needs classification, encryption, and access policies that travel with it, not protections that depend on where the data happens to sit. When an AI agent retrieves data to answer a query or take an action, that retrieval should be checked against the same access policy a human user would face — not granted automatically because the request came from "inside" the system.
The Unique Attack Surface of Autonomous AI Agents
AI-first organizations face attack vectors that didn't meaningfully exist in pre-AI enterprise environments:
- Prompt injection. Malicious instructions hidden in documents, emails, or retrieved web content can hijack an agent's behavior, redirecting it to leak data or perform unauthorized actions.
- Tool and function-calling abuse. Agents with access to tools — sending emails, executing code, modifying records — can be manipulated into misusing those tools in ways a static application never could be.
- Excessive agency. Granting an agent broad, standing permissions "just in case" turns a narrow task into a wide-open liability if that agent is ever compromised or manipulated.
- Model and data poisoning. Attackers targeting training data or fine-tuning pipelines can introduce subtle behavioral changes that are difficult to detect through conventional security monitoring.
- Insecure agent-to-agent communication. As multi-agent systems become more common, the channels agents use to coordinate with each other become a new, often under-monitored attack surface.
These risks share a common thread: they exploit trust granted by default rather than verified continuously, which is precisely the gap zero trust is designed to close.
Implementing Zero Trust for AI Agents: Practical Steps
Issue scoped, short-lived credentials for every agent. Replace long-lived API keys with credentials that expire quickly and grant access only to the specific resources a given task requires — not standing access to entire systems.
Apply least-privilege access by default. An agent built to summarize support tickets shouldn't also have write access to the billing database. Default to the narrowest permission set that allows the task to function, and expand only with explicit justification.
Microsegment workloads. Isolate AI services from each other and from broader internal networks so that a compromised component can't move laterally to systems it was never meant to touch.
Monitor continuously, not just at access time. Behavioral anomaly detection — flagging when an agent suddenly accesses unusual data, calls unfamiliar tools, or deviates from expected patterns — catches manipulation that a one-time login check would miss entirely.
Classify and encrypt data at the source. Data should carry its access policy with it, so that any agent or service retrieving it is automatically subject to the same rules regardless of how it was queried.
Require human-in-the-loop checkpoints for high-risk actions. Irreversible or high-impact actions — financial transactions, external communications, code deployment — should route through human approval rather than full autonomous execution, at least until an agent's reliability has been extensively validated.
Validate and sanitize inputs to agents. Treat any external content an agent processes — documents, emails, scraped web pages — as potentially adversarial, and build filtering layers that reduce the risk of embedded prompt injection reaching the model unchecked.
Common Mistakes Organizations Make
Many AI-first organizations adopt zero-trust language without changing underlying architecture. A few patterns show up repeatedly:
- Treating zero trust as a product purchase rather than an architectural shift. A single identity tool doesn't deliver zero trust if workloads still communicate over flat, unsegmented networks.
- Granting agents human-equivalent access "to be safe." This inverts least-privilege thinking and creates exactly the broad blast radius zero trust is meant to prevent.
- Verifying identity once at deployment and never again. Continuous verification means re-checking trust at each request, not establishing it once when an agent is first provisioned.
- Ignoring agent-to-agent traffic. As multi-agent architectures grow, the assumption that "internal" agent communication is automatically safe recreates the same blind spot perimeter security had for human users.
Building a Zero-Trust Roadmap for AI Adoption
Organizations don't need to implement every control simultaneously. A practical rollout typically starts with identity — issuing distinct, scoped credentials for every agent and service — followed by microsegmentation of the highest-risk workloads, then continuous monitoring layered on top. Data classification and encryption policies should be established early, since retrofitting them after agents are already in production is significantly harder than building them in from the start.
The organizations managing AI risk well aren't the ones avoiding autonomous agents — they're the ones that have rebuilt their security architecture around the assumption that any identity, device, workload, or data request might be compromised, and verify accordingly, every time.
Talk to Our Team About Securing Your AI Systems
If your organization is deploying autonomous agents faster than your security architecture has evolved to handle them, that gap is worth closing before it becomes an incident. Talk to our team about building a zero-trust framework designed for how AI systems actually operate.
First Call to POC: How We Compress 6-Month to 5 Weeks
If you've ever sat through an enterprise AI pitch, you've heard the timeline: six months to a proof of concept. Sometimes nine. The vendor walks you through a Gantt chart full of "discovery phases" and "alignment workshops," and by month four you're still debating data access policies instead of looking at a working model.
That timeline isn't a reflection of how hard AI is to build. It's a reflection of how badly most teams manage the process of building it.
At Techtics, we take clients from first call to a validated, working proof of concept in five weeks. Not five weeks of slide decks — five weeks that end with a functioning system your team can actually test against real data and real workflows. Here's how that compression happens, and why it isn't about cutting corners.
Why Most AI Timelines Run Six Months (or Longer)
Six-month AI engagements rarely fail because the underlying model is hard to train. They fail because of structural drag built into how enterprise teams typically approach AI projects.
Procurement and vendor evaluation eat the first six to eight weeks.
Most organizations run a formal RFP process before a single line of code gets written, comparing five vendors against requirements that are still being defined.
Requirements gathering becomes a project of its own.
Stakeholders from product, engineering, compliance, and operations all need to weigh in, and reconciling their priorities can stretch into months if there's no structured way to capture and validate use cases quickly.
Data access and integration get treated as an afterthought.
Teams often don't audit their data sources, APIs, and system access until after the build has started, which means the engineering team discovers blockers mid-sprint instead of in week one.
Scope keeps expanding.
Without a fixed, validated use case, "let's also add this feature" creeps in continuously, and a focused POC slowly turns into a half-built production system that never quite ships.
None of these are technology problems. They're sequencing and discipline problems — and they're fixable.
The Real Bottleneck Isn't Technology, It's Process
Modern AI tooling — pretrained models, vector databases, orchestration frameworks, cloud-native infrastructure — has compressed the technical build time for a focused POC down to days, not months. A well-scoped predictive model, a retrieval-augmented chatbot, or an automation workflow can be prototyped in a sprint by an experienced team.
What actually consumes time is everything around the build: getting the right people in a room, validating that the use case is real before writing code, securing data access, and aligning on what "done" looks like. Compress those steps and the technical build naturally fits inside the remaining runway.
This is the core insight behind our 5-week framework: treat process compression, not engineering speed, as the primary lever.
The 5-Week Framework: From First Call to Validated POC
Week 1 — Discovery and Use Case Validation
The first call isn't a sales conversation; it's a working session. We map the business problem, identify the specific decision or workflow the AI system needs to improve, and validate that the use case is solvable with available data before committing engineering time. By the end of week one, there's a written scope document with success metrics both sides have signed off on.
Week 2 — Data Audit and Architecture Sprint
This is where most enterprise timelines silently lose months, so we front-load it. Our team audits data sources, API access, security requirements, and existing infrastructure in parallel with architecture design. We identify blockers now — missing data, access bottlenecks, compliance constraints — while there's still time to route around them without derailing the build.
Week 3 — Build Sprint
With scope and data access confirmed, the engineering team builds the core system: the model, the automation pipeline, the agent workflow, or whichever architecture fits the validated use case. Because scope was locked in week one, the team isn't building against a moving target.
Week 4 — Integration and Testing
The POC gets connected to a real (or representative) data environment and tested against the success metrics defined in week one. This is also when we run edge cases and stress-test the system against the messy, inconsistent data that real production environments actually contain, rather than the clean sample sets most demos rely on.
Week 5 — Validation and Stakeholder Sign-off
The final week is for the client's team to actually use the system, not watch a demo of it. Stakeholders test it against real scenarios, we capture feedback, and we document a clear path from POC to production scale-up. By the end of week five, you have a working system and a data-backed decision on whether to move forward.
What Makes Compression Possible (Without Cutting Corners)
A 5-week timeline only works because of decisions made well before the engagement starts:
- Reusable component libraries. Common building blocks — authentication layers, data connectors, model evaluation pipelines — don't get rebuilt from scratch for every client, which removes weeks of redundant engineering.
- Parallel workstreams instead of sequential handoffs. Data audits, architecture design, and early prototyping happen simultaneously rather than waiting on each other in a linear chain.
- Fixed-scope POC agreements. Locking the use case in week one prevents the scope creep that quietly turns a five-week sprint into a five-month slog.
- Embedded subject matter access. Having a PhD-level research team and domain specialists involved from day one means fewer "let's circle back next week" delays caused by needing outside expert input.
- Pre-vetted infrastructure templates. Cloud architecture and CI/CD patterns that have already been proven across 150+ prior projects don't need to be re-validated from zero each time.
This is compression through preparation, not through skipping validation steps. The POC that comes out the other end is something your team can stress-test, not a fragile demo built to impress in a single meeting.
What This Means for Enterprise Buyers
If you're evaluating AI vendors, the length of a proposed timeline tells you more about their process maturity than their technical capability. A team that needs six months to reach a POC is often telling you they haven't solved the coordination problem — not that the AI problem itself is six months deep.
A faster, well-structured timeline also changes the risk profile of the decision. Instead of committing budget and internal resources for half a year before seeing results, a 5-week POC gives you a concrete, testable artifact to evaluate before any larger commitment. That shifts AI adoption from a leap of faith into a series of small, validated bets.
Common Pitfalls That Stretch Timelines Back to Six Months
Even with a compressed framework available, a few mistakes can pull a project back toward the slow end:
- Skipping the data audit. Teams that jump straight to building without confirming data access almost always hit a wall mid-sprint.
- Letting stakeholders weigh in after the build starts. Validation needs to happen in week one, not week four, or scope will shift under the team's feet.
- Treating the POC like a finished product. A POC exists to validate an approach with real users and real data — not to ship every feature a production system would eventually need.
- Choosing a use case that's too broad. "Improve customer service with AI" isn't a scoped use case. "Reduce average response time on tier-one billing tickets using an AI triage agent" is.
Is Five Weeks Right for Every Use Case?
Not every AI initiative fits neatly into a five-week box — a multi-system enterprise rollout touching dozens of legacy integrations will need a longer runway. But for the most common entry point into enterprise AI — a focused proof of concept validating one clear use case — five weeks is achievable for the vast majority of organizations, provided the discovery and data audit steps aren't skipped.
The goal isn't speed for its own sake. It's removing the unnecessary friction that turns a solvable problem into a half-year commitment, so your organization can make a confident, evidence-based decision about scaling AI faster.
Frequently Asked Questions
How is a 5-week POC different from a typical MVP? A POC validates whether an approach works at all — does the model perform well enough on real data, does the workflow actually save time, is the use case technically feasible. An MVP assumes the approach is already validated and focuses on shipping a usable product to early customers. The 5-week framework is built for the validation stage, which is exactly where most AI initiatives stall.
What happens after the POC if we want to move to production? The week 5 deliverable includes a documented scale-up path: infrastructure requirements, security and compliance considerations, integration points with existing systems, and an estimated timeline for production deployment. Clients use this to make an informed go/no-go decision with their own stakeholders before committing further budget.
What if our data isn't ready? This is exactly why the data audit happens in week two rather than being assumed away. If data quality or access issues surface, we flag them immediately and adjust scope — sometimes that means narrowing the use case to data that is available now, with a roadmap for expanding once additional data sources are cleaned up or connected.
Does a faster timeline mean a less rigorous build? No. Rigor comes from validating the use case correctly and testing against real conditions in week four, not from how many calendar weeks the engagement runs. The compression comes from removing redundant process overhead, not from skipping testing or validation steps.
Ready to See Your Use Case in Five Weeks?
If your team has been quoted a six-month AI timeline, there's a good chance the bottleneck isn't the technology — it's the process around it. Talk to our team and find out what a validated proof of concept could look like for your organization in five weeks, not six months.
A Practical Roadmap for Your Organization's AI Automation Strategy
The numbers tell a paradoxical story. According to McKinsey's State of AI research, 78% of organizations now use AI in at least one business function, making it one of the fastest-adopted technologies ever tracked. Yet only a small fraction, roughly 5%, qualify as "AI high performers" who see meaningful bottom-line impact from their investments. Gartner predicted that at least 30% of generative AI projects would be abandoned after proof of concept due to poor data quality, inadequate risk controls, escalating costs, or unclear business value, and it forecasts that over 40% of agentic AI projects will be canceled by the end of 2027. An MIT study made headlines claiming as many as 95% of GenAI pilots fail to deliver meaningful results.

The lesson is unambiguous: adopting AI is easy; creating value with AI is hard. The difference between the two is not the sophistication of the models you use. It is the discipline of your strategy.
Having spent two decades at the intersection of academic research and applied AI, and having helped deliver 120+ AI projects across 20+ countries through Techtics.ai, I have seen the same pattern repeatedly. Organizations that succeed with AI do not start with technology. They start with a structured assessment of need, value, feasibility, and risk, and they execute through a staged, measurable implementation pipeline. This article lays out that roadmap.

Step 1: Begin with an Honest AI Need Assessment
Every successful AI journey begins with a deceptively simple question: What problem are we actually trying to solve?
Too many AI initiatives are born from FOMO rather than need. The board hears competitors are "doing AI," and a mandate descends without any connection to operational pain points. This is precisely the dynamic Gartner analysts describe when they note that most early agentic AI projects are "driven by hype and often misapplied."
A genuine need assessment examines your organization's value chain end to end and asks:
- Where do we lose the most time, money, or quality today?
- Which decisions are made slowly, inconsistently, or with incomplete information?
- Which processes are repetitive, rule-bound, and data-rich, the natural habitat of automation?
- Where are customers or employees experiencing friction that better intelligence could remove?
The output of this stage is not a technology wishlist. It is a prioritized map of business pains and opportunities, expressed in the language of operations and finance, not in the language of models and algorithms.
Step 2: Identify Potential Use Cases and Cast a Wide Net
With needs mapped, translate them into candidate AI use cases. At this stage, breadth matters more than precision. Industry frameworks such as Gartner's AI use-case prisms are instructive here: whether you operate in insurance, media, utilities, legal practice, B2B sales, digital commerce, smart cities, or automotive, there are typically 15 to 20 well-recognized use cases per industry, from churn prediction and fraud detection to demand forecasting, content personalization, predictive maintenance, lead scoring, and intelligent process automation.
Workshop these with the people who actually run the processes. In our discovery workshops at Techtics, frontline managers routinely surface automation candidates that never appear on the executive radar: the invoice that takes three departments to validate, the phone orders transcribed manually, the blueprints reviewed line by line. These "unglamorous" use cases are often the highest-ROI ones.
Step 3: Evaluate Every Use Case on Two Axes — Business Value and Feasibility
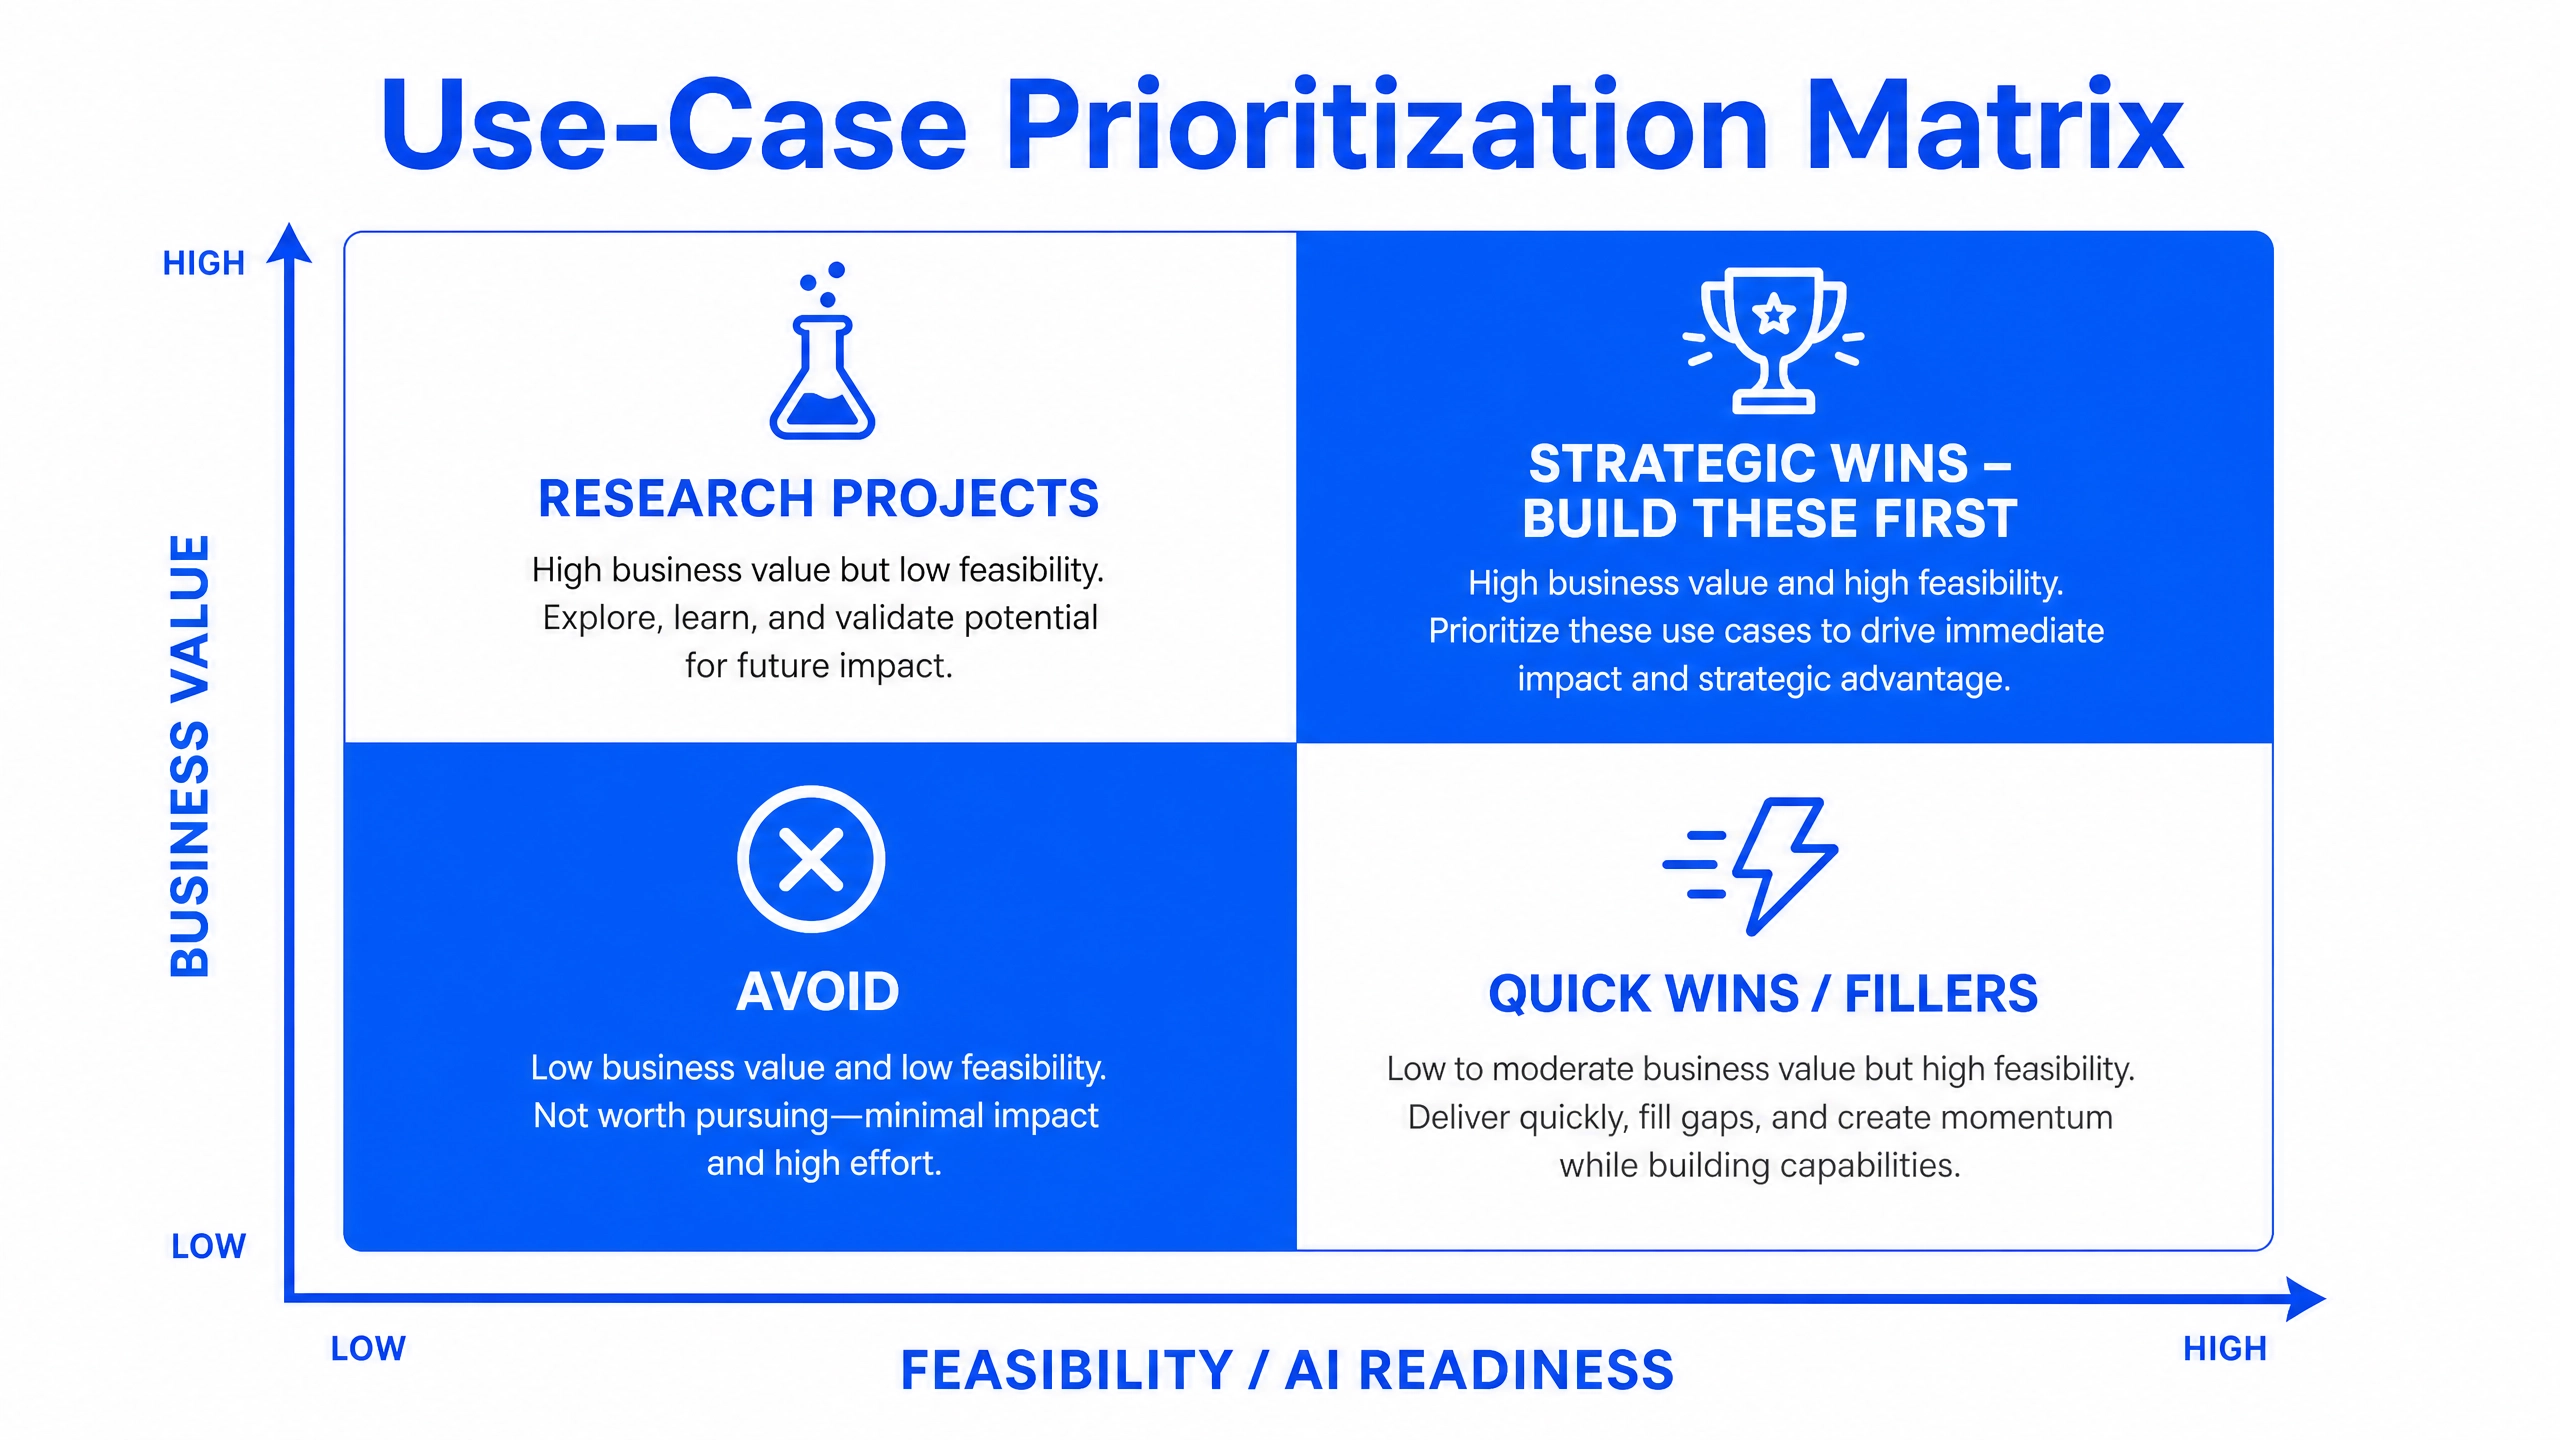
This is the heart of the methodology, and it is where most organizations cut corners. Every candidate use case must be plotted against two independent dimensions: the business value it can create and the feasibility of actually delivering it. A use case that scores high on value but low on feasibility is a research project, not a roadmap item. A use case that is highly feasible but low value is a distraction.

The Business Value Lens
Value addition from AI automation typically flows through four channels: positive financial impact (cost reduction and revenue growth), improved quality (of service, product, and operations), time reduction, and reduced human intervention. In practice, I encourage leadership teams to score each use case against a concrete checklist: process improvement (does it remove steps, handoffs, or rework?), service improvement, HR efficiency, cost reduction, error reduction, quality improvement, offering scale (can you serve 10x volume without 10x headcount?), and revenue increase.
Then perform a hard-nosed revenue-versus-cost analysis. Estimate the total cost of ownership (not just development, but deployment, recurring inference and licensing costs, and maintenance) against quantified annual value. If the payback period exceeds 18 to 24 months under conservative assumptions, deprioritize.
These projections are not fantasy when grounded in real benchmarks. From our own delivery portfolio: a retail computer-vision analytics deployment delivered a 10% increase in customer base, 12% improvement in conversion, and 10% reduction in human resource requirements; a food-and-beverage analytics solution cut food wastage by 10% while optimizing HR deployment by 20%; a power-plant anomaly detection system lifted plant productivity by 12%; and an insurance field-force automation improved productivity by 400%. Realistic, sector-specific reference points like these should anchor your value estimates.
The Feasibility / AI-Readiness Lens
Feasibility is where the 30% to 95% failure statistics are born. Gartner's research attributes most AI project failures to poor data quality and predicts that 60% of AI projects lacking AI-ready data will be abandoned through 2026. Feasibility assessment must therefore go far beyond "can the model be built?" It spans technical, organizational, and adoption readiness:
- Organizational readiness. Are the underlying processes well-defined and stable enough to automate? Is the process digitalized, or does it still live on paper and tribal knowledge? Does the data needed for AI exist, in usable quality and volume, with the rights to use it? Do the relevant stakeholders genuinely intend to change how they work?
- Management readiness. Is top leadership visibly committed, not just approving but sponsoring? Is there financial readiness to fund not only the build, but the run? McKinsey found that, among 25 organizational attributes tested, redesigning workflows and putting senior leaders in critical AI roles had the strongest correlation with realizing EBIT impact from AI. AI delegated to the IT department alone almost always stalls.
- Cost realism. Account for the full cost stack: development cost, deployment and running cost, recurring costs (API and LLM usage, compute, licensing), and maintenance cost. GenAI in particular carries recurring inference costs that can quietly dwarf the initial build, which is one of the principal reasons Gartner cites "escalating costs" as a top abandonment driver.
- Relevant departments' readiness and willingness. Are the stakeholders who own the process open to this change? Do they have, and will they share, the data? Are they willing to adopt the solution and adapt their ways of working around it? A technically perfect system that the operating team quietly works around delivers zero value. BCG's 10-20-70 principle captures this: AI success is roughly 10% algorithms, 20% data and technology, and 70% people, process, and cultural transformation.
- Occurrence frequency. How often is the use case executed? How much time does each execution take, and what does it cost? Automation economics compound with frequency: a process run 10,000 times a month justifies investment that a quarterly process never will. Frequency also determines whether automation scales the business, turning a capacity ceiling into a growth lever.
Step 4: Risk Analysis — The Dimension Everyone Skips
Before selection, every shortlisted use case must pass a structured risk review across at least three dimensions:
- Correctness risk. What happens when the AI is wrong? A product-recommendation error costs a click; an error in invoice validation, medical imaging, or legal document analysis costs real money and trust. Define acceptable error tolerances, human-in-the-loop checkpoints, and fallback procedures before you build. McKinsey's surveys consistently show inaccuracy is the most commonly experienced negative consequence of GenAI use.
- Dependency on external AI (LLMs). Building on third-party foundation models introduces dependencies on pricing changes, model deprecations, rate limits, behavior drift across versions, and vendor lock-in. A sound architecture abstracts the model layer, benchmarks alternatives, and, where volume justifies it, considers fine-tuned or self-hosted models to control recurring cost and continuity risk.
- Data privacy and security. Where does your data go when it enters an AI pipeline? Regulatory regimes (GDPR, HIPAA, sector-specific rules) and customer trust both demand clear answers. This consideration alone often dictates the deployment model (on-premises, private cloud, or hybrid), which in turn reshapes the cost equation.
Step 5: Select and Prioritize
With value, feasibility, and risk scored, selection becomes almost mechanical: choose use cases that sit in the high-value, high-feasibility, manageable-risk quadrant. Then prioritize within that set using three tie-breakers:
- Time-to-value. Early, visible wins build the organizational confidence that funds the harder, bigger wins later.
- Strategic leverage. Does this use case build data assets, infrastructure, or capabilities that make the next use cases cheaper?
- Sponsorship strength. Start where the business owner is most committed.
Resist the temptation to launch five initiatives at once. The organizations stuck in "pilot purgatory" are usually those running many shallow experiments rather than a few deep deployments.
Step 6: Implement Through a Staged Pipeline
For each selected use case, disciplined staging is what separates the 5% who realize value from the rest. The pipeline runs PoC, then MVP, then Pilot, then Scale, then Deployment and Maintenance, with a hard gate between every stage:
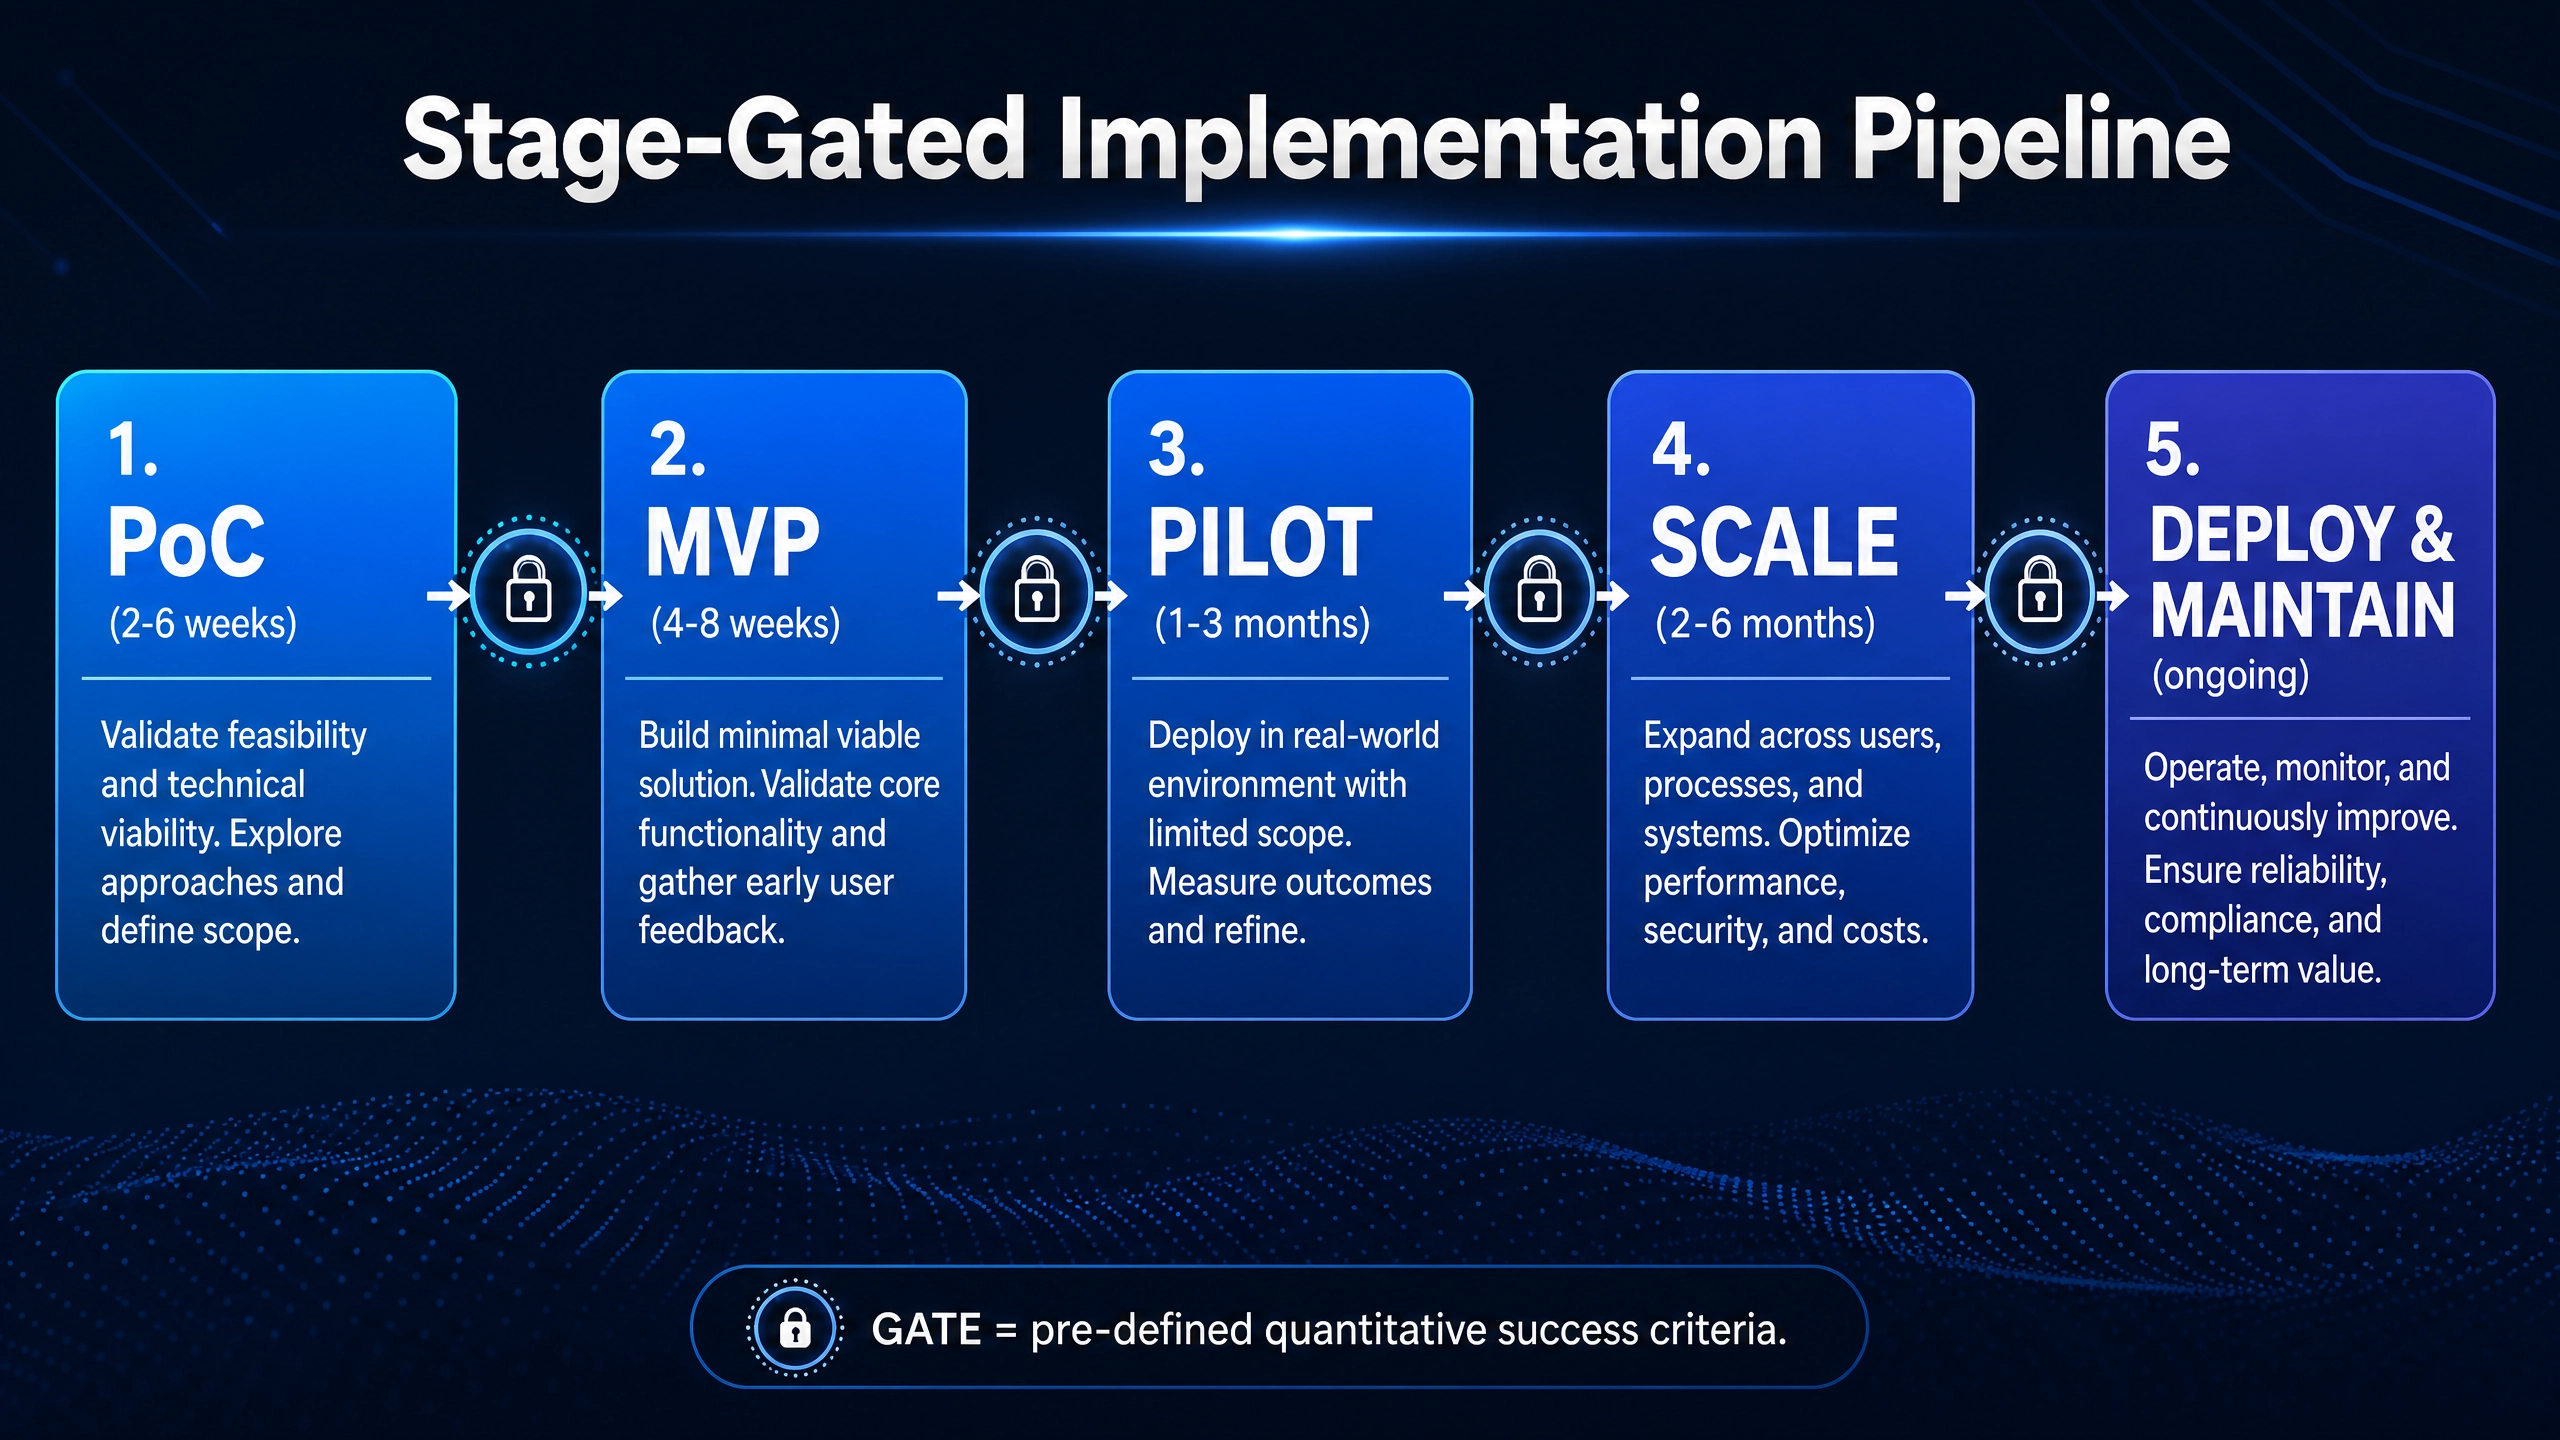
- Proof of Concept (2–6 weeks). Validate the core technical hypothesis on real (not curated) data. The deliverable is evidence, not a product. Define quantitative success criteria upfront, and be willing to kill the project here cheaply. A killed PoC is a success of the methodology, not a failure.
- MVP. Build the minimum end-to-end system a real user can use for a real task, integrated with at least one real upstream and downstream system. This is where integration realities surface.
- Pilot. Run in a live operational environment with a bounded scope: one region, one product line, one team. Measure business KPIs, not model metrics: cycle time, error rate, cost per transaction, user adoption. The pilot is a stress test of organizational readiness as much as of technology.
- Scale. Expand coverage with hardened infrastructure, monitoring, retraining pipelines, and support processes. This is where data drift, edge cases, and load break naive systems. Plan for it from MVP onward, not after.
- Deployment and Maintenance. AI systems are living systems. Models degrade, data distributions shift, business rules change, and LLM providers update their models. Budget ongoing MLOps, monitoring, and periodic revalidation as a permanent operating cost, not an afterthought.
Step 7: Close the Loop — Expected Value vs. Actual Value
The final discipline, and the rarest, is the review assessment: a formal comparison of the value you projected in Step 3 against the value actually realized in production. McKinsey notes that most organizations still lack robust KPIs for their AI initiatives, and that where rigorous tracking exists, value realization rises and risk incidents fall.
Did the 12% productivity lift materialize, or did it stop at 6%, and why? Was the recurring cost in line with the forecast? Did adoption hold after the novelty faded? This review does three things: it keeps everyone honest, it sharpens the assumptions for the next use case, and it converts AI from a faith-based investment into a managed portfolio.
The Very Important Concern: Choosing the Right Technology Partner
Everything above describes what to do. The most consequential decision, however, is often who you do it with, and it deserves direct treatment.
An impactful and sensible AI strategy is rarely developed in isolation. It is best built with a technology partner and consultant who brings relevant, cross-industry delivery experience: someone who has seen where feasibility assessments go wrong, which value estimates prove optimistic, and which architectural decisions come back to haunt you in year two.
Here is the uncomfortable truth about AI economics that inexperienced teams learn expensively: the build cost is only the entry ticket. The development cost, the recurring cost of running the automation, the deployment cost, the maintenance cost, and the selection of the appropriate deployment model (on-premises, cloud, or hybrid) collectively determine whether your AI initiative is an asset or a liability. A GenAI solution that delights in the demo can hemorrhage money in production if every transaction triggers expensive LLM calls that a smarter design would have avoided.
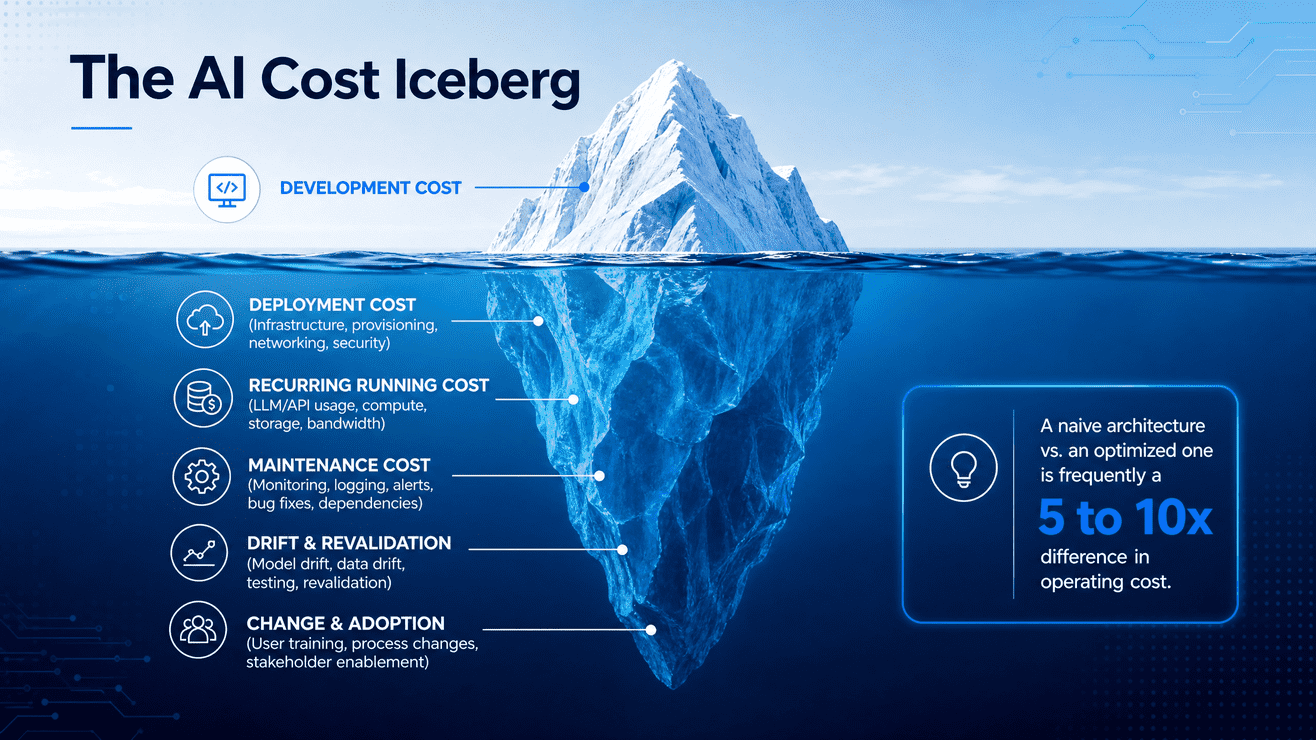
This is where seasoned teams distinguish themselves. They do not merely develop a solution; they develop a cost-effective solution, using smart algorithms, caching strategies, model right-sizing (using a small model where a large one is unnecessary), retrieval architectures, hybrid rule-based/ML designs, and other architectural improvisations that systematically minimize recurring cost. The difference between a naive architecture and an optimized one is frequently 5x to 10x in operating cost, which is the difference between a positive and negative ROI on the same use case.
When evaluating a partner, ask:
- Can they show delivered outcomes with numbers, not just demos?
- Do they have breadth across agentic AI, generative AI, computer vision, and data analytics, so they recommend the right tool rather than the only tool they know?
- Do they lead with discovery and feasibility assessment, or do they jump straight to a quote?
- Can they articulate your total cost of ownership across deployment options before writing a line of code?
- Will they structure delivery as PoC, MVP, Pilot, then Scale, with kill-switches and success criteria at each gate?
Where Techtics.ai Fits In
At Techtics.ai, this methodology is not theory; it is how we work. Founded in 2022 and now 80+ professionals strong, with 10 PhDs, 200+ research publications, and 120+ delivered projects across 20+ countries, we have built our practice around exactly the lifecycle described in this article: discovery workshops (1–2 weeks), proof of concept (2–6 weeks), development and deployment (2–6 months), and go-live support. In practical terms, your PoC can be in your hands within 3 to 4 weeks of our first conversation.
Our delivery spans agentic AI (multi-agent CRM and order automation, AI-driven invoice processing, voice ordering agents, B2B lead-generation automation), generative AI (content automation, AI-powered screening, financial agents, 3D modeling for e-commerce), computer vision (retail analytics, fleet management, aerial surveillance, insurance auto-scan), and data analytics (anomaly detection, forecasting, waste-reduction analytics), across retail, supply chain, education, insurance, food & beverage, cybersecurity, legal, media, and more.
More importantly, we engage as a strategic partner, not a vendor: we will tell you which of your use cases not to build, we will design for your recurring-cost reality and your deployment constraints, and we will measure ourselves against the actual-versus-expected value review, because that is the only metric that matters.
If you are ready to move from AI ambition to AI impact, let's start with a discovery workshop.
Ready to Go Beyond the Article?
Technology is
in our DNA


