
Product-Market Fit for AI Products: Why the Rules Are Different


Introduction
Every product team knows the old test. Rahul Vohra popularized it, Sean Ellis built a movement around it, and for over a decade, the 40% threshold has served as the north star for product-market fit. Ask users how they'd feel if your product disappeared tomorrow. If 40% or more say "very disappointed," you've found fit. Ship it, scale it, defend it.
That test assumes something quietly important: the product being measured stays still long enough to measure. A SaaS tool built in March behaves the same way in September, aside from the features you deliberately add. The survey works because the object of the survey holds its shape.
Product-Market Fit for AI Products: Why the Rules Are Different starts from a different premise. An AI product doesn't hold its shape. The underlying model can drift as new data flows in. Output quality can shift between two customers using the exact same feature. A single prompt change can quietly alter behavior across the entire user base. Fit, in this context, isn't a fixed target you hit once — it's a moving relationship between three forces: data dependency, iteration cost, and trust. Miss any one of them, and the numbers on your PMF survey will lie to you.
Why Standard SaaS PMF Frameworks Fall Short for AI
Traditional PMF frameworks were built for products where the interface is the variable and the logic underneath is fixed. Change a button, measure the response, repeat. AI products invert that relationship — the logic underneath is the variable, and it changes on its own even when nobody touches the interface.
SaaS Fit Is About Workflow Match; AI Fit Is About Workflow and Output Reliability
A standard SaaS tool earns its place by fitting into how a team already works. Does it save time? Does it replace three spreadsheets? Does it reduce the number of tabs open at once? Fit is largely a workflow question, and workflow questions have stable answers.
An AI product has to clear that same workflow bar and then clear a second one: is the output right often enough to be useful? A CRM add-on that automates data entry only earns adoption if the entries it makes are accurate. Workflow match gets a user to try the product. Output reliability gets them to keep using it.
Feature-Based PMF Surveys Don't Capture Model Drift or Output Variance
The Sean Ellis survey asks about disappointment if a feature disappeared. It doesn't ask whether the feature performed consistently last week versus this week. That gap matters more than it looks. A model can degrade gradually as the distribution of real-world inputs shifts away from what it was trained or tuned on, and a satisfaction survey run at a single point in time won't catch that decline until users have already started quietly abandoning the product.
Feature-based surveys treat capability as binary — present or absent. AI capability is closer to a spectrum that moves.
The Feedback Loop Is Probabilistic, Not Deterministic
In deterministic software, a given input produces the same output every time. Debugging is a straight line: find the input, trace the logic, fix the bug. In AI systems, the same input can produce different outputs depending on model version, temperature settings, or the data available at that moment. That means the feedback loop teams rely on to validate fit — user does X, product responds with Y, user reacts — isn't a clean line anymore. It's a distribution. Reading fit signals correctly requires accounting for that variance rather than treating one bad output as an isolated bug or one good output as proof of readiness.
Data Dependency Is Part of the Fit Equation
No SaaS PMF conversation spends much time on the customer's own data quality. An AI PMF conversation has to, because the product's performance is partly outsourced to information the company doesn't control.
Data dependency isn't a footnote in AI product validation — it's a variable that sits alongside price, positioning, and feature set as something that can make or break fit.
A Model Is Only as Good as the Data Feeding It — Fit Can Degrade Without a Single Code Change
This is the part that catches product teams off guard. A team ships a model, watches it perform well in the first quarter, and assumes the hard part is behind them. Then a customer's internal data changes — new product lines, a shift in customer behavior, a merger that scrambles historical records — and the model's outputs start missing the mark. No one touched the code. No one shipped a bad release. The ground underneath simply moved.
This is exactly why product-market fit for AI products can't be treated as a one-time milestone. Fit measured in month one doesn't guarantee fit in month six unless the data pipeline is actively monitored.
Customer Data Quality Becomes a Go/No-Go Factor for AI Product-Market Fit, Not Just an Engineering Concern
Sales and product teams are used to qualifying customers on budget, use case, and company size. AI products add another qualifying question: is this customer's data clean, structured, and sufficient enough for the product to work as promised? A customer with messy, sparse, or inconsistent data can turn a strong product into a poor experience through no fault of the product itself.
Ignoring this question at the sales stage sets up a churn problem at the retention stage. Building it into onboarding — data audits, minimum viable dataset checks, structured intake — protects both the customer relationship and the fit metrics the team is tracking.
Cold-Start Problem: New Customers May Not Have Enough Data for the Product to Perform Well on Day One
Many AI products improve with usage. That's a strength over time and a liability on day one. A new customer with little historical data may see underwhelming results in their first weeks, not because the product is wrong for them, but because the model hasn't had enough signal yet to perform at its best. Teams validating AI product-market fit need to separate "this customer isn't a fit" from "this customer hasn't generated enough data yet." Confusing the two leads to abandoning good customers too early or, worse, redesigning a product that was never actually broken.
Iteration Cost Changes What "Fast Feedback" Means
Lean product methodology runs on speed. Build, measure, learn, repeat, and do it faster than the competition. AI products can still move fast, but the cost structure of each iteration looks nothing like a UI experiment.
Shipping a UI Tweak vs. Retraining or Re-Prompting a Model — Different Cost Curves
Changing a button color or reordering a form takes a developer an afternoon. Retraining a model, rebuilding an evaluation set, or restructuring a prompt chain can take days or weeks, and it carries a real risk of breaking behavior that was previously working well. Teams that apply SaaS-style iteration speed expectations to AI development often end up frustrated, not because the team is slow, but because the underlying cost curve was never comparable in the first place.
Why Rapid Experimentation, a PMF Staple, Is Harder When Every Iteration Touches a Model, Eval Set, or Data Pipeline
Rapid experimentation depends on cheap, reversible changes. AI iterations are rarely both. A prompt change might improve results for one use case and quietly degrade another. A model swap might fix accuracy but introduce latency. Every change tends to ripple outward, which means testing in isolation — the backbone of quick experimentation — has to be replaced with testing against a broader evaluation set before anything reaches production.
This doesn't mean experimentation should slow to a crawl. It means the definition of "fast" has to account for the additional verification work an AI change requires, or the team will ship regressions faster than it ships improvements.
Building Evaluation Infrastructure Before Scaling, Not After
Teams validating traditional software can often get away with building monitoring and analytics after they've found initial traction. AI teams don't have that luxury. Without an evaluation framework — golden datasets, accuracy benchmarks, drift alerts — a team scaling an AI product is scaling blind. They'll see usage numbers climb without knowing whether output quality is climbing, flat, or quietly declining underneath. Building this infrastructure early costs time upfront and saves far more time later, when a quality problem would otherwise surface as a wave of customer complaints instead of a dashboard alert.
Trust Is an Adoption Metric, Not a Nice-to-Have
Trust doesn't usually appear as a line item in a SaaS PMF conversation. It's assumed, then occasionally damaged by an outage or a bug. In AI products, trust behaves less like a background condition and more like a core feature that has to be actively earned and maintained.
Users Tolerate SaaS Bugs; They Abandon AI Products After One Bad or "Hallucinated" Output
A user who hits a broken button in a SaaS tool usually reports it, waits for a fix, and moves on. A user who receives a confidently wrong answer from an AI feature — a fabricated statistic, a miscategorized record, a summary that misses the point entirely — tends to react differently. They don't just note the error. They question every output that came before it and every one that comes after. One bad output can undo dozens of good ones, which makes the tolerance for error in AI products far thinner than in conventional software.
Explainability and Predictability as Fit Signals — Can Users Trust the Output Enough to Act on It?
Fit isn't only about whether the output is accurate. It's about whether the user believes it's accurate enough to act on without double-checking it every time. A product that's 90% accurate but gives users no way to understand why it reached a conclusion will often see lower adoption than a slightly less accurate product that shows its reasoning. Predictability matters here too — users build confidence in a system that behaves consistently, even if that consistency includes known limitations, more than one that occasionally surprises them in either direction.
Trust-Building Mechanisms: Confidence Scores, Human-in-the-Loop, Audit Trails
Product teams have several concrete levers for building trust rather than hoping it develops on its own.
- Confidence scores give users a signal for when to double-check output and when to move forward without hesitation.
- Human-in-the-loop checkpoints let users approve or override AI decisions before they take effect, which builds comfort during early adoption.
- Audit trails show exactly what data or reasoning led to a given output, turning a black box into something a user can inspect.
None of these mechanisms make a model more accurate. What they do is make the relationship between the user and the product transparent enough that accuracy gaps don't automatically become trust gaps.
A Practical Framework for Validating AI Products
With data dependency, iteration cost, and trust all in play, teams need a validation approach that goes beyond a satisfaction survey. The following framework adjusts classic PMF thinking for AI's specific behavior.
Redefine "Retention" — Are Users Returning Because the Model Is Improving With Their Data?
Retention in a SaaS product usually means the workflow still fits. Retention in an AI product should be examined more closely. Are users returning because the product is getting better at serving them specifically, as it learns from their data and usage patterns? Or are they returning out of habit while quietly routing around a feature that isn't delivering? Segmenting retention by improvement trajectory, not just raw return rate, gives a clearer picture of whether validating AI products is actually succeeding.
Track Output Quality Metrics Alongside Usage Metrics
Usage numbers tell a team whether people are showing up. They don't tell a team whether what's being delivered is good. Pairing usage data with output quality metrics — accuracy against a benchmark, drift over time, and override rate, meaning how often users manually correct or reject the AI's output — gives a fuller picture. Rising usage paired with a rising override rate is a warning sign disguised as a growth metric.
Talk to Users About Trust, Not Just Satisfaction
Standard PMF interviews ask about satisfaction and disappointment. AI product interviews should add a direct question about trust: do you double-check this output before acting on it, and if so, how often? The answer reveals whether the product has earned confidence or is merely being tolerated while users quietly verify everything behind the scenes.
Signs You've Actually Found AI Product-Market Fit
A handful of concrete signals separate genuine fit from a product that looks healthy on the surface.
- Users voluntarily feed the system more data because they've seen it pay off in better output.
- Override and correction rates trend downward over time rather than staying flat.
- Usage holds steady or grows across model updates, rather than dropping every time something changes on the backend.
- Customers reference specific outputs in their own decision-making, not just the existence of the feature.
- Support tickets shift from "this is wrong" to "can this do more," signaling accuracy is no longer the primary concern.
FAQ
What's different about product-market fit for AI products vs. traditional software?
Traditional software fit is measured against a stable product. AI product fit has to account for a product that changes on its own through model drift, data shifts, and probabilistic output, which means fit has to be monitored continuously rather than confirmed once.
How do you measure trust in an AI product?
Trust can be measured indirectly through override rates, how often users act on output without double-checking it, and direct interview questions about confidence in the system's decisions, alongside mechanisms like confidence scores and audit trails that make trust easier to build in the first place.
Why does data dependency affect PMF timelines?
Because AI products often need a baseline of customer data to perform well, new customers may show weaker early results not because the product is a poor fit, but because the model hasn't had enough signal yet. This extends the timeline needed to accurately judge fit.
Can you have PMF before your model is fully accurate?
Yes, provided the product is transparent about its current limitations and gives users tools like confidence scores or human review to manage accuracy gaps. Fit depends as much on whether users trust and can work around imperfect output as it does on the accuracy number itself.
Recent Articles
A Practical Roadmap for Your Organization's AI Automation Strategy

The numbers tell a paradoxical story. According to McKinsey's State of AI research, 78% of organizations now use AI in at least one business function, making it one of the fastest-adopted technologies ever tracked. Yet only a small fraction, roughly 5%, qualify as "AI high performers" who see meaningful bottom-line impact from their investments. Gartner predicted that at least 30% of generative AI projects would be abandoned after proof of concept due to poor data quality, inadequate risk controls, escalating costs, or unclear business value, and it forecasts that over 40% of agentic AI projects will be canceled by the end of 2027. An MIT study made headlines claiming as many as 95% of GenAI pilots fail to deliver meaningful results.

The lesson is unambiguous: adopting AI is easy; creating value with AI is hard. The difference between the two is not the sophistication of the models you use. It is the discipline of your strategy.
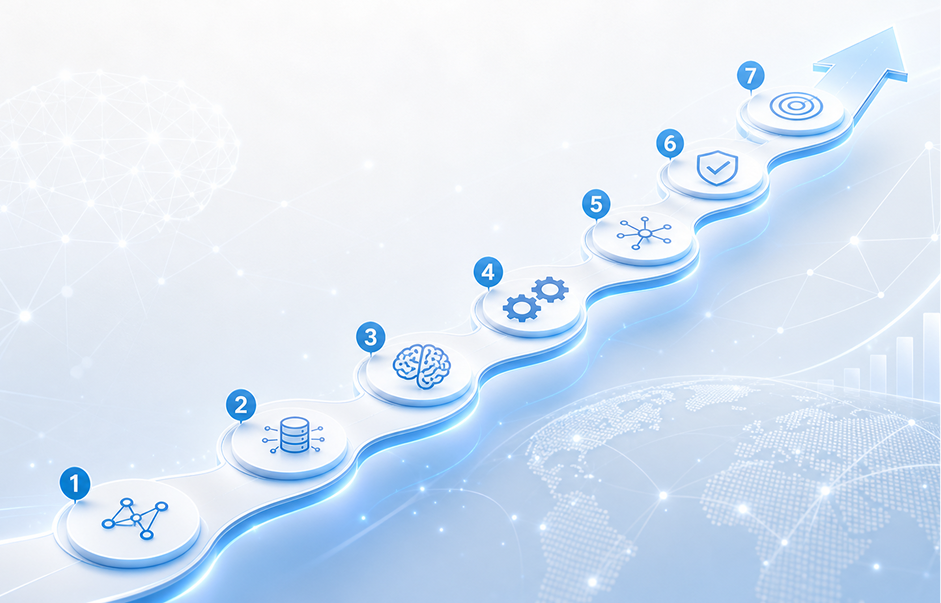
Having spent two decades at the intersection of academic research and applied AI, and having helped deliver 120+ AI projects across 20+ countries through Techtics.ai, I have seen the same pattern repeatedly. Organizations that succeed with AI do not start with technology. They start with a structured assessment of need, value, feasibility, and risk, and they execute through a staged, measurable implementation pipeline. This article lays out that roadmap.

Step 1: Begin with an Honest AI Need Assessment
Every successful AI journey begins with a deceptively simple question: What problem are we actually trying to solve?
Too many AI initiatives are born from FOMO rather than need. The board hears competitors are "doing AI," and a mandate descends without any connection to operational pain points. This is precisely the dynamic Gartner analysts describe when they note that most early agentic AI projects are "driven by hype and often misapplied."
A genuine need assessment examines your organization's value chain end to end and asks:
- Where do we lose the most time, money, or quality today?
- Which decisions are made slowly, inconsistently, or with incomplete information?
- Which processes are repetitive, rule-bound, and data-rich, the natural habitat of automation?
- Where are customers or employees experiencing friction that better intelligence could remove?
The output of this stage is not a technology wishlist. It is a prioritized map of business pains and opportunities, expressed in the language of operations and finance, not in the language of models and algorithms.
Step 2: Identify Potential Use Cases and Cast a Wide Net
With needs mapped, translate them into candidate AI use cases. At this stage, breadth matters more than precision. Industry frameworks such as Gartner's AI use-case prisms are instructive here: whether you operate in insurance, media, utilities, legal practice, B2B sales, digital commerce, smart cities, or automotive, there are typically 15 to 20 well-recognized use cases per industry, from churn prediction and fraud detection to demand forecasting, content personalization, predictive maintenance, lead scoring, and intelligent process automation.
Workshop these with the people who actually run the processes. In our discovery workshops at Techtics, frontline managers routinely surface automation candidates that never appear on the executive radar: the invoice that takes three departments to validate, the phone orders transcribed manually, the blueprints reviewed line by line. These "unglamorous" use cases are often the highest-ROI ones.
Step 3: Evaluate Every Use Case on Two Axes — Business Value and Feasibility
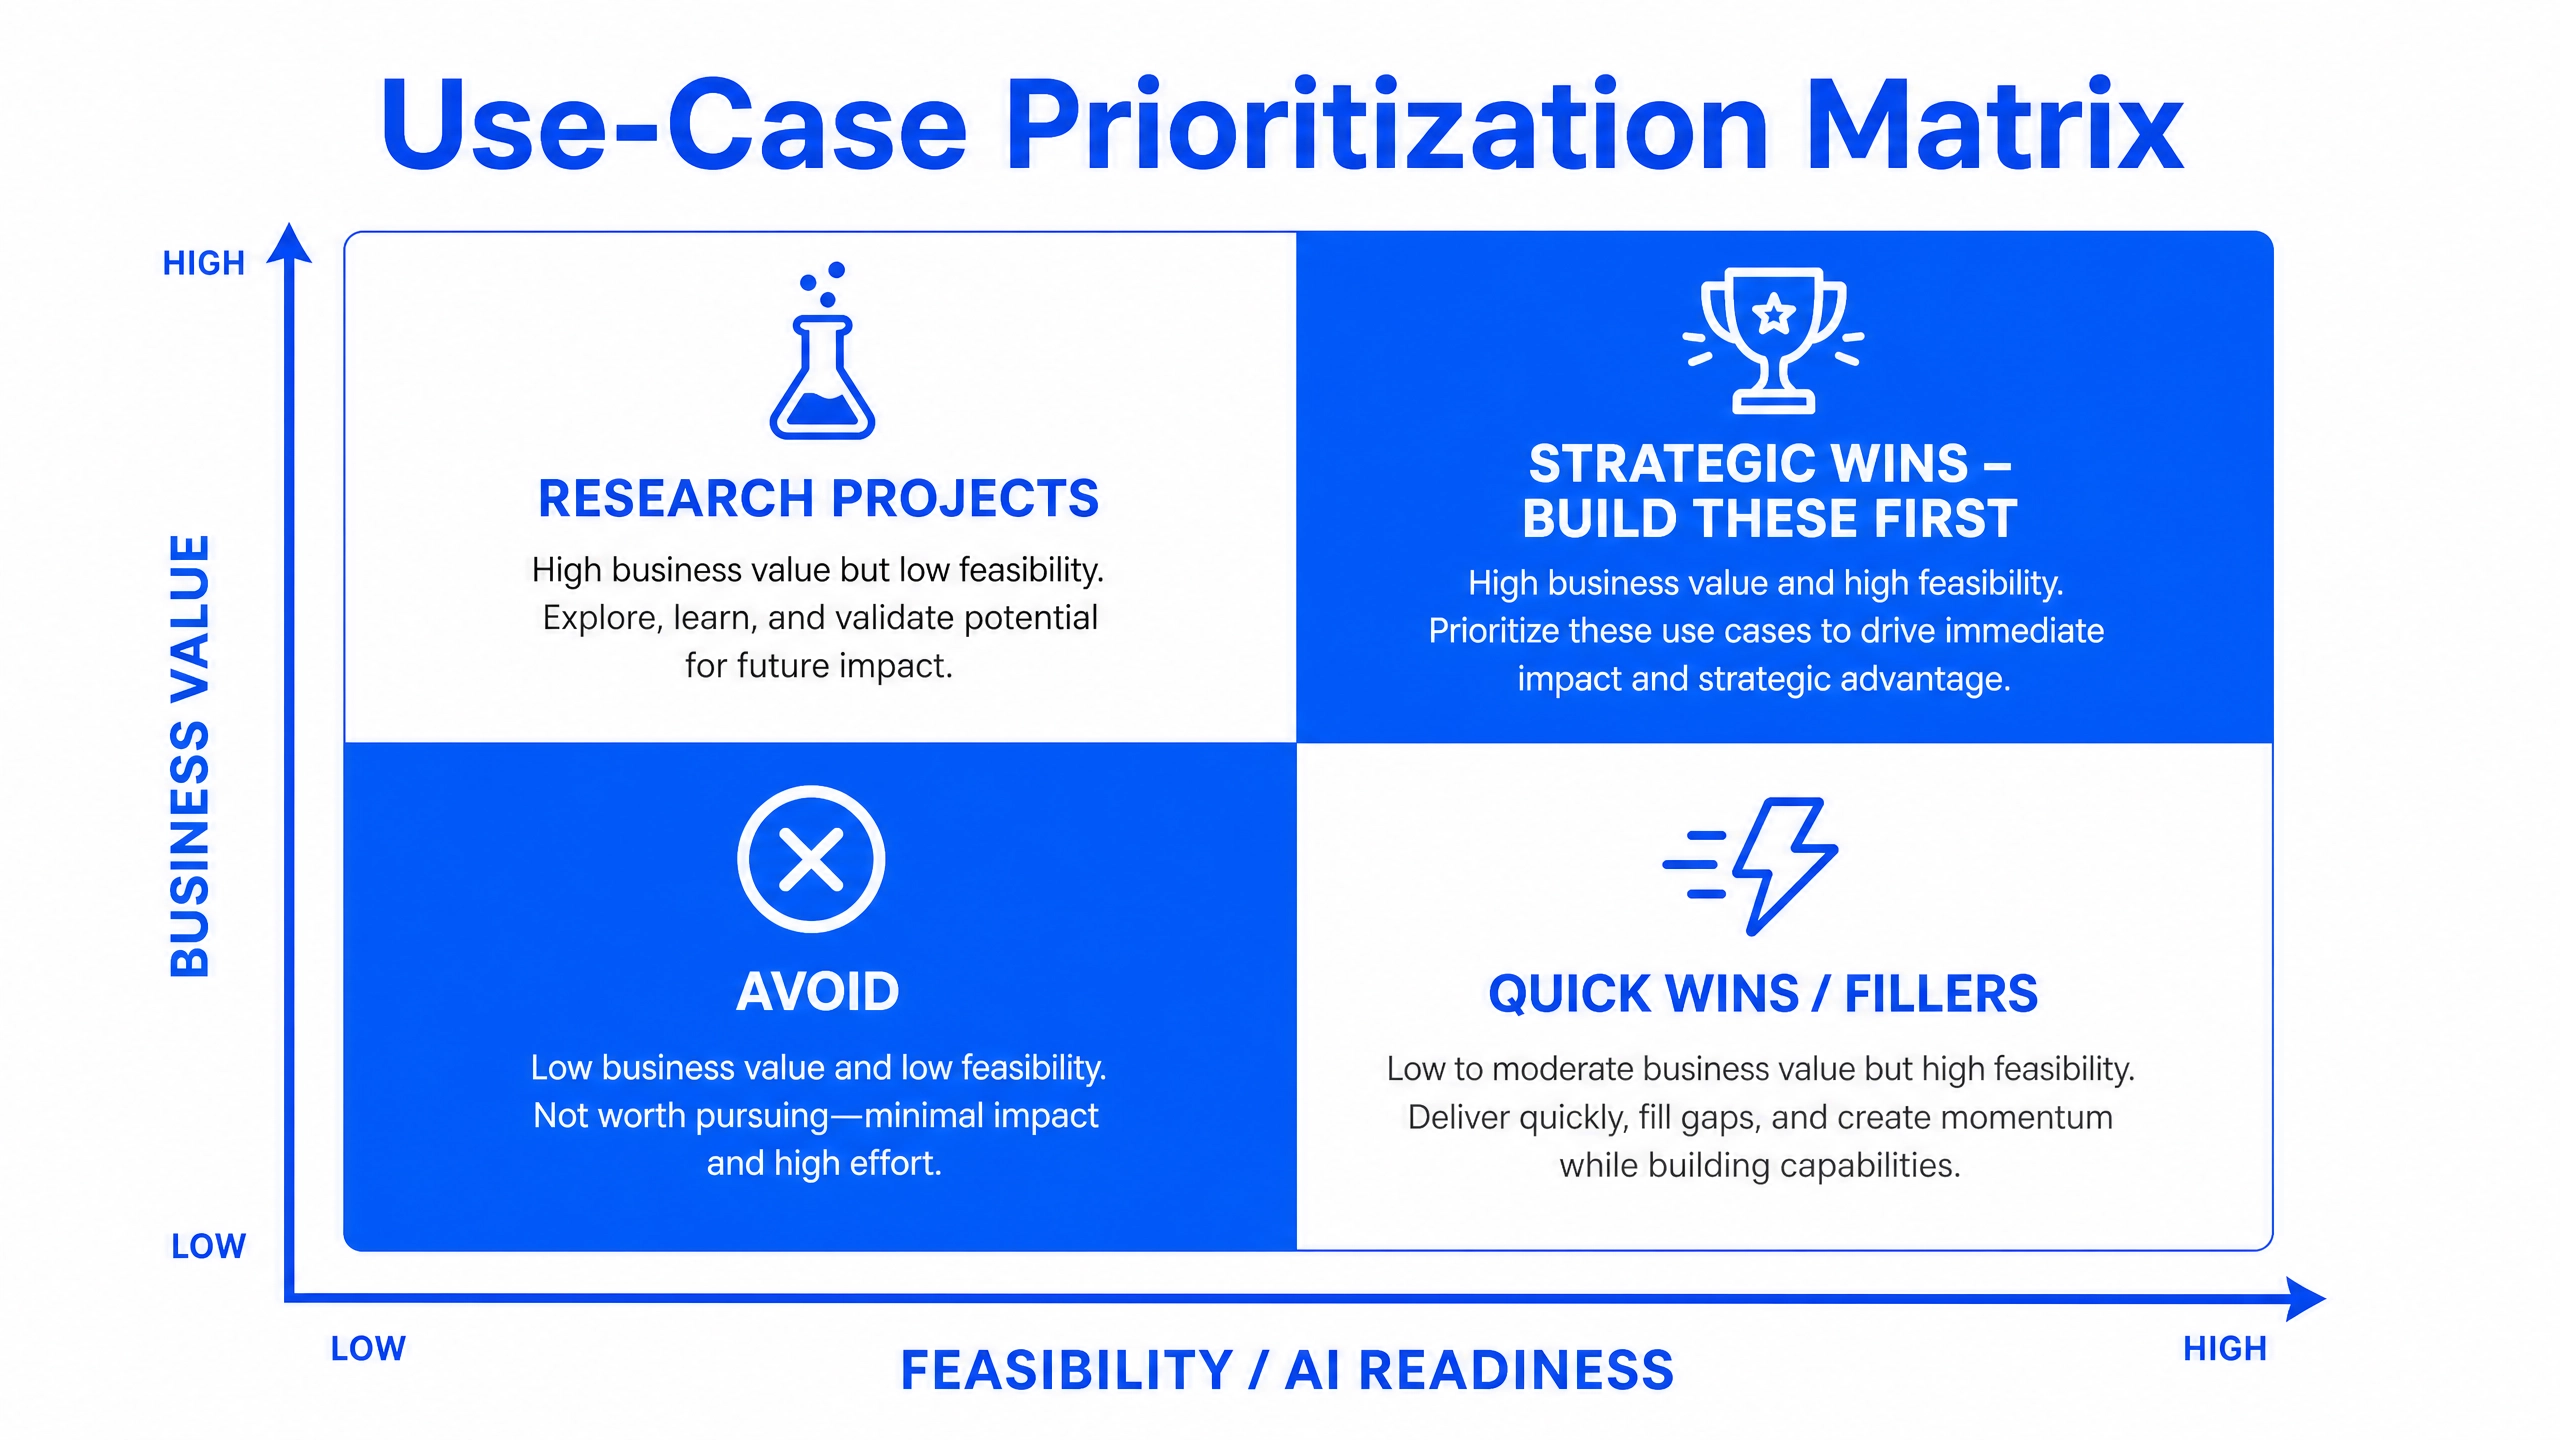
This is the heart of the methodology, and it is where most organizations cut corners. Every candidate use case must be plotted against two independent dimensions: the business value it can create and the feasibility of actually delivering it. A use case that scores high on value but low on feasibility is a research project, not a roadmap item. A use case that is highly feasible but low value is a distraction.

The Business Value Lens
Value addition from AI automation typically flows through four channels: positive financial impact (cost reduction and revenue growth), improved quality (of service, product, and operations), time reduction, and reduced human intervention. In practice, I encourage leadership teams to score each use case against a concrete checklist: process improvement (does it remove steps, handoffs, or rework?), service improvement, HR efficiency, cost reduction, error reduction, quality improvement, offering scale (can you serve 10x volume without 10x headcount?), and revenue increase.
Then perform a hard-nosed revenue-versus-cost analysis. Estimate the total cost of ownership (not just development, but deployment, recurring inference and licensing costs, and maintenance) against quantified annual value. If the payback period exceeds 18 to 24 months under conservative assumptions, deprioritize.
These projections are not fantasy when grounded in real benchmarks. From our own delivery portfolio: a retail computer-vision analytics deployment delivered a 10% increase in customer base, 12% improvement in conversion, and 10% reduction in human resource requirements; a food-and-beverage analytics solution cut food wastage by 10% while optimizing HR deployment by 20%; a power-plant anomaly detection system lifted plant productivity by 12%; and an insurance field-force automation improved productivity by 400%. Realistic, sector-specific reference points like these should anchor your value estimates.
The Feasibility / AI-Readiness Lens
Feasibility is where the 30% to 95% failure statistics are born. Gartner's research attributes most AI project failures to poor data quality and predicts that 60% of AI projects lacking AI-ready data will be abandoned through 2026. Feasibility assessment must therefore go far beyond "can the model be built?" It spans technical, organizational, and adoption readiness:
- Organizational readiness. Are the underlying processes well-defined and stable enough to automate? Is the process digitalized, or does it still live on paper and tribal knowledge? Does the data needed for AI exist, in usable quality and volume, with the rights to use it? Do the relevant stakeholders genuinely intend to change how they work?
- Management readiness. Is top leadership visibly committed, not just approving but sponsoring? Is there financial readiness to fund not only the build, but the run? McKinsey found that, among 25 organizational attributes tested, redesigning workflows and putting senior leaders in critical AI roles had the strongest correlation with realizing EBIT impact from AI. AI delegated to the IT department alone almost always stalls.
- Cost realism. Account for the full cost stack: development cost, deployment and running cost, recurring costs (API and LLM usage, compute, licensing), and maintenance cost. GenAI in particular carries recurring inference costs that can quietly dwarf the initial build, which is one of the principal reasons Gartner cites "escalating costs" as a top abandonment driver.
- Relevant departments' readiness and willingness. Are the stakeholders who own the process open to this change? Do they have, and will they share, the data? Are they willing to adopt the solution and adapt their ways of working around it? A technically perfect system that the operating team quietly works around delivers zero value. BCG's 10-20-70 principle captures this: AI success is roughly 10% algorithms, 20% data and technology, and 70% people, process, and cultural transformation.
- Occurrence frequency. How often is the use case executed? How much time does each execution take, and what does it cost? Automation economics compound with frequency: a process run 10,000 times a month justifies investment that a quarterly process never will. Frequency also determines whether automation scales the business, turning a capacity ceiling into a growth lever.
Step 4: Risk Analysis — The Dimension Everyone Skips
Before selection, every shortlisted use case must pass a structured risk review across at least three dimensions:
- Correctness risk. What happens when the AI is wrong? A product-recommendation error costs a click; an error in invoice validation, medical imaging, or legal document analysis costs real money and trust. Define acceptable error tolerances, human-in-the-loop checkpoints, and fallback procedures before you build. McKinsey's surveys consistently show inaccuracy is the most commonly experienced negative consequence of GenAI use.
- Dependency on external AI (LLMs). Building on third-party foundation models introduces dependencies on pricing changes, model deprecations, rate limits, behavior drift across versions, and vendor lock-in. A sound architecture abstracts the model layer, benchmarks alternatives, and, where volume justifies it, considers fine-tuned or self-hosted models to control recurring cost and continuity risk.
- Data privacy and security. Where does your data go when it enters an AI pipeline? Regulatory regimes (GDPR, HIPAA, sector-specific rules) and customer trust both demand clear answers. This consideration alone often dictates the deployment model (on-premises, private cloud, or hybrid), which in turn reshapes the cost equation.
Step 5: Select and Prioritize
With value, feasibility, and risk scored, selection becomes almost mechanical: choose use cases that sit in the high-value, high-feasibility, manageable-risk quadrant. Then prioritize within that set using three tie-breakers:
- Time-to-value. Early, visible wins build the organizational confidence that funds the harder, bigger wins later.
- Strategic leverage. Does this use case build data assets, infrastructure, or capabilities that make the next use cases cheaper?
- Sponsorship strength. Start where the business owner is most committed.
Resist the temptation to launch five initiatives at once. The organizations stuck in "pilot purgatory" are usually those running many shallow experiments rather than a few deep deployments.
Step 6: Implement Through a Staged Pipeline
For each selected use case, disciplined staging is what separates the 5% who realize value from the rest. The pipeline runs PoC, then MVP, then Pilot, then Scale, then Deployment and Maintenance, with a hard gate between every stage:
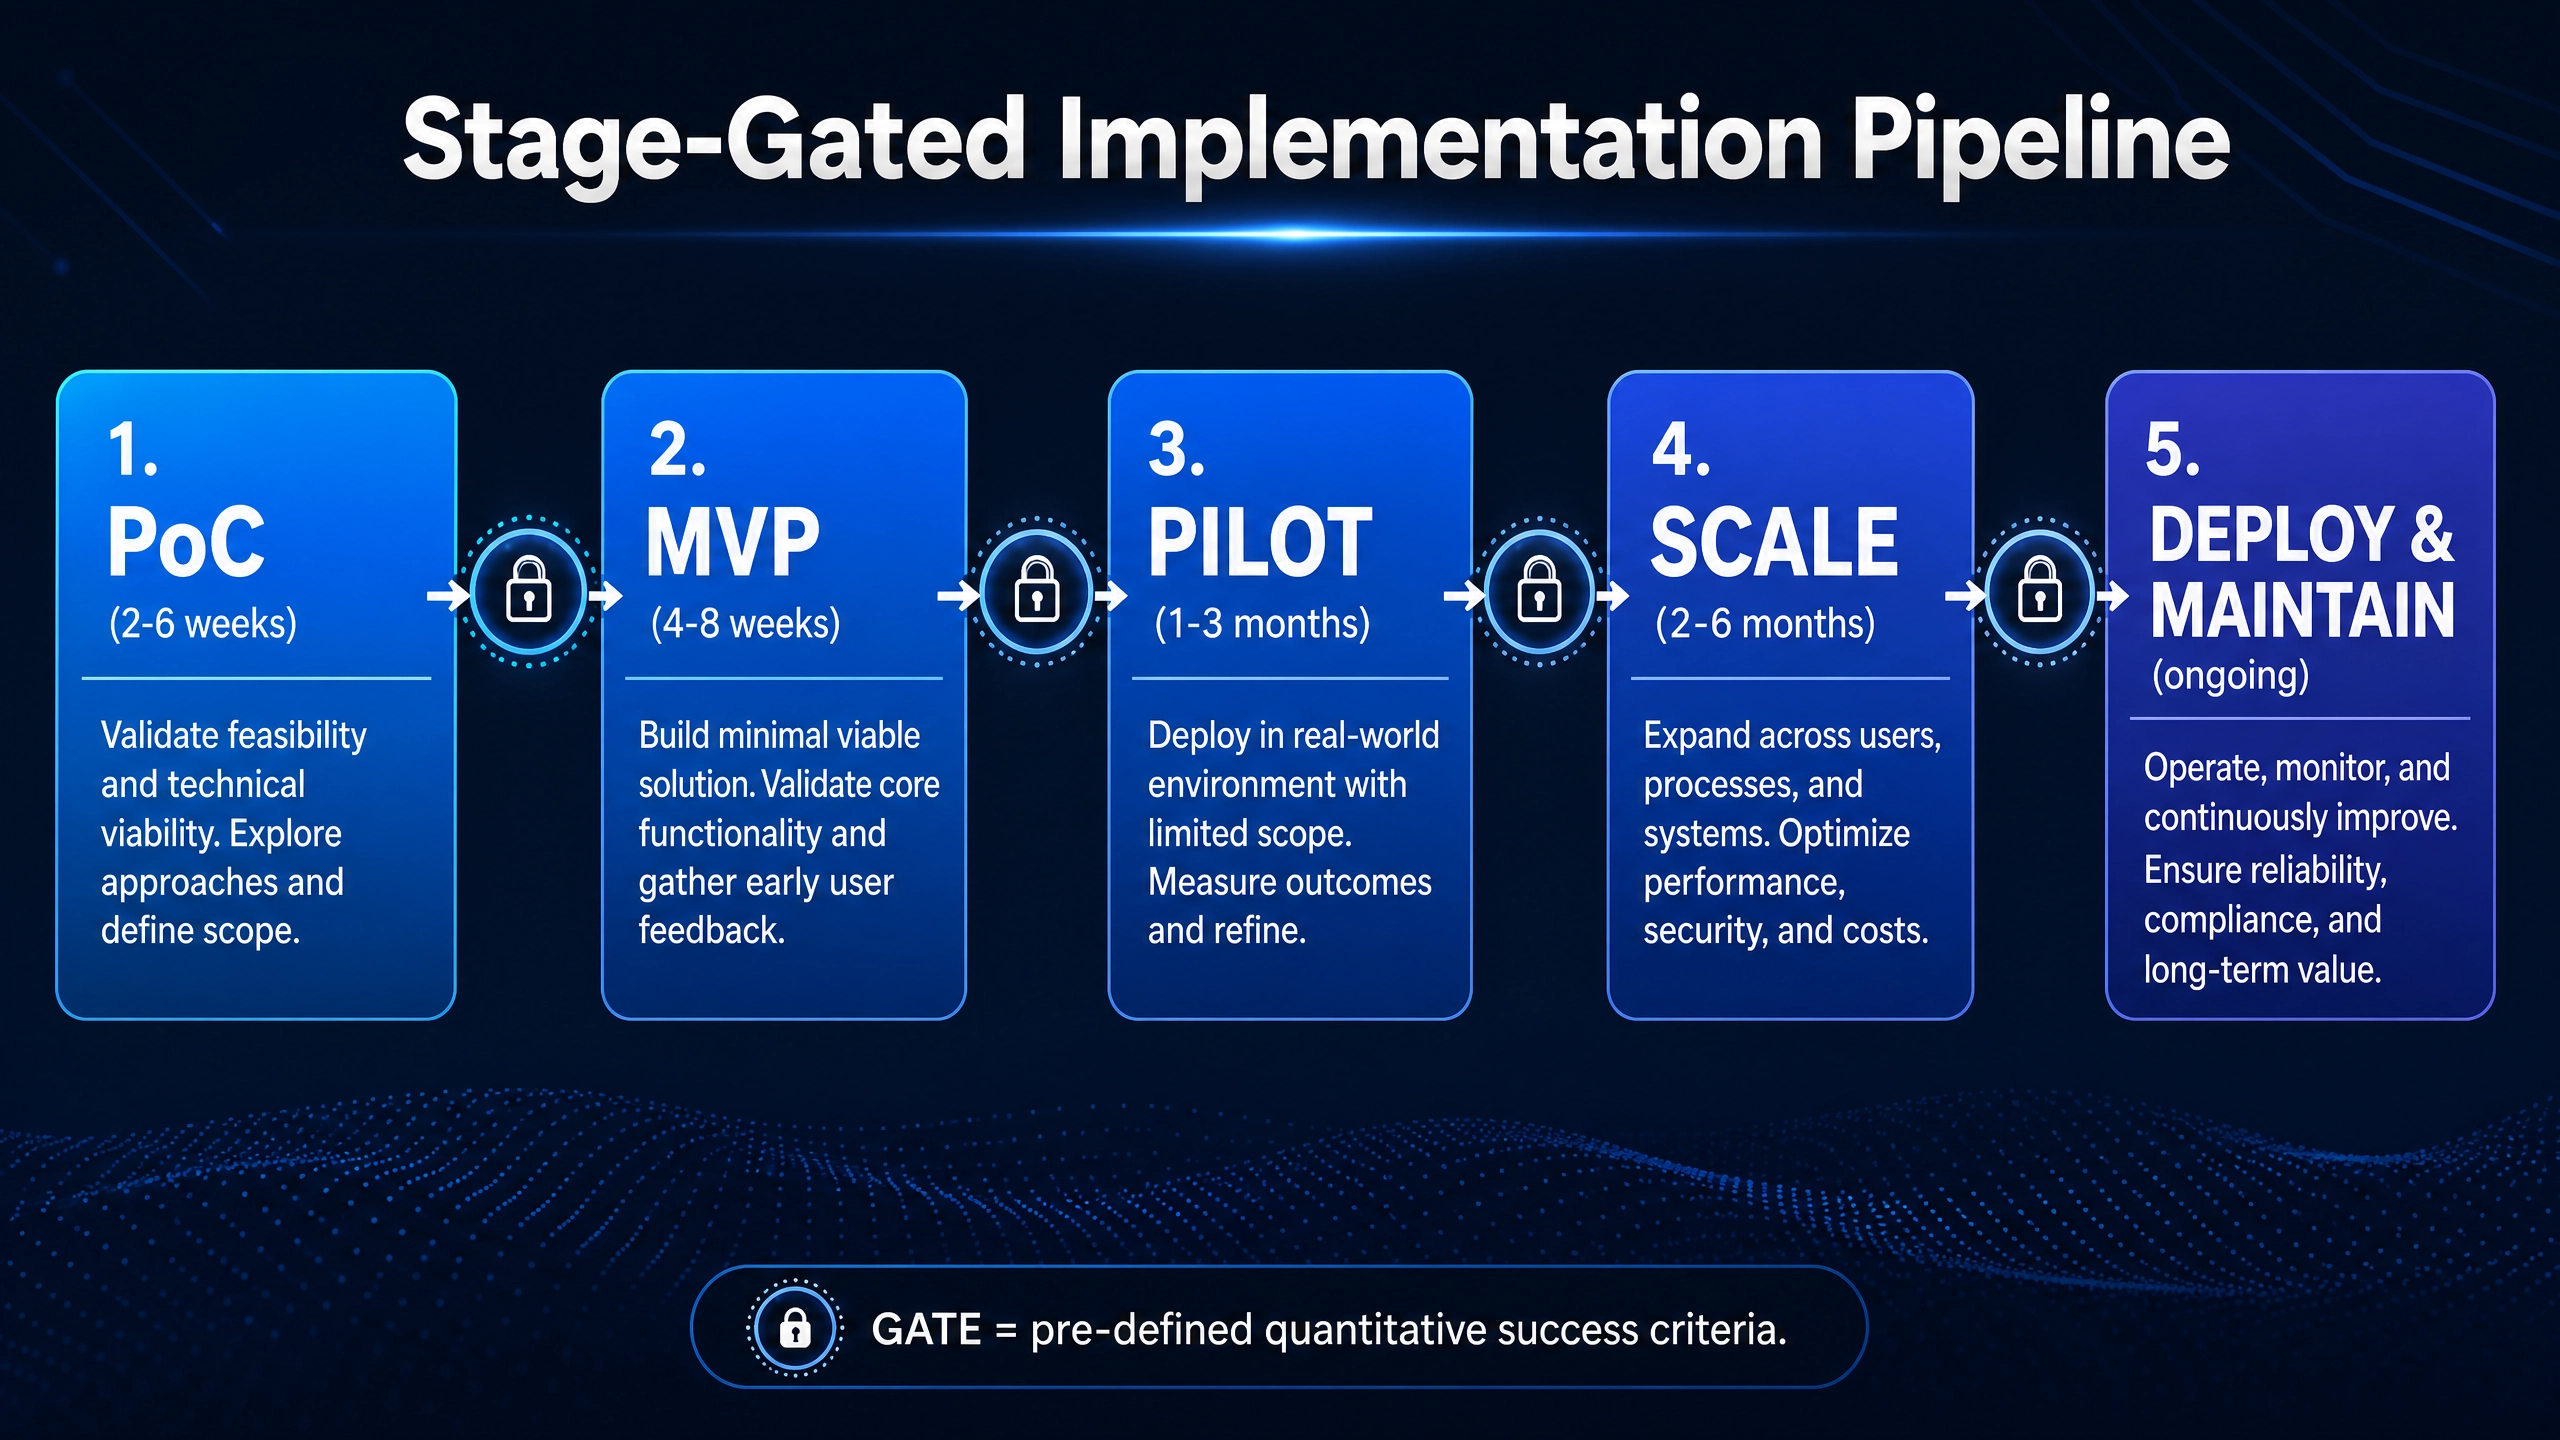
- Proof of Concept (2–6 weeks). Validate the core technical hypothesis on real (not curated) data. The deliverable is evidence, not a product. Define quantitative success criteria upfront, and be willing to kill the project here cheaply. A killed PoC is a success of the methodology, not a failure.
- MVP. Build the minimum end-to-end system a real user can use for a real task, integrated with at least one real upstream and downstream system. This is where integration realities surface.
- Pilot. Run in a live operational environment with a bounded scope: one region, one product line, one team. Measure business KPIs, not model metrics: cycle time, error rate, cost per transaction, user adoption. The pilot is a stress test of organizational readiness as much as of technology.
- Scale. Expand coverage with hardened infrastructure, monitoring, retraining pipelines, and support processes. This is where data drift, edge cases, and load break naive systems. Plan for it from MVP onward, not after.
- Deployment and Maintenance. AI systems are living systems. Models degrade, data distributions shift, business rules change, and LLM providers update their models. Budget ongoing MLOps, monitoring, and periodic revalidation as a permanent operating cost, not an afterthought.
Step 7: Close the Loop — Expected Value vs. Actual Value
The final discipline, and the rarest, is the review assessment: a formal comparison of the value you projected in Step 3 against the value actually realized in production. McKinsey notes that most organizations still lack robust KPIs for their AI initiatives, and that where rigorous tracking exists, value realization rises and risk incidents fall.
Did the 12% productivity lift materialize, or did it stop at 6%, and why? Was the recurring cost in line with the forecast? Did adoption hold after the novelty faded? This review does three things: it keeps everyone honest, it sharpens the assumptions for the next use case, and it converts AI from a faith-based investment into a managed portfolio.
The Very Important Concern: Choosing the Right Technology Partner
Everything above describes what to do. The most consequential decision, however, is often who you do it with, and it deserves direct treatment.
An impactful and sensible AI strategy is rarely developed in isolation. It is best built with a technology partner and consultant who brings relevant, cross-industry delivery experience: someone who has seen where feasibility assessments go wrong, which value estimates prove optimistic, and which architectural decisions come back to haunt you in year two.
Here is the uncomfortable truth about AI economics that inexperienced teams learn expensively: the build cost is only the entry ticket. The development cost, the recurring cost of running the automation, the deployment cost, the maintenance cost, and the selection of the appropriate deployment model (on-premises, cloud, or hybrid) collectively determine whether your AI initiative is an asset or a liability. A GenAI solution that delights in the demo can hemorrhage money in production if every transaction triggers expensive LLM calls that a smarter design would have avoided.
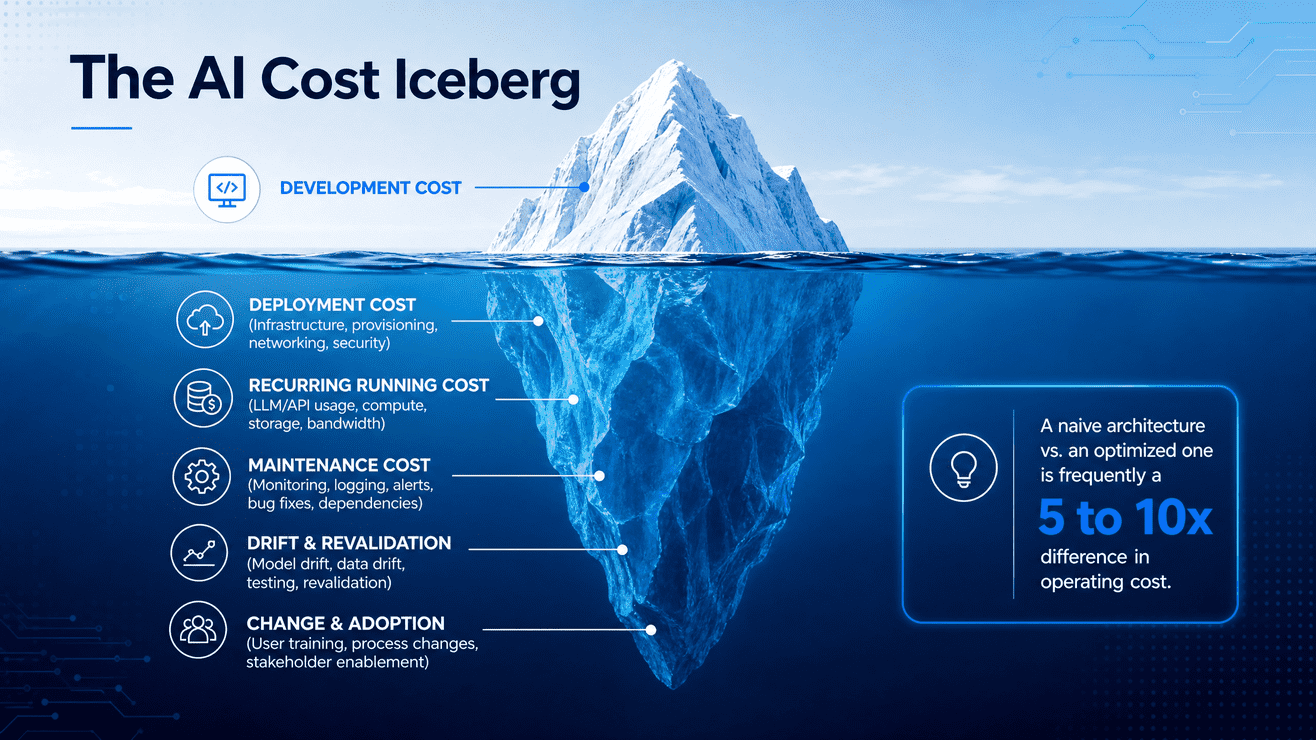
This is where seasoned teams distinguish themselves. They do not merely develop a solution; they develop a cost-effective solution, using smart algorithms, caching strategies, model right-sizing (using a small model where a large one is unnecessary), retrieval architectures, hybrid rule-based/ML designs, and other architectural improvisations that systematically minimize recurring cost. The difference between a naive architecture and an optimized one is frequently 5x to 10x in operating cost, which is the difference between a positive and negative ROI on the same use case.
When evaluating a partner, ask:
- Can they show delivered outcomes with numbers, not just demos?
- Do they have breadth across agentic AI, generative AI, computer vision, and data analytics, so they recommend the right tool rather than the only tool they know?
- Do they lead with discovery and feasibility assessment, or do they jump straight to a quote?
- Can they articulate your total cost of ownership across deployment options before writing a line of code?
- Will they structure delivery as PoC, MVP, Pilot, then Scale, with kill-switches and success criteria at each gate?
Where Techtics.ai Fits In
At Techtics.ai, this methodology is not theory; it is how we work. Founded in 2022 and now 80+ professionals strong, with 10 PhDs, 200+ research publications, and 120+ delivered projects across 20+ countries, we have built our practice around exactly the lifecycle described in this article: discovery workshops (1–2 weeks), proof of concept (2–6 weeks), development and deployment (2–6 months), and go-live support. In practical terms, your PoC can be in your hands within 3 to 4 weeks of our first conversation.
Our delivery spans agentic AI (multi-agent CRM and order automation, AI-driven invoice processing, voice ordering agents, B2B lead-generation automation), generative AI (content automation, AI-powered screening, financial agents, 3D modeling for e-commerce), computer vision (retail analytics, fleet management, aerial surveillance, insurance auto-scan), and data analytics (anomaly detection, forecasting, waste-reduction analytics), across retail, supply chain, education, insurance, food & beverage, cybersecurity, legal, media, and more.
More importantly, we engage as a strategic partner, not a vendor: we will tell you which of your use cases not to build, we will design for your recurring-cost reality and your deployment constraints, and we will measure ourselves against the actual-versus-expected value review, because that is the only metric that matters.
If you are ready to move from AI ambition to AI impact, let's start with a discovery workshop.
Zero-Trust Security Frameworks for AI-First Organizations
For three decades, enterprise security was built around a simple assumption: define a perimeter, secure it, and trust whatever sits inside it. That model made sense when "inside the network" meant employees on company devices, behind a firewall, accessing systems through known applications.
AI-first organizations have quietly broken that assumption. Autonomous agents now query databases, call APIs, trigger workflows, and make decisions without a human clicking anything. The "trusted insider" in today's enterprise might be a piece of software that was prompted into existence an hour ago. Perimeter security has no good answer for that — which is exactly why zero trust has moved from a security buzzword to an operational necessity.
Why Traditional Perimeter Security Fails AI-First Organizations
Perimeter-based security assumes a relatively static, predictable set of actors: known users, known devices, known applications, all operating inside a defined boundary. AI systems violate nearly every part of that assumption.
Agents act with their own credentials, not a human's. An AI agent calling internal APIs, querying a database, or triggering a downstream workflow isn't a person logging in from a recognized laptop — it's a service identity that can be spun up, modified, or duplicated in seconds.
The attack surface is conversational, not just structural. Prompt injection attacks don't exploit a network vulnerability; they exploit the model's interpretation of input text. A malicious instruction embedded in a document, email, or web page can manipulate an agent into taking unauthorized actions, and a firewall has no visibility into that kind of attack at all.
Excessive agency creates new blast radii. When an AI agent is granted broad permissions to "get the job done" — access to multiple systems, the ability to execute code, the ability to send communications — a single compromised or manipulated agent can cause damage across every system it touches, not just the one it was originally deployed for.
Workloads move and scale dynamically. Containers, serverless functions, and orchestrated AI pipelines spin up and tear down constantly, which makes a fixed network perimeter nearly impossible to define in the first place.
None of this means perimeter security is worthless — but it means it's no longer sufficient on its own. Organizations deploying AI agents at scale need a model that doesn't assume safety based on location inside a network boundary.
What Zero Trust Actually Means
Zero trust is often summarized as "never trust, always verify," but the more useful framing for AI-first organizations is this: assume any identity, device, workload, or data request could be compromised, and require continuous verification before granting access — regardless of where the request originates.
This is a meaningful shift from perimeter thinking. Instead of asking "is this inside our network," zero trust asks "is this specific request, from this specific identity, for this specific resource, legitimate right now." That question gets asked every time, not once at login.
The Four Pillars of Zero Trust for AI Systems
A practical zero-trust architecture for AI-first organizations rests on four areas of continuous verification.
Identity
Every human user, service account, and AI agent needs a distinct, verifiable identity — not shared credentials, not generic API keys reused across systems. Agent identities should be issued, rotated, and revoked with the same discipline applied to human accounts, and every action an agent takes should be traceable back to that specific identity.
Device
The infrastructure an AI workload runs on — the container, the virtual machine, the edge device — needs to be verified as a known, compliant environment before it's trusted with sensitive operations. This matters more in AI systems than traditional ones because inference often happens across distributed, ephemeral compute resources rather than a fixed set of company-owned machines.
Workload
Each service, model, and pipeline component should be treated as its own trust boundary, with explicit rules governing what it can call, what data it can access, and what actions it can trigger. Microsegmentation — isolating workloads from each other rather than allowing broad internal network access — limits how far a compromised agent or model can reach.
Data
Data needs classification, encryption, and access policies that travel with it, not protections that depend on where the data happens to sit. When an AI agent retrieves data to answer a query or take an action, that retrieval should be checked against the same access policy a human user would face — not granted automatically because the request came from "inside" the system.
The Unique Attack Surface of Autonomous AI Agents
AI-first organizations face attack vectors that didn't meaningfully exist in pre-AI enterprise environments:
- Prompt injection. Malicious instructions hidden in documents, emails, or retrieved web content can hijack an agent's behavior, redirecting it to leak data or perform unauthorized actions.
- Tool and function-calling abuse. Agents with access to tools — sending emails, executing code, modifying records — can be manipulated into misusing those tools in ways a static application never could be.
- Excessive agency. Granting an agent broad, standing permissions "just in case" turns a narrow task into a wide-open liability if that agent is ever compromised or manipulated.
- Model and data poisoning. Attackers targeting training data or fine-tuning pipelines can introduce subtle behavioral changes that are difficult to detect through conventional security monitoring.
- Insecure agent-to-agent communication. As multi-agent systems become more common, the channels agents use to coordinate with each other become a new, often under-monitored attack surface.
These risks share a common thread: they exploit trust granted by default rather than verified continuously, which is precisely the gap zero trust is designed to close.
Implementing Zero Trust for AI Agents: Practical Steps
Issue scoped, short-lived credentials for every agent. Replace long-lived API keys with credentials that expire quickly and grant access only to the specific resources a given task requires — not standing access to entire systems.
Apply least-privilege access by default. An agent built to summarize support tickets shouldn't also have write access to the billing database. Default to the narrowest permission set that allows the task to function, and expand only with explicit justification.
Microsegment workloads. Isolate AI services from each other and from broader internal networks so that a compromised component can't move laterally to systems it was never meant to touch.
Monitor continuously, not just at access time. Behavioral anomaly detection — flagging when an agent suddenly accesses unusual data, calls unfamiliar tools, or deviates from expected patterns — catches manipulation that a one-time login check would miss entirely.
Classify and encrypt data at the source. Data should carry its access policy with it, so that any agent or service retrieving it is automatically subject to the same rules regardless of how it was queried.
Require human-in-the-loop checkpoints for high-risk actions. Irreversible or high-impact actions — financial transactions, external communications, code deployment — should route through human approval rather than full autonomous execution, at least until an agent's reliability has been extensively validated.
Validate and sanitize inputs to agents. Treat any external content an agent processes — documents, emails, scraped web pages — as potentially adversarial, and build filtering layers that reduce the risk of embedded prompt injection reaching the model unchecked.
Common Mistakes Organizations Make
Many AI-first organizations adopt zero-trust language without changing underlying architecture. A few patterns show up repeatedly:
- Treating zero trust as a product purchase rather than an architectural shift. A single identity tool doesn't deliver zero trust if workloads still communicate over flat, unsegmented networks.
- Granting agents human-equivalent access "to be safe." This inverts least-privilege thinking and creates exactly the broad blast radius zero trust is meant to prevent.
- Verifying identity once at deployment and never again. Continuous verification means re-checking trust at each request, not establishing it once when an agent is first provisioned.
- Ignoring agent-to-agent traffic. As multi-agent architectures grow, the assumption that "internal" agent communication is automatically safe recreates the same blind spot perimeter security had for human users.
Building a Zero-Trust Roadmap for AI Adoption
Organizations don't need to implement every control simultaneously. A practical rollout typically starts with identity — issuing distinct, scoped credentials for every agent and service — followed by microsegmentation of the highest-risk workloads, then continuous monitoring layered on top. Data classification and encryption policies should be established early, since retrofitting them after agents are already in production is significantly harder than building them in from the start.
The organizations managing AI risk well aren't the ones avoiding autonomous agents — they're the ones that have rebuilt their security architecture around the assumption that any identity, device, workload, or data request might be compromised, and verify accordingly, every time.
Talk to Our Team About Securing Your AI Systems
If your organization is deploying autonomous agents faster than your security architecture has evolved to handle them, that gap is worth closing before it becomes an incident. Talk to our team about building a zero-trust framework designed for how AI systems actually operate.
Why Pakistan Needs Its Own AI Stack, Not Just Its Own AI Users
Every country on earth now uses AI. Very few own any of it. That distinction, between being a consumer of artificial intelligence and being a sovereign participant in it, is quickly becoming one of the defining economic and strategic questions of this decade. Pakistan needs to decide, urgently, which side of that line it wants to be on.
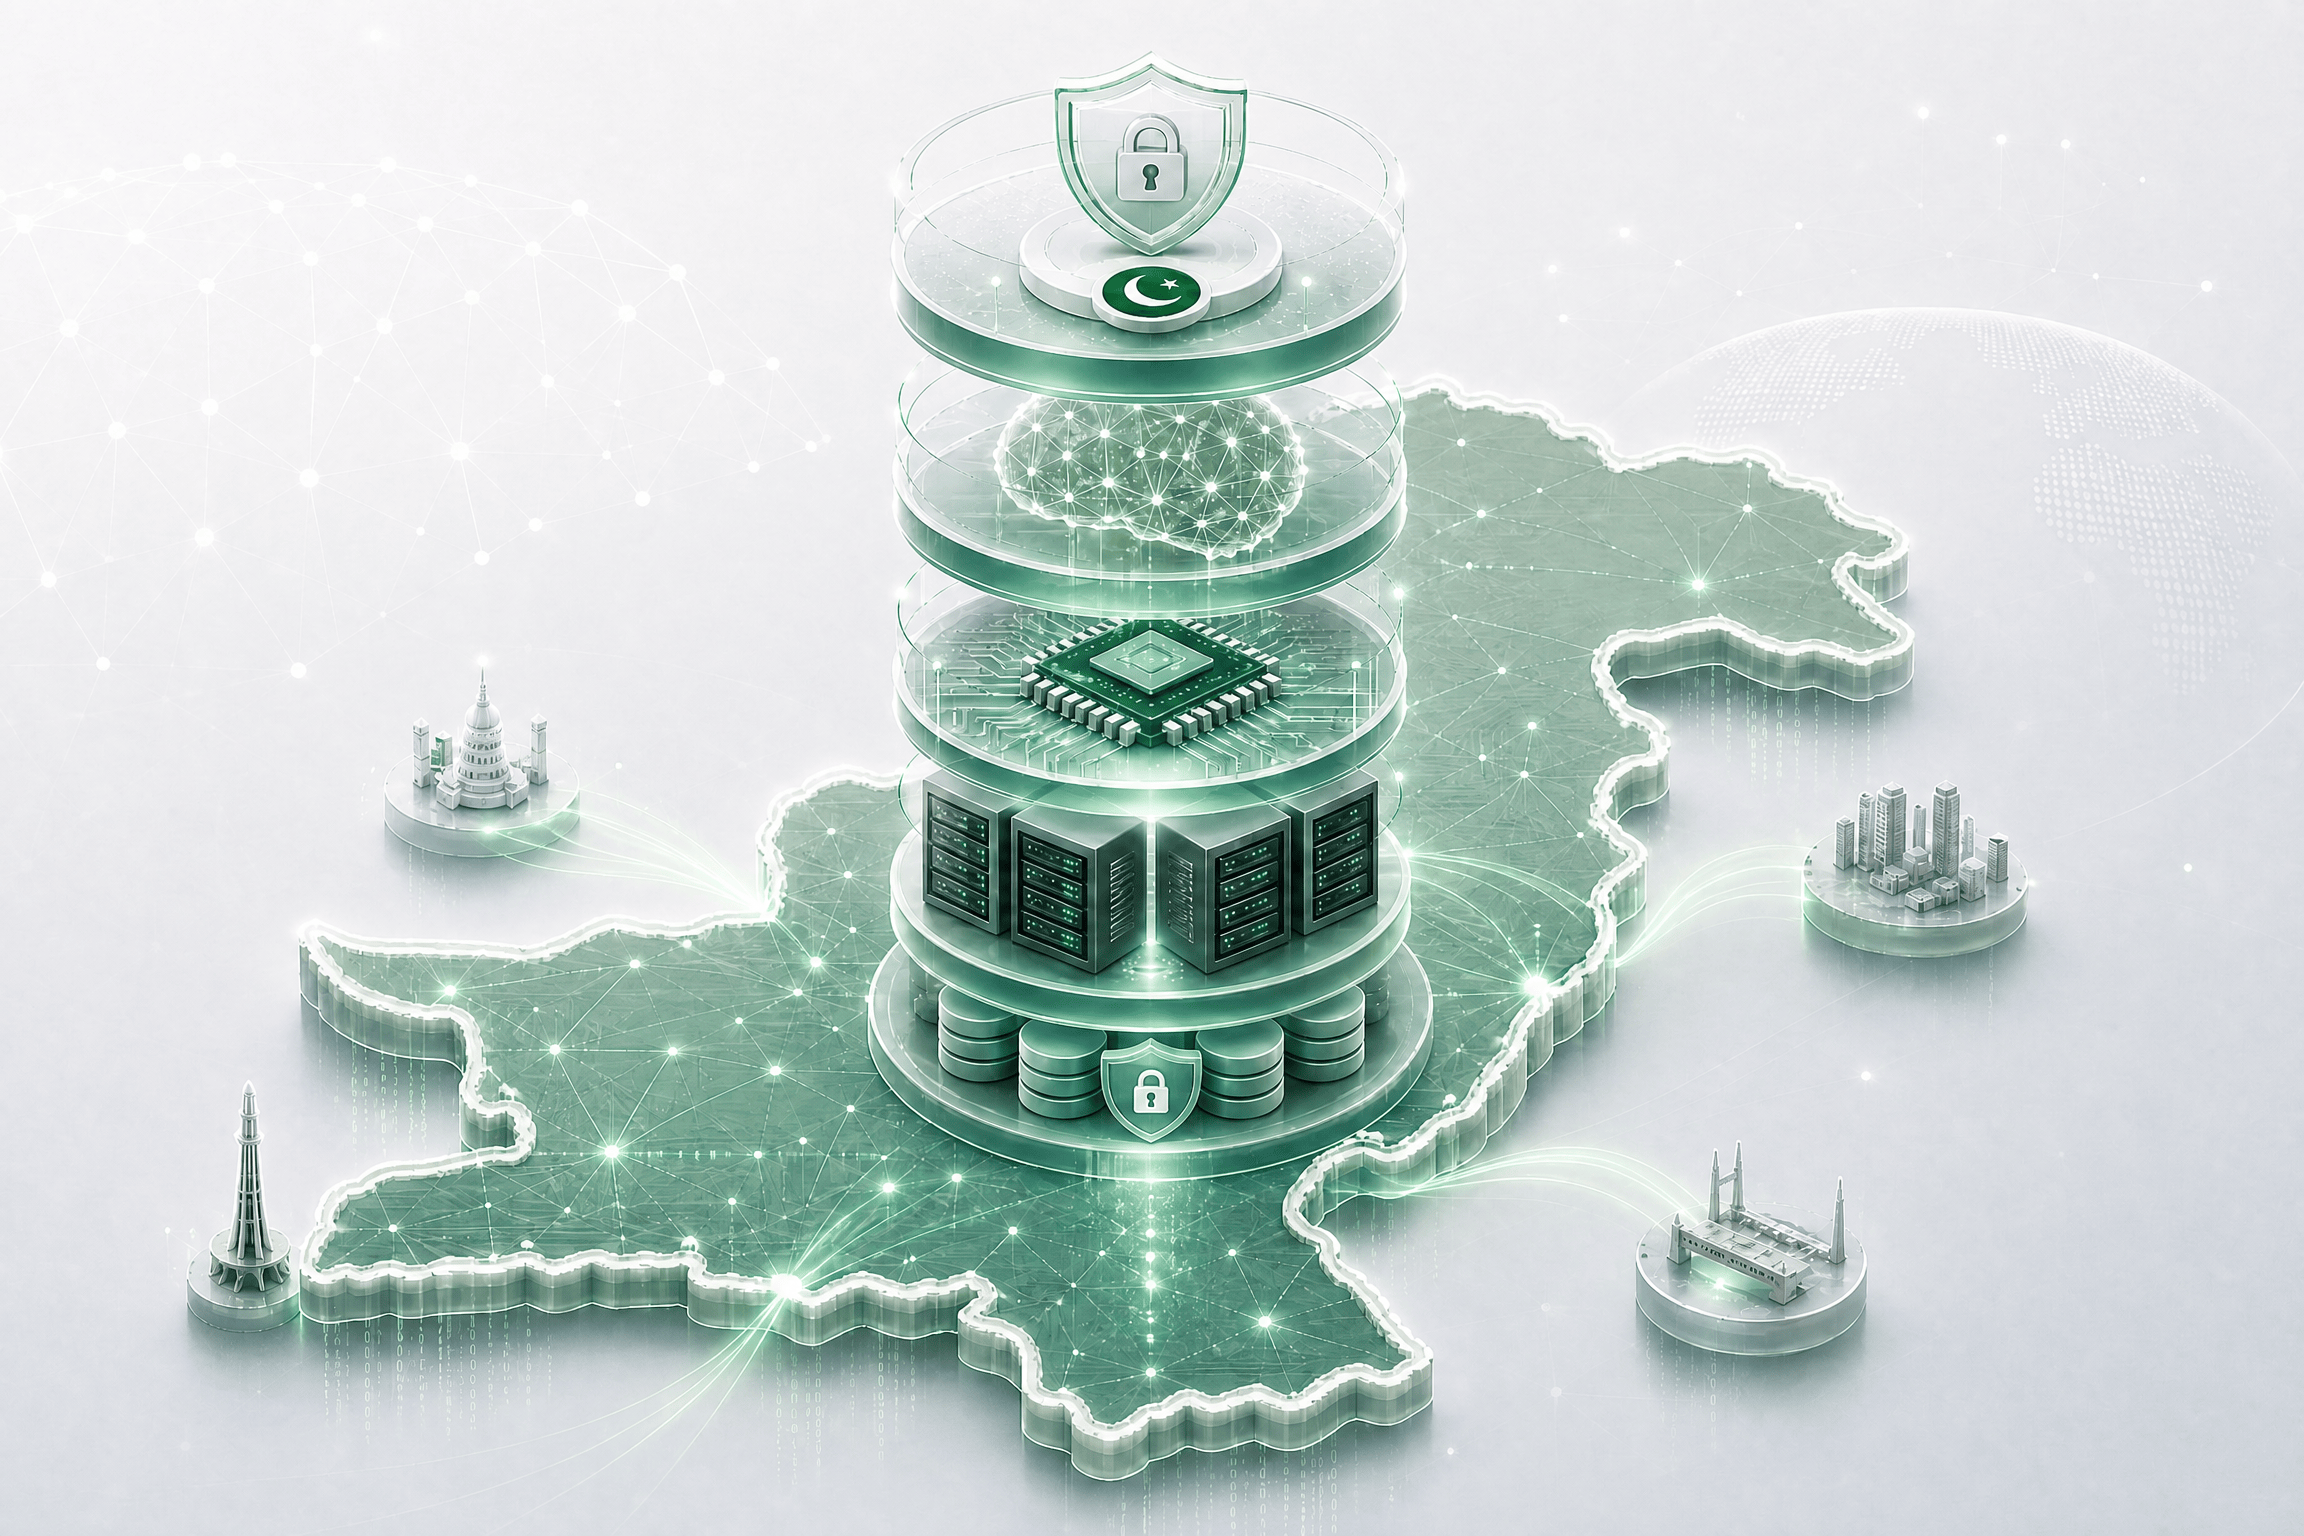
The Five Layers of the AI Stack
To understand what “owning” AI actually means, it helps to break the technology down into five layers, each one more foundational than the last.
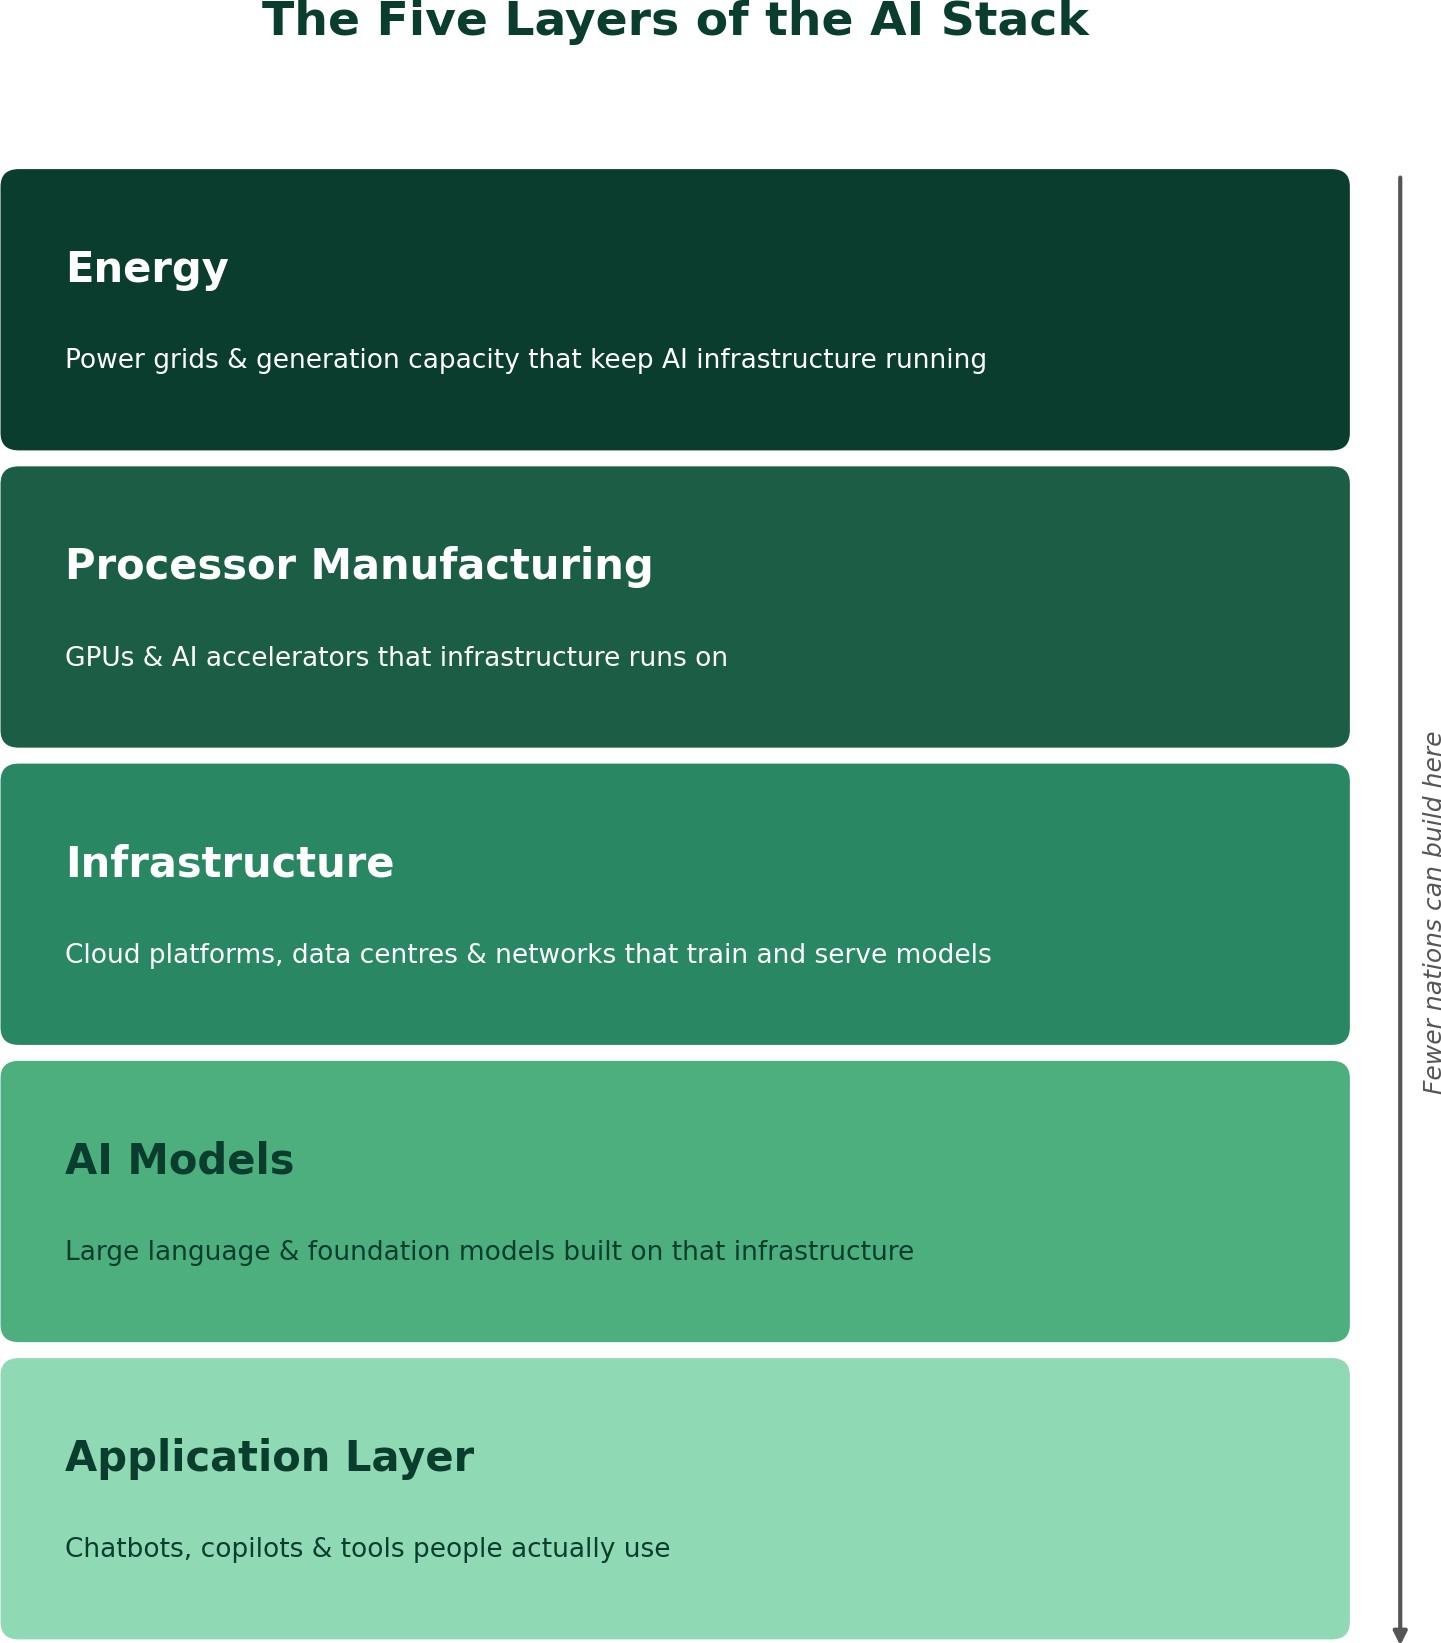
- Application Layer. the chatbots, copilots, and domain tools people actually use.
- AI Models. the large language and foundation models that power those applications.
- Infrastructure. the cloud platforms, data centres, and networks that train and serve those models.
- Processor Manufacturing. the GPUs and AI accelerators that infrastructure runs on.
- Energy. the power grids and generation capacity that keep all of the above running. A single modern AI training cluster can draw as much electricity as a small city.
Almost every country can build at Layer 1. A shrinking number can meaningfully operate at Layer 2 or 3. Only a handful of nations compete at Layers 4 and 5. The realistic question for a country like Pakistan is not “how do we compete at every layer.” It is “where in this stack can we build genuine, defensible capability, and how do we secure fair access to the layers we cannot own outright.”
The Global Race for Sovereign AI
Sovereign AI, the ability of a nation to develop, host, and govern AI on its own infrastructure, in its own languages, over its own data, has become a formal policy goal for dozens of governments.
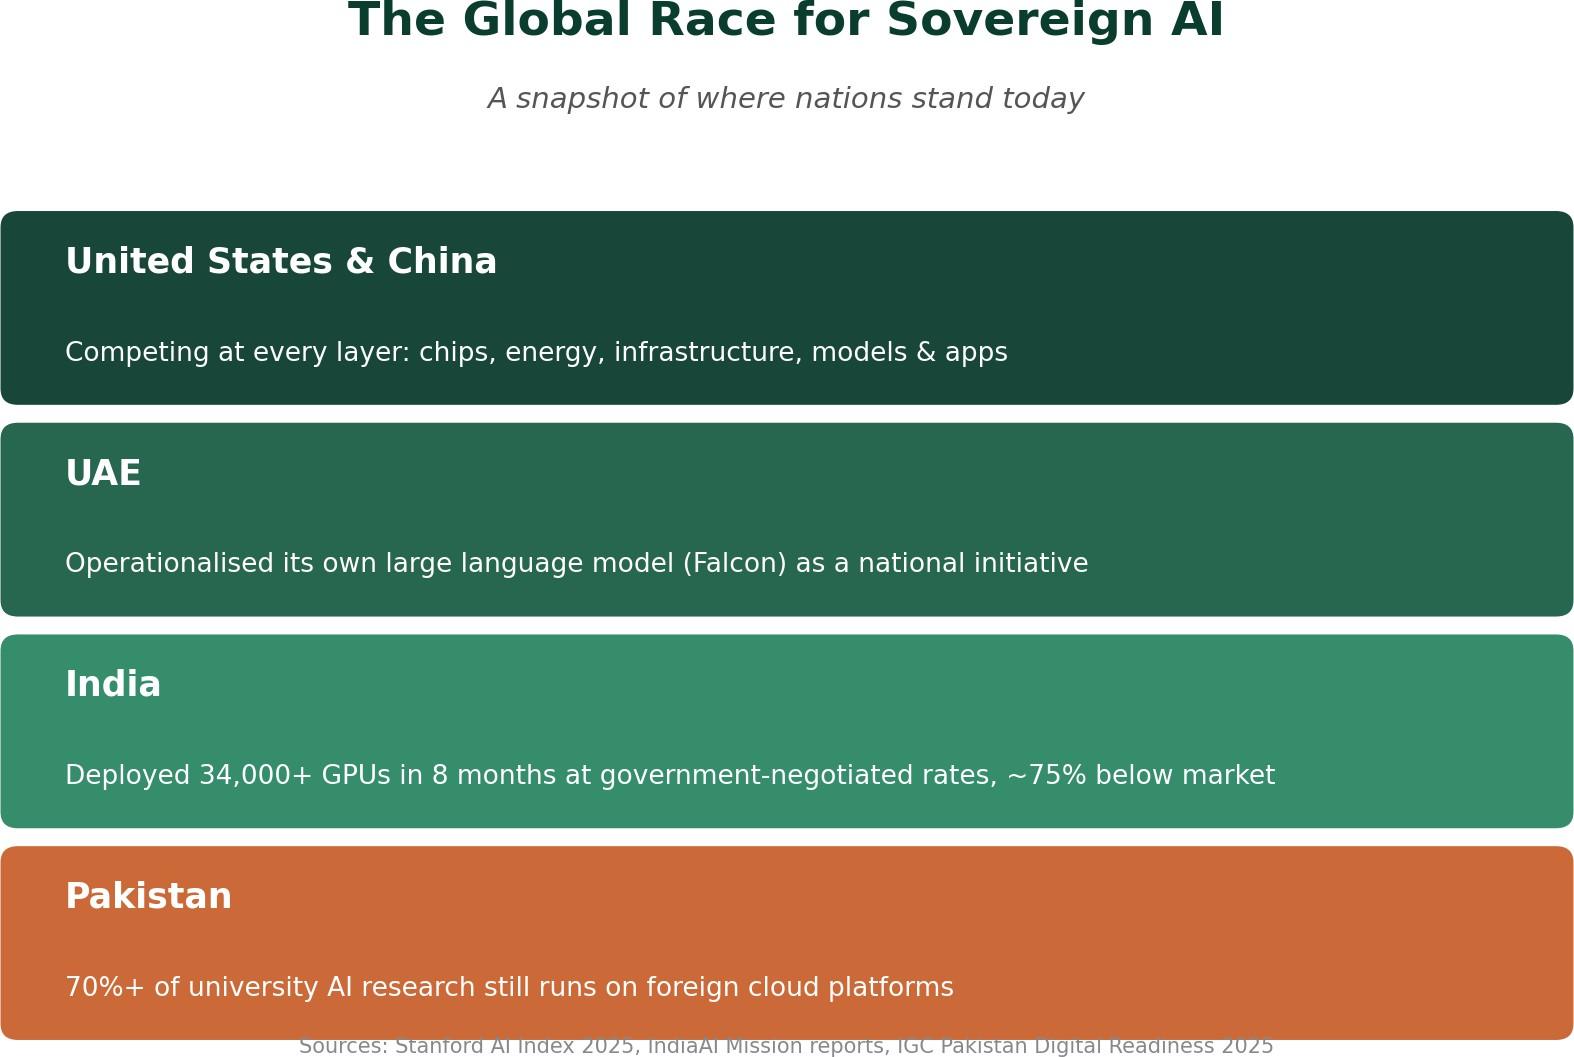
The US and China are racing at every layer of the stack at once. The UAE has operationalised its own Falcon large language model and is positioning itself as a regional AI hub. India's national AI mission deployed over 34,000 H100 and H200 class GPUs in just eight months, backed by a roughly ■10,372 crore (about USD 1.25 billion) government investment, and negotiated public-sector compute rates of about ■67 per GPU-hour, roughly 75% below global market prices. That is a masterclass in how a large, resource-constrained country can still build a public compute layer without trying to out-spend the hyperscalers dollar for dollar. Global corporate AI investment crossed USD 252.3 billion in 2024 alone, up 26% year on year. The gap between countries with a domestic AI stack and those without one is not closing. It is compounding.
Where Pakistan Stands Today
The honest picture is sobering. Pakistan currently ranks 97th out of 133 countries on digital infrastructure, skills, and usage, and 149th out of 197 on openness of government data. Pakistan's own university sector reports over 70% reliance on foreign commercial cloud platforms just to train and experiment with AI models. Sensitive national data, including health records, census data, education
data, and agricultural data, has for years been processed on servers outside Pakistan's jurisdiction, beyond the reach of domestic data protection law. And most large language models in wide use today have little to no meaningful grounding in Urdu or Pakistan's regional languages, which means a large share of the population is effectively invisible to the AI systems increasingly shaping commerce, governance, and public services.
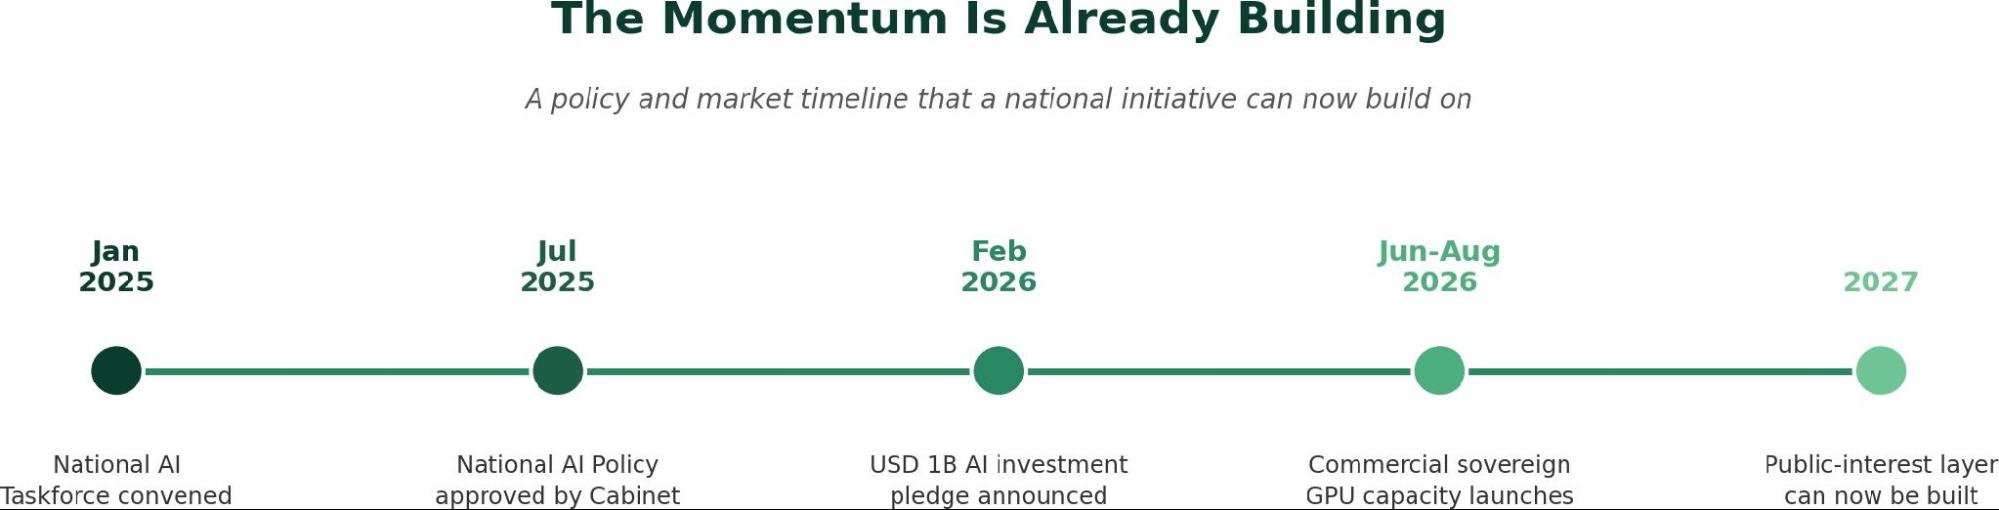
As of mid-2026, Awareness and Readiness remains the only fully operationalised pillar of Pakistan's National AI Policy 2025. The Fifth Pillar, AI Infrastructure, calls explicitly for a national AI compute grid, national and provincial data repositories, and regulatory sandboxes, but the public-interest research, data, and talent layer this pillar envisions remains largely unbuilt, even as commercial GPU hosting has begun to emerge.
Why Sovereign AI Isn't Optional
This matters for four concrete reasons.
- Economics. Research suggests AI adoption could add up to 12% to Pakistan's GDP and create over 3.5 million jobs by 2030, but only if it is backed by genuine domestic capability and not just imported tools.
- Security and data sovereignty. A nation that cannot train or host its own models on its own sensitive data stays permanently dependent on foreign infrastructure for decisions that affect its citizens.
- Linguistic and social inclusion. AI that doesn't understand Urdu, Punjabi, Sindhi, Pashto, or Balochi simply doesn't work for most Pakistanis, no matter how capable the underlying model is.
- Economic leakage. Every dollar spent on foreign AI APIs and foreign cloud compute is a dollar that never builds local capacity, local jobs, or local intellectual property.
The Encouraging Part: Pakistan Isn't Starting From Zero
The good news is that real groundwork already exists, and the eighteen months to mid-2026 in particular saw fast movement, on both the policy and the commercial hardware side.
A premier government-backed AI research centre already operates nine laboratories across six universities and has shipped over 220 AI products spanning smart cities, precision agriculture, healthcare, and judiciary applications. A leading university's language engineering lab has spent decades building foundational Urdu NLP toolkits, morphological analysers, and speech corpora. A telecom operator, a major university, and the national IT board have jointly begun work on the country's first locally hosted large language model. A philanthropically funded AI hub, backed by a major international foundation grant, has just launched with a flagship focus on maternal and child health. A national open data portal has published over 1,100 public datasets across 14 sectors.
Most importantly, Pakistan's private sector has moved fast on the hardware side. Sky47's Karakoram-01 facility in Islamabad, an 8.5 MW Tier III/IV carrier-neutral sovereign cloud data centre, was inaugurated by the Prime Minister in July 2026, with a second facility in Karachi and a third city already planned. Data Vault Pakistan, based in Karachi, launched the country's first solar-powered GPU-as-a-Service data centre in mid-2025 and now runs a three-year sovereign AI services contract with the National Telecommunication Corporation for federal government workloads. Indus Cloud, run by the Master Group, brought online Pakistan's first Cisco AI GPU cluster built on NVIDIA H200 chips in August 2026, the first availability of brand-new H200 hardware on Pakistani soil. GPU prices have also fallen sharply, from over USD 25,000 to roughly USD 8,000 to 15,000 per unit, lowering the cost of building serious compute capacity. For the first time, the hardware half of the sovereign AI equation is genuinely being built on Pakistani soil.
The Problem: Fragmentation, Not Absence
These efforts are scattered. They are concentrated in one or two cities, running independently of one another, with no shared dataset repository, no common governance framework, and no deliberate mechanism connecting academia, government, and the private compute providers now coming online.
Commercial GPU hosting solves the hardware half of the problem. It does not, on its own, produce local-language models, curated public-sector datasets, or a pipeline of trained AI talent, because no commercial provider is commercially incentivised to build any of that. What Pakistan needs now is not another isolated initiative. It needs deliberate diversification: a footprint that spans provinces rather than a single city, that formally binds academia and industry together instead of leaving them to collaborate informally, and that is organised as a consortium-led national initiative rather than a single institution's project, so the effort survives beyond any one team, campus, or funding cycle.
The Way Forward: A Layered Build, Not a Single Product
The most credible path forward mirrors the five-layer stack itself, built from the bottom up, and at a scale that is modest by global standards but catalytic for a public-interest layer: a federated academic compute grid of several hundred GPUs, paired with negotiated access to the country's much larger new commercial capacity, can be enough to make the rest of the stack possible.
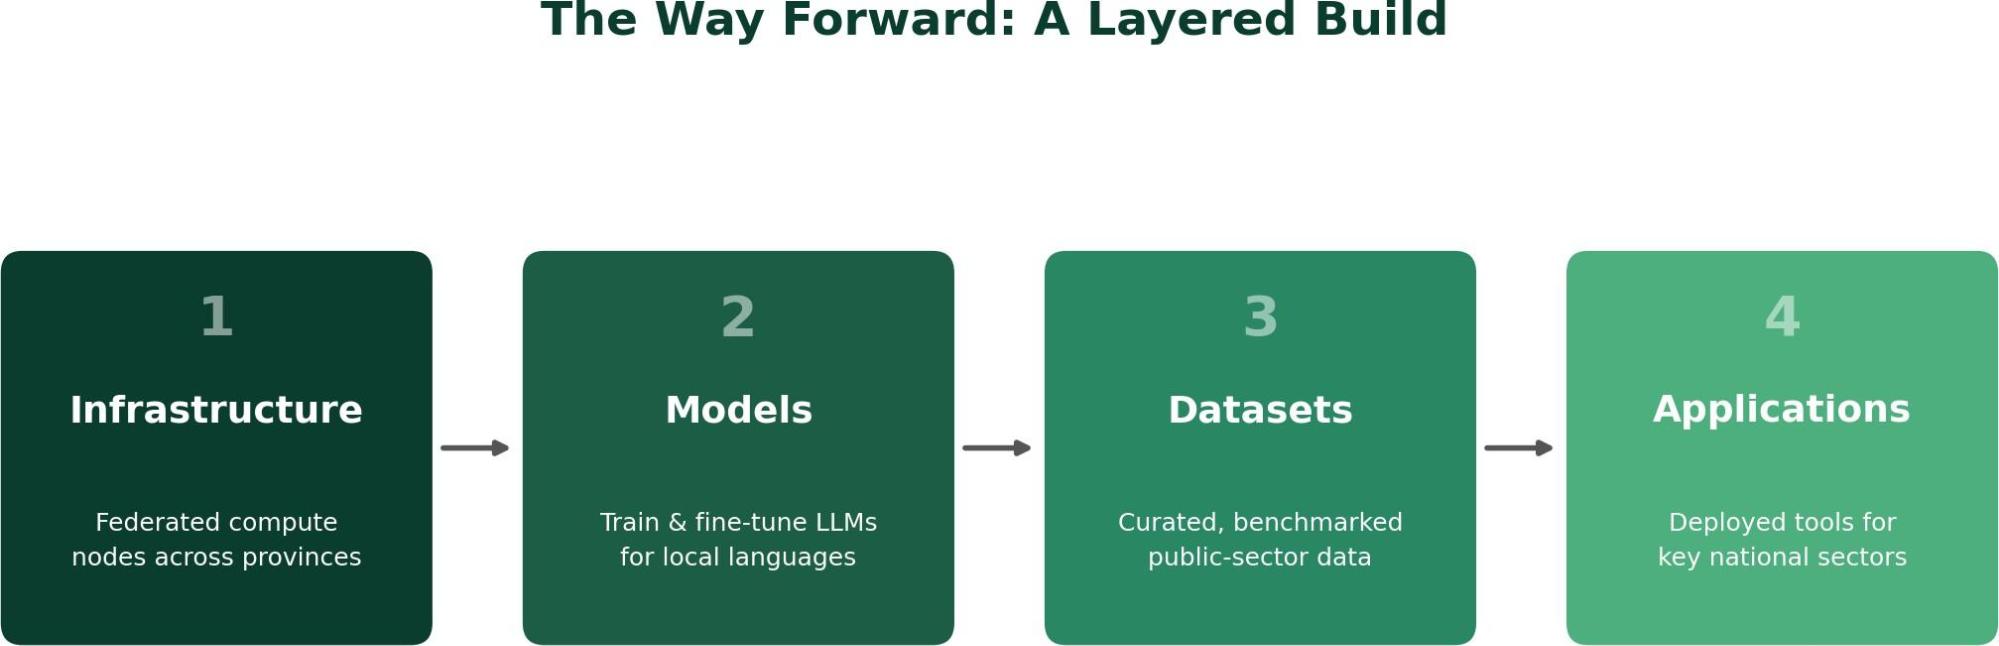
- Infrastructure first. federated, GPU-equipped compute nodes hosted across multiple universities in different provinces, paired with negotiated public-sector access to the country's new commercial GPU capacity for burst-scale training, so the public sector rents capacity intelligently instead of duplicating it.
- Models next. training and fine-tuning large language models covering six or more of Pakistan's languages, built on infrastructure the public sector actually controls, with open interfaces so researchers and startups can customise and extend them.
- Datasets. a secure, benchmarked, and versioned national repository of dozens of public-sector datasets across health, agriculture, water, climate, education, and governance, curated with proper academic custodianship and data protection compliance. This is the fuel without which no model, however well trained, can serve real national needs.
- Applications. tools piloted and deployed for both domestic impact and export revenue, so the stack ultimately serves citizens, industry, and international markets alike.
Where This Kind of Effort Can Deliver Impact
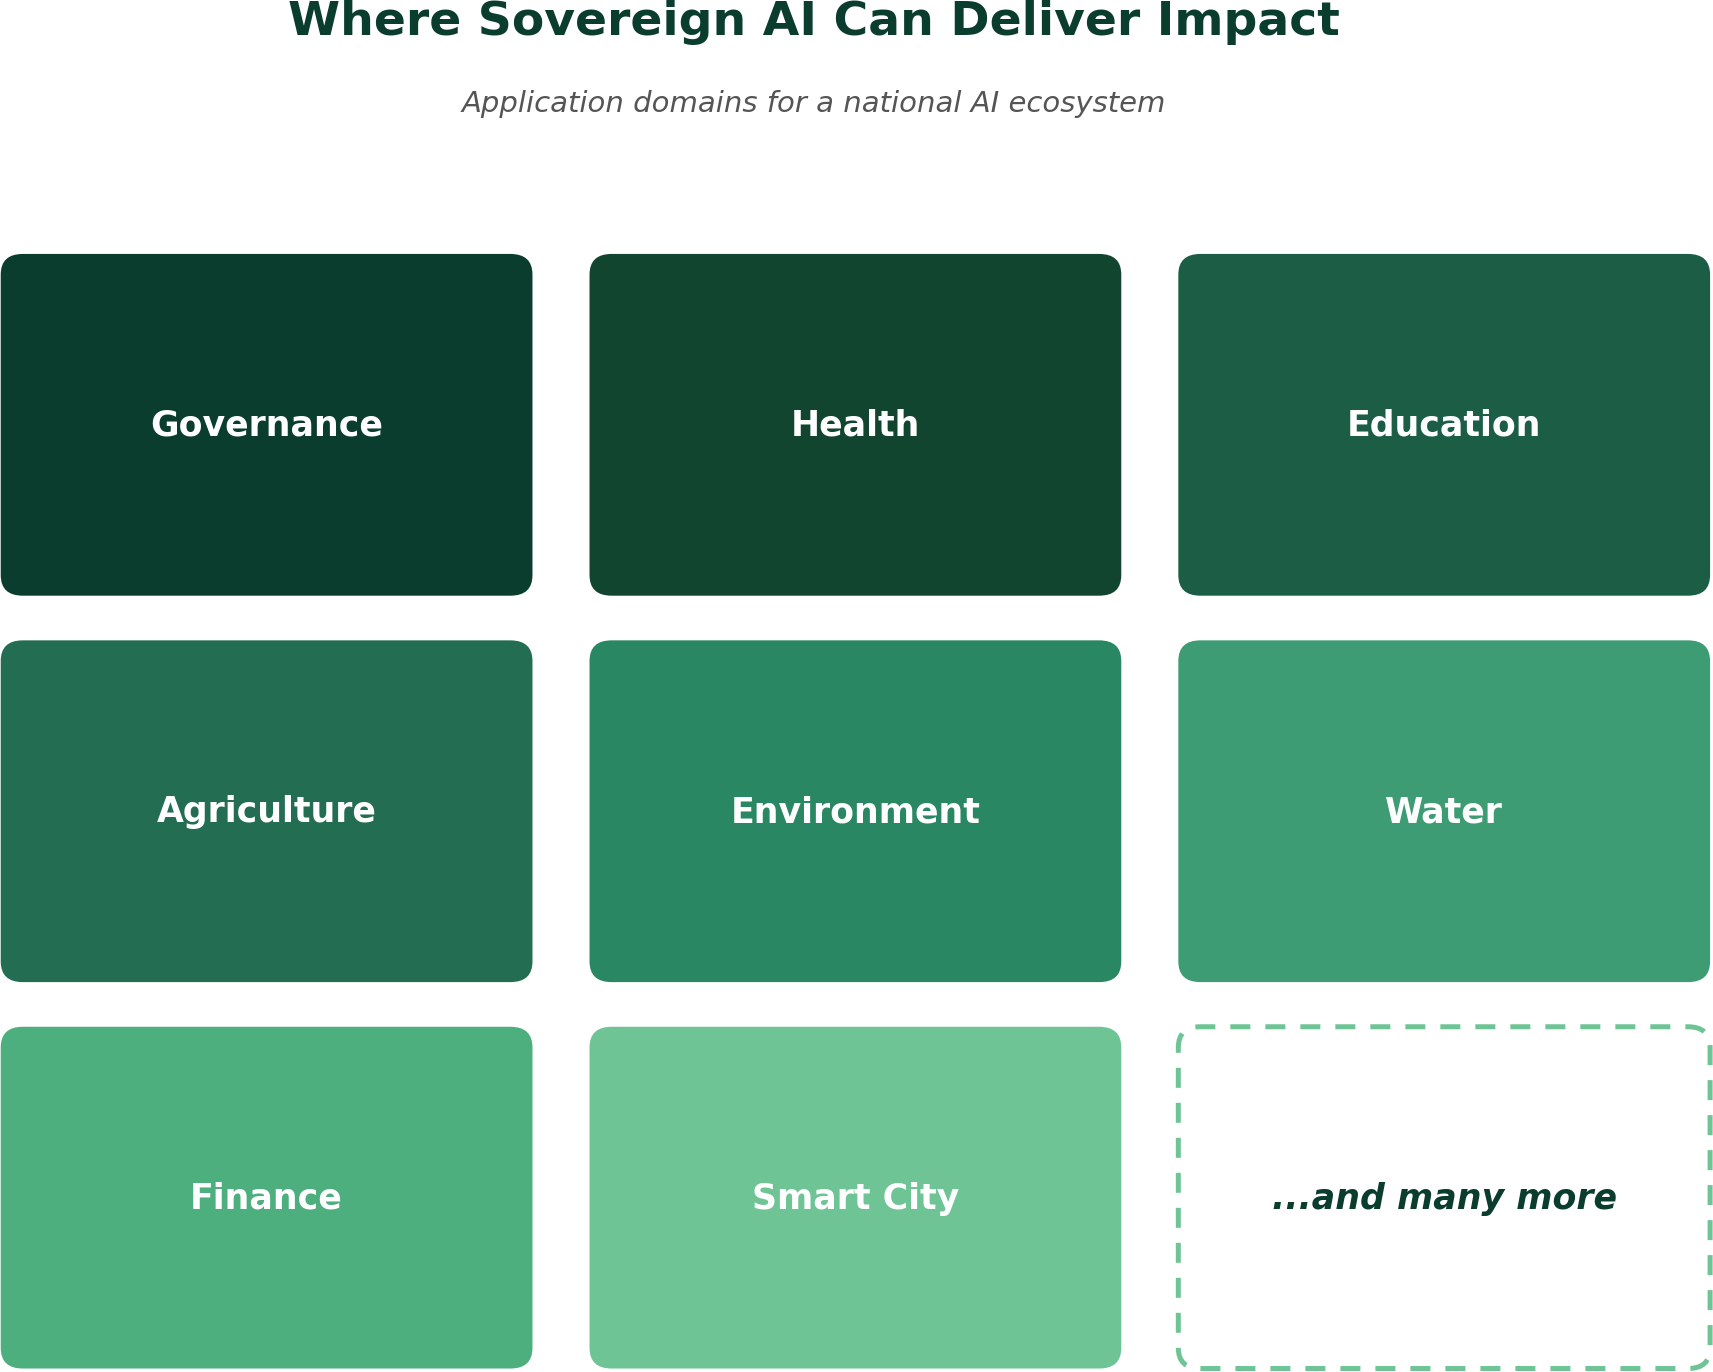
A national AI ecosystem built this way has clear application domains to aim at, each grounded in concrete, piloted use cases rather than abstract ambition, and this list is only a starting point:
- Governance. multilingual citizen-query assistants for e-governance portals, and smarter, data-driven policymaking.
- Health. multilingual AI-assisted triage and diagnostic support for frontline health workers in underserved districts.
- Education. adaptive, native-language AI tutors aimed at closing foundational literacy and numeracy gaps in rural schools.
- Agriculture. voice-enabled crop advisory and pest and disease identification for smallholder farmers in their own languages.
- Environment. climate risk mapping, land-use analysis, and remote-sensing tools built on local geospatial data.
- Water. flood forecasting and groundwater monitoring for water-stressed districts, grounded in local hydrological data.
- Finance. multilingual financial inclusion tools, credit-risk scoring, and fraud detection built for underserved and unbanked communities.
- Smart city. traffic and utility management, urban planning analytics, and municipal service delivery tools for growing urban centres.
- And many more. accessibility and inclusion tools, judiciary, media, and other domains are all within reach once the underlying models, datasets, and talent exist.
The Scale of Potential Impact
Done well, and funded at a modest scale (comparable initiatives elsewhere have been costed in the USD 10 to 15 million range over three years), an initiative structured this way could plausibly deliver the following by 2029 to 2031:
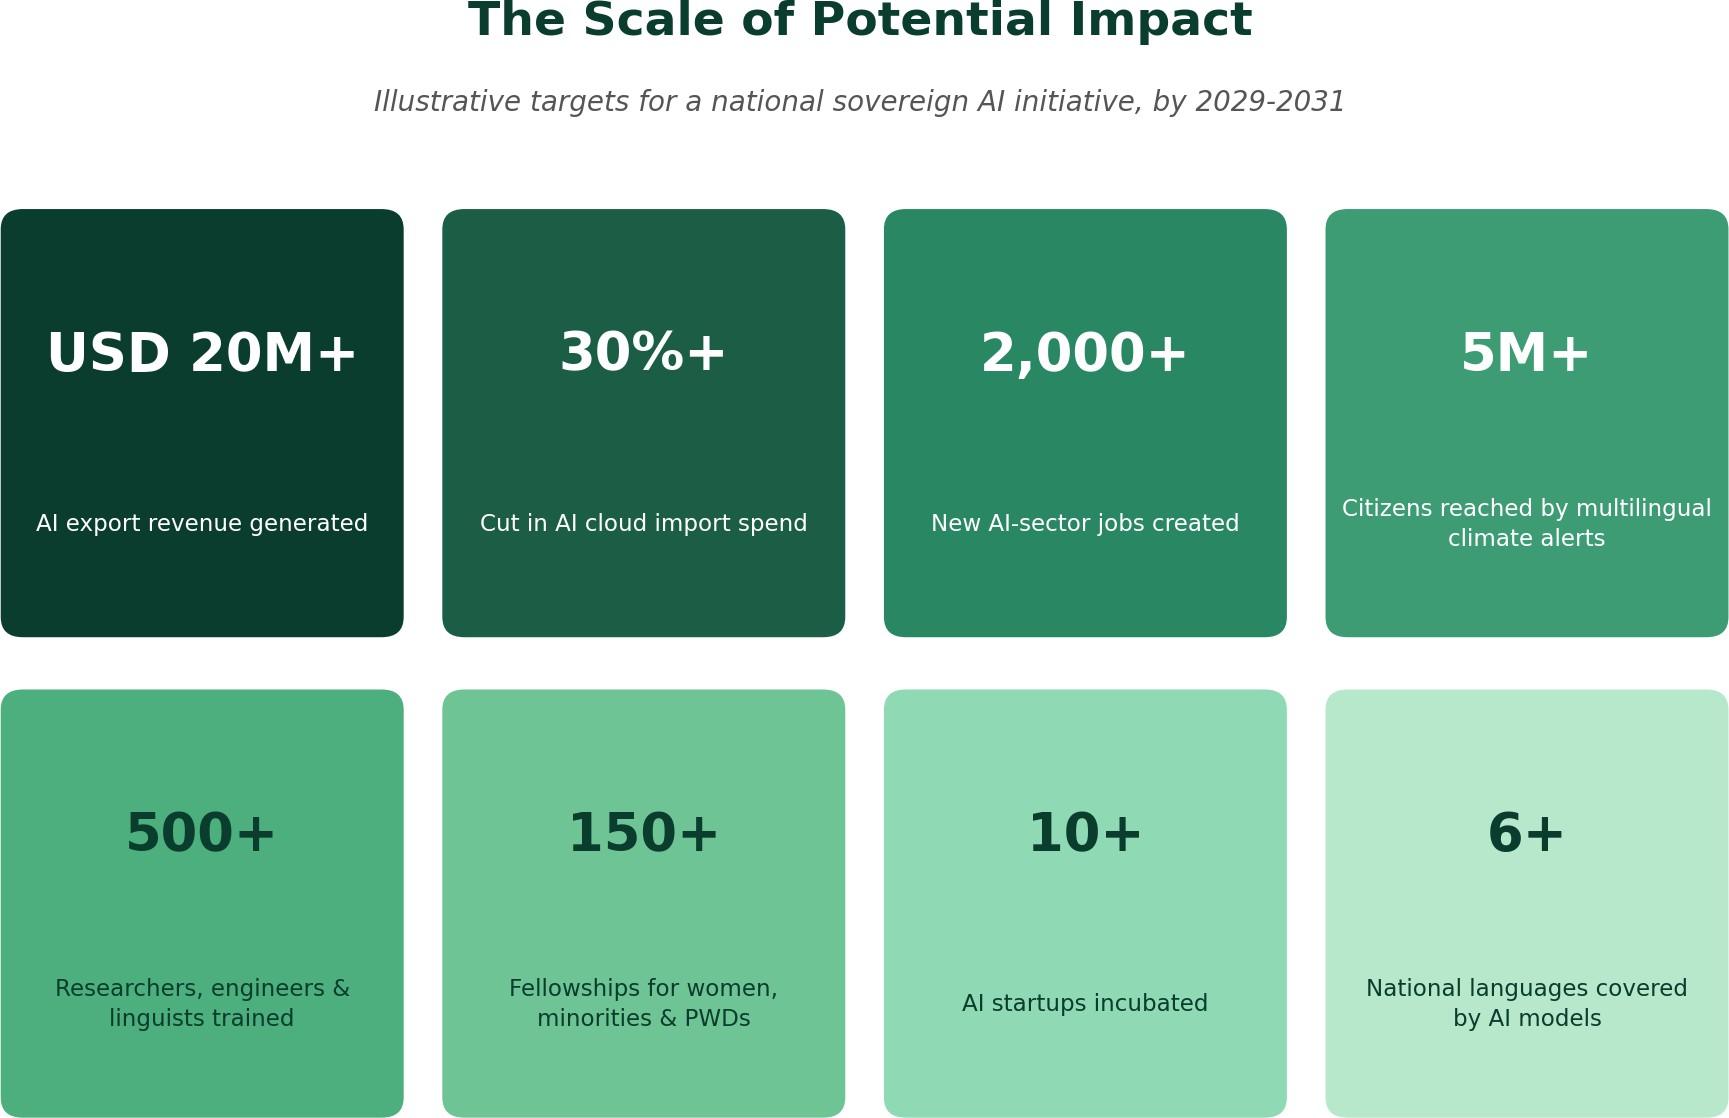
It would also do something harder to quantify but arguably more important. It would prove that Pakistan's universities, government, and private compute providers can build durable public infrastructure together, at national scale, without waiting for it to be handed to them from abroad.
The Bottom Line
Sovereign AI is not about competing with the US or China at every layer of the stack. That ambition would be unrealistic for almost any country outside those two. It is about making sure that at the layers where sovereignty is achievable, namely models, infrastructure access, datasets, and applications, a country like Pakistan is a builder and not merely a customer.
The hardware is starting to arrive. The policy exists on paper. What's missing is the connective tissue: a coordinated, geographically distributed, academia-industry-government consortium that turns scattered pockets of excellent work into a genuine national capability. That is the gap worth closing next, and the window to close it is now, while the foundational layers are still being poured.
What's your view: should sovereign AI be treated as a national infrastructure priority on par with energy and telecom, or is this better left to the market? I would be glad to hear your thoughts.
Ready to Go Beyond the Article?
Technology is
in our DNA


