
API-First Development: Why It's the Foundation for AI-Ready Enterprises


Introduction — The Integration Problem Nobody Budgets For
Most AI pilots don't stall because the model underperforms. They stall because nobody can get the model talking to the systems that actually run the business. A procurement agent gets built, a demo goes well, and then someone asks it to pull live vendor data from the ERP. That's usually where the timeline quietly falls apart.
Here's the pattern we keep seeing: enterprises pour budget into AI agents while their internal systems still communicate through nightly CSV exports, manual spreadsheet handoffs, and point-to-point scripts that one engineer wrote three years ago and nobody wants to touch. The agent is ready. The infrastructure underneath it isn't.
API-first development is what separates AI that becomes part of daily operations from AI that sits bolted onto the side of the business, dependent on someone manually feeding it data. It's not a technical nicety reserved for platform teams. It's the difference between an integration that takes an afternoon and one that takes a quarter.
This article makes the case for treating API-first development as core infrastructure, not a later-stage cleanup task. We'll walk through what the term actually means, why AI agents expose weaknesses that human developers used to quietly absorb, what a clean and agent-ready API looks like in practice, and where an enterprise should start if it's serious about becoming AI-ready rather than AI-adjacent.
What "API-First" Actually Means (And What It Doesn't)
Having a few APIs scattered across departments doesn't count. That's not API-first development — that's API-incidental development, where interfaces get created reactively, usually because one team needed to talk to another and nobody had a better option at the time.
API-first development flips the build order. Instead of writing internal application logic and exposing an API afterward as a convenience layer, teams design the API contract first: what the endpoints are, what data they return, how authentication works, what errors look like. Only once that contract is agreed on does implementation begin. The API isn't a side effect of the product. It is the product, or at minimum, it's treated with the same design discipline as one.
Compare this to code-first development, where the API emerges organically from whatever the internal code happens to expose. Code-first works fine when the only consumers are other engineers on the same team who can ask a colleague what an endpoint does over Slack. It falls apart the moment the consumer isn't a person who can ask questions.
That's exactly the situation enterprises are walking into with AI agents. An agent doesn't ping a teammate for clarification when a field name is ambiguous or a response format changes without notice. It either works with what it's given, or it doesn't work at all. That single shift — from human consumers who tolerate friction to machine consumers who don't — is why API-first development stops being optional the moment agentic AI enters the picture.
Why AI Agents Break on APIs That Were "Good Enough" for Humans
An API that's technically functional but poorly documented has always been a minor annoyance for engineering teams. A new hire spends an extra afternoon reading source code instead of documentation, shrugs, and moves on. That tolerance doesn't carry over to AI agents, and enterprises that assume it does tend to find out the hard way, usually mid-deployment.
Humans Tolerate Ambiguity. Agents Don't.
A developer who hits an undocumented edge case can trace through the codebase, ask around, or make an educated guess based on years of context about how the system generally behaves. An agent doesn't have that context, and it doesn't have the judgment to know when its guess is wrong. Inconsistent field naming, business logic that lives only in a senior engineer's memory, endpoints that behave differently depending on undocumented parameters — a human works around all of this without much friction. An agent either fails silently, returns something confidently incorrect, or stalls the entire workflow it's part of.
This matters more as agents get chained together into multi-step processes. One ambiguous endpoint doesn't just cause one bad response. It cascades through every downstream step that depended on that data being accurate.
Discoverability Is Now a Machine Requirement
If an agent can't infer what an endpoint does directly from its schema or its description, it has no reliable way to use it. There's no fallback where it opens a wiki page or messages a platform engineer.
This is why things that used to sit in the "nice to have, eventually" column — OpenAPI specifications, consistent naming conventions, predictable response shapes — now function as baseline infrastructure. Without them, an agent isn't just working less efficiently. It's often not able to work with the system at all.
The Real Cost of Bolt-On Integration
Enterprises that skip this groundwork don't avoid the cost. They defer it, and it tends to come back larger. Every new AI initiative that connects to a system without a proper contract requires its own custom glue code: a script here, a workaround there, a translation layer nobody fully documents because the deadline was tight. That code doesn't disappear once the project ships. It sits there as technical debt, and it compounds with every subsequent integration built the same way.
These bolt-on integrations are brittle by nature. When an internal system changes — a field gets renamed, a response format shifts slightly, an endpoint gets deprecated — nothing announces the change to the custom code depending on it. It just breaks, often silently, and often not until someone notices the agent has been working with stale or wrong data for a week.
There's also the opportunity cost that doesn't show up on a project timeline but shows up everywhere else. Every new AI initiative ends up re-solving the same connectivity problem the last one solved, because there was never a reusable foundation to build on. Teams reinvent authentication handling, error parsing, and data mapping project after project, instead of building once and reusing.
Contrast that with organizations that took API-first development seriously from the start. New agents and internal tools plug into existing, documented contracts. Integration work that used to take a sprint cycle takes days, because the hard part — designing a stable, discoverable interface — was already done.
What Clean, AI-Ready APIs Actually Look Like
None of this is abstract. Clean, agent-ready APIs share a handful of concrete characteristics, and none of them require exotic tooling. They require discipline applied consistently across teams.
Documentation as a Contract, Not an Afterthought
Documentation that gets written after the API ships tends to drift out of date within a few release cycles. Documentation that functions as a contract — written before implementation, kept in sync with every change — is different. Machine-readable specifications like OpenAPI or Swagger give both human developers and AI agents a single, structured source of truth for what an endpoint expects and returns. Pair that with consistent authentication patterns across services and disciplined versioning, so a breaking change doesn't quietly take down every agent that depended on the old behavior.
Predictable, Composable Endpoints
An agent chaining multiple API calls together to complete a task needs to trust that each call behaves the way the last one did. That means resource-oriented design, where endpoints map cleanly to business entities instead of internal implementation quirks. It means consistent error handling, so a failure looks the same whether it happens on call one or call twelve. And it means idempotency, so retrying a call after a timeout doesn't produce duplicate records or unintended side effects. These aren't abstract engineering preferences — they're what allow an agent to chain calls without guessing at what happens next.
Semantic Clarity Over Technical Cleverness
Naming conventions matter more than most teams give them credit for. An endpoint or field name that reflects internal implementation details — a legacy table name, an abbreviation only the original engineer understood — tells a human very little and tells an agent even less. Naming and structure that describe business meaning directly are what let an agent reason correctly about what it's calling and why. This isn't about making code look nicer. It's about making the system legible to something that has no other way of understanding it.
Building the Foundation: Where Enterprises Should Start
Getting to this point doesn't require a full platform rebuild. It requires a starting point and consistent follow-through.
- Audit existing APIs first, before adding anything new — documentation gaps, naming inconsistencies, and undocumented behaviors need to surface before they get built on top of.
- Establish API design standards at the organizational level, not per team, so different departments don't end up solving the same problem five different ways.
- Treat internal APIs with the same rigor as public-facing ones. An internal-only endpoint that powers an AI agent carries the same operational risk as a customer-facing one.
- Build every new interface with the assumption that both human developers and AI agents will consume it, rather than retrofitting agent compatibility after the fact.
None of these steps are glamorous. They're also the steps that determine whether the next AI initiative takes a week or a quarter.
How Techtics Approaches API-First Architecture for Agentic Systems
At Techtics, agentic systems don't get bolted onto enterprise infrastructure after the fact — the integration layer is designed alongside the agents themselves, using clean, documented contracts instead of one-off connections built for a single deployment. Multi-agent workflows, whether that's procurement systems coordinating quote, purchase order, and payment agents, or document processing pipelines handling cross-system handoffs, only function reliably when every agent involved can trust the interface it's calling.
That reliability doesn't happen by accident. It's the direct result of designing the API layer first, with the same rigor applied whether the consumer is a person on an engineering team or an autonomous agent completing a task without supervision. As orchestration across multiple agents and systems becomes more common, that foundation stops being a technical preference and starts being the reason the whole system holds together.
Build the Door Before You Build the Agent That Walks Through It
"AI-ready" was never really a model decision. It's an API decision, usually made months before any agent shows up looking for a system to connect to. Enterprises that treat API-first development as foundational infrastructure aren't just preparing for one project. They're building the door that every future agent, tool, and integration will eventually need to walk through.
If your systems weren't designed with that door in mind, that's worth finding out now, before the next AI initiative depends on it.
FAQ
What does "API-first" mean in the context of AI adoption?
It means designing and documenting an API's contract before building the underlying implementation, so any consumer — human or AI agent — has a stable, predictable interface to work with from day one.
Why do AI agents need better API documentation than human developers?
Human developers can work around ambiguity by asking colleagues or reading source code. Agents can't. They rely entirely on the schema and documentation to understand what an endpoint does, so gaps that a person would shrug off can stop an agent completely.
What's the difference between API-first and API-driven development?
API-first means the API contract is designed before implementation begins. API-driven typically refers to building products or workflows around existing APIs, which may or may not have been designed with this level of upfront discipline.
How do we retrofit API-first principles into a legacy enterprise system?
Start with an audit of existing endpoints to identify documentation gaps and inconsistent patterns, then apply org-wide design standards to new development while gradually bringing legacy interfaces in line, rather than attempting a full rebuild at once.
Does API-first slow down initial development?
It can add time upfront, since contracts get designed and agreed on before coding starts. That time is typically recovered many times over once integrations, agents, and internal tools stop requiring custom work for every new connection.
Recent Articles
Zero-Trust Security Frameworks for AI-First Organizations

For three decades, enterprise security was built around a simple assumption: define a perimeter, secure it, and trust whatever sits inside it. That model made sense when "inside the network" meant employees on company devices, behind a firewall, accessing systems through known applications.
AI-first organizations have quietly broken that assumption. Autonomous agents now query databases, call APIs, trigger workflows, and make decisions without a human clicking anything. The "trusted insider" in today's enterprise might be a piece of software that was prompted into existence an hour ago. Perimeter security has no good answer for that — which is exactly why zero trust has moved from a security buzzword to an operational necessity.
Why Traditional Perimeter Security Fails AI-First Organizations
Perimeter-based security assumes a relatively static, predictable set of actors: known users, known devices, known applications, all operating inside a defined boundary. AI systems violate nearly every part of that assumption.
Agents act with their own credentials, not a human's. An AI agent calling internal APIs, querying a database, or triggering a downstream workflow isn't a person logging in from a recognized laptop — it's a service identity that can be spun up, modified, or duplicated in seconds.
The attack surface is conversational, not just structural. Prompt injection attacks don't exploit a network vulnerability; they exploit the model's interpretation of input text. A malicious instruction embedded in a document, email, or web page can manipulate an agent into taking unauthorized actions, and a firewall has no visibility into that kind of attack at all.
Excessive agency creates new blast radii. When an AI agent is granted broad permissions to "get the job done" — access to multiple systems, the ability to execute code, the ability to send communications — a single compromised or manipulated agent can cause damage across every system it touches, not just the one it was originally deployed for.
Workloads move and scale dynamically. Containers, serverless functions, and orchestrated AI pipelines spin up and tear down constantly, which makes a fixed network perimeter nearly impossible to define in the first place.
None of this means perimeter security is worthless — but it means it's no longer sufficient on its own. Organizations deploying AI agents at scale need a model that doesn't assume safety based on location inside a network boundary.
What Zero Trust Actually Means
Zero trust is often summarized as "never trust, always verify," but the more useful framing for AI-first organizations is this: assume any identity, device, workload, or data request could be compromised, and require continuous verification before granting access — regardless of where the request originates.
This is a meaningful shift from perimeter thinking. Instead of asking "is this inside our network," zero trust asks "is this specific request, from this specific identity, for this specific resource, legitimate right now." That question gets asked every time, not once at login.
The Four Pillars of Zero Trust for AI Systems
A practical zero-trust architecture for AI-first organizations rests on four areas of continuous verification.
Identity
Every human user, service account, and AI agent needs a distinct, verifiable identity — not shared credentials, not generic API keys reused across systems. Agent identities should be issued, rotated, and revoked with the same discipline applied to human accounts, and every action an agent takes should be traceable back to that specific identity.
Device
The infrastructure an AI workload runs on — the container, the virtual machine, the edge device — needs to be verified as a known, compliant environment before it's trusted with sensitive operations. This matters more in AI systems than traditional ones because inference often happens across distributed, ephemeral compute resources rather than a fixed set of company-owned machines.
Workload
Each service, model, and pipeline component should be treated as its own trust boundary, with explicit rules governing what it can call, what data it can access, and what actions it can trigger. Microsegmentation — isolating workloads from each other rather than allowing broad internal network access — limits how far a compromised agent or model can reach.
Data
Data needs classification, encryption, and access policies that travel with it, not protections that depend on where the data happens to sit. When an AI agent retrieves data to answer a query or take an action, that retrieval should be checked against the same access policy a human user would face — not granted automatically because the request came from "inside" the system.
The Unique Attack Surface of Autonomous AI Agents
AI-first organizations face attack vectors that didn't meaningfully exist in pre-AI enterprise environments:
- Prompt injection. Malicious instructions hidden in documents, emails, or retrieved web content can hijack an agent's behavior, redirecting it to leak data or perform unauthorized actions.
- Tool and function-calling abuse. Agents with access to tools — sending emails, executing code, modifying records — can be manipulated into misusing those tools in ways a static application never could be.
- Excessive agency. Granting an agent broad, standing permissions "just in case" turns a narrow task into a wide-open liability if that agent is ever compromised or manipulated.
- Model and data poisoning. Attackers targeting training data or fine-tuning pipelines can introduce subtle behavioral changes that are difficult to detect through conventional security monitoring.
- Insecure agent-to-agent communication. As multi-agent systems become more common, the channels agents use to coordinate with each other become a new, often under-monitored attack surface.
These risks share a common thread: they exploit trust granted by default rather than verified continuously, which is precisely the gap zero trust is designed to close.
Implementing Zero Trust for AI Agents: Practical Steps
Issue scoped, short-lived credentials for every agent. Replace long-lived API keys with credentials that expire quickly and grant access only to the specific resources a given task requires — not standing access to entire systems.
Apply least-privilege access by default. An agent built to summarize support tickets shouldn't also have write access to the billing database. Default to the narrowest permission set that allows the task to function, and expand only with explicit justification.
Microsegment workloads. Isolate AI services from each other and from broader internal networks so that a compromised component can't move laterally to systems it was never meant to touch.
Monitor continuously, not just at access time. Behavioral anomaly detection — flagging when an agent suddenly accesses unusual data, calls unfamiliar tools, or deviates from expected patterns — catches manipulation that a one-time login check would miss entirely.
Classify and encrypt data at the source. Data should carry its access policy with it, so that any agent or service retrieving it is automatically subject to the same rules regardless of how it was queried.
Require human-in-the-loop checkpoints for high-risk actions. Irreversible or high-impact actions — financial transactions, external communications, code deployment — should route through human approval rather than full autonomous execution, at least until an agent's reliability has been extensively validated.
Validate and sanitize inputs to agents. Treat any external content an agent processes — documents, emails, scraped web pages — as potentially adversarial, and build filtering layers that reduce the risk of embedded prompt injection reaching the model unchecked.
Common Mistakes Organizations Make
Many AI-first organizations adopt zero-trust language without changing underlying architecture. A few patterns show up repeatedly:
- Treating zero trust as a product purchase rather than an architectural shift. A single identity tool doesn't deliver zero trust if workloads still communicate over flat, unsegmented networks.
- Granting agents human-equivalent access "to be safe." This inverts least-privilege thinking and creates exactly the broad blast radius zero trust is meant to prevent.
- Verifying identity once at deployment and never again. Continuous verification means re-checking trust at each request, not establishing it once when an agent is first provisioned.
- Ignoring agent-to-agent traffic. As multi-agent architectures grow, the assumption that "internal" agent communication is automatically safe recreates the same blind spot perimeter security had for human users.
Building a Zero-Trust Roadmap for AI Adoption
Organizations don't need to implement every control simultaneously. A practical rollout typically starts with identity — issuing distinct, scoped credentials for every agent and service — followed by microsegmentation of the highest-risk workloads, then continuous monitoring layered on top. Data classification and encryption policies should be established early, since retrofitting them after agents are already in production is significantly harder than building them in from the start.
The organizations managing AI risk well aren't the ones avoiding autonomous agents — they're the ones that have rebuilt their security architecture around the assumption that any identity, device, workload, or data request might be compromised, and verify accordingly, every time.
Talk to Our Team About Securing Your AI Systems
If your organization is deploying autonomous agents faster than your security architecture has evolved to handle them, that gap is worth closing before it becomes an incident. Talk to our team about building a zero-trust framework designed for how AI systems actually operate.
First Call to POC: How We Compress 6-Month to 5 Weeks
If you've ever sat through an enterprise AI pitch, you've heard the timeline: six months to a proof of concept. Sometimes nine. The vendor walks you through a Gantt chart full of "discovery phases" and "alignment workshops," and by month four you're still debating data access policies instead of looking at a working model.
That timeline isn't a reflection of how hard AI is to build. It's a reflection of how badly most teams manage the process of building it.
At Techtics, we take clients from first call to a validated, working proof of concept in five weeks. Not five weeks of slide decks — five weeks that end with a functioning system your team can actually test against real data and real workflows. Here's how that compression happens, and why it isn't about cutting corners.
Why Most AI Timelines Run Six Months (or Longer)
Six-month AI engagements rarely fail because the underlying model is hard to train. They fail because of structural drag built into how enterprise teams typically approach AI projects.
Procurement and vendor evaluation eat the first six to eight weeks.
Most organizations run a formal RFP process before a single line of code gets written, comparing five vendors against requirements that are still being defined.
Requirements gathering becomes a project of its own.
Stakeholders from product, engineering, compliance, and operations all need to weigh in, and reconciling their priorities can stretch into months if there's no structured way to capture and validate use cases quickly.
Data access and integration get treated as an afterthought.
Teams often don't audit their data sources, APIs, and system access until after the build has started, which means the engineering team discovers blockers mid-sprint instead of in week one.
Scope keeps expanding.
Without a fixed, validated use case, "let's also add this feature" creeps in continuously, and a focused POC slowly turns into a half-built production system that never quite ships.
None of these are technology problems. They're sequencing and discipline problems — and they're fixable.
The Real Bottleneck Isn't Technology, It's Process
Modern AI tooling — pretrained models, vector databases, orchestration frameworks, cloud-native infrastructure — has compressed the technical build time for a focused POC down to days, not months. A well-scoped predictive model, a retrieval-augmented chatbot, or an automation workflow can be prototyped in a sprint by an experienced team.
What actually consumes time is everything around the build: getting the right people in a room, validating that the use case is real before writing code, securing data access, and aligning on what "done" looks like. Compress those steps and the technical build naturally fits inside the remaining runway.
This is the core insight behind our 5-week framework: treat process compression, not engineering speed, as the primary lever.
The 5-Week Framework: From First Call to Validated POC
Week 1 — Discovery and Use Case Validation
The first call isn't a sales conversation; it's a working session. We map the business problem, identify the specific decision or workflow the AI system needs to improve, and validate that the use case is solvable with available data before committing engineering time. By the end of week one, there's a written scope document with success metrics both sides have signed off on.
Week 2 — Data Audit and Architecture Sprint
This is where most enterprise timelines silently lose months, so we front-load it. Our team audits data sources, API access, security requirements, and existing infrastructure in parallel with architecture design. We identify blockers now — missing data, access bottlenecks, compliance constraints — while there's still time to route around them without derailing the build.
Week 3 — Build Sprint
With scope and data access confirmed, the engineering team builds the core system: the model, the automation pipeline, the agent workflow, or whichever architecture fits the validated use case. Because scope was locked in week one, the team isn't building against a moving target.
Week 4 — Integration and Testing
The POC gets connected to a real (or representative) data environment and tested against the success metrics defined in week one. This is also when we run edge cases and stress-test the system against the messy, inconsistent data that real production environments actually contain, rather than the clean sample sets most demos rely on.
Week 5 — Validation and Stakeholder Sign-off
The final week is for the client's team to actually use the system, not watch a demo of it. Stakeholders test it against real scenarios, we capture feedback, and we document a clear path from POC to production scale-up. By the end of week five, you have a working system and a data-backed decision on whether to move forward.
What Makes Compression Possible (Without Cutting Corners)
A 5-week timeline only works because of decisions made well before the engagement starts:
- Reusable component libraries. Common building blocks — authentication layers, data connectors, model evaluation pipelines — don't get rebuilt from scratch for every client, which removes weeks of redundant engineering.
- Parallel workstreams instead of sequential handoffs. Data audits, architecture design, and early prototyping happen simultaneously rather than waiting on each other in a linear chain.
- Fixed-scope POC agreements. Locking the use case in week one prevents the scope creep that quietly turns a five-week sprint into a five-month slog.
- Embedded subject matter access. Having a PhD-level research team and domain specialists involved from day one means fewer "let's circle back next week" delays caused by needing outside expert input.
- Pre-vetted infrastructure templates. Cloud architecture and CI/CD patterns that have already been proven across 150+ prior projects don't need to be re-validated from zero each time.
This is compression through preparation, not through skipping validation steps. The POC that comes out the other end is something your team can stress-test, not a fragile demo built to impress in a single meeting.
What This Means for Enterprise Buyers
If you're evaluating AI vendors, the length of a proposed timeline tells you more about their process maturity than their technical capability. A team that needs six months to reach a POC is often telling you they haven't solved the coordination problem — not that the AI problem itself is six months deep.
A faster, well-structured timeline also changes the risk profile of the decision. Instead of committing budget and internal resources for half a year before seeing results, a 5-week POC gives you a concrete, testable artifact to evaluate before any larger commitment. That shifts AI adoption from a leap of faith into a series of small, validated bets.
Common Pitfalls That Stretch Timelines Back to Six Months
Even with a compressed framework available, a few mistakes can pull a project back toward the slow end:
- Skipping the data audit. Teams that jump straight to building without confirming data access almost always hit a wall mid-sprint.
- Letting stakeholders weigh in after the build starts. Validation needs to happen in week one, not week four, or scope will shift under the team's feet.
- Treating the POC like a finished product. A POC exists to validate an approach with real users and real data — not to ship every feature a production system would eventually need.
- Choosing a use case that's too broad. "Improve customer service with AI" isn't a scoped use case. "Reduce average response time on tier-one billing tickets using an AI triage agent" is.
Is Five Weeks Right for Every Use Case?
Not every AI initiative fits neatly into a five-week box — a multi-system enterprise rollout touching dozens of legacy integrations will need a longer runway. But for the most common entry point into enterprise AI — a focused proof of concept validating one clear use case — five weeks is achievable for the vast majority of organizations, provided the discovery and data audit steps aren't skipped.
The goal isn't speed for its own sake. It's removing the unnecessary friction that turns a solvable problem into a half-year commitment, so your organization can make a confident, evidence-based decision about scaling AI faster.
Frequently Asked Questions
How is a 5-week POC different from a typical MVP? A POC validates whether an approach works at all — does the model perform well enough on real data, does the workflow actually save time, is the use case technically feasible. An MVP assumes the approach is already validated and focuses on shipping a usable product to early customers. The 5-week framework is built for the validation stage, which is exactly where most AI initiatives stall.
What happens after the POC if we want to move to production? The week 5 deliverable includes a documented scale-up path: infrastructure requirements, security and compliance considerations, integration points with existing systems, and an estimated timeline for production deployment. Clients use this to make an informed go/no-go decision with their own stakeholders before committing further budget.
What if our data isn't ready? This is exactly why the data audit happens in week two rather than being assumed away. If data quality or access issues surface, we flag them immediately and adjust scope — sometimes that means narrowing the use case to data that is available now, with a roadmap for expanding once additional data sources are cleaned up or connected.
Does a faster timeline mean a less rigorous build? No. Rigor comes from validating the use case correctly and testing against real conditions in week four, not from how many calendar weeks the engagement runs. The compression comes from removing redundant process overhead, not from skipping testing or validation steps.
Ready to See Your Use Case in Five Weeks?
If your team has been quoted a six-month AI timeline, there's a good chance the bottleneck isn't the technology — it's the process around it. Talk to our team and find out what a validated proof of concept could look like for your organization in five weeks, not six months.
Why Pakistan Needs Its Own AI Stack, Not Just Its Own AI Users
Every country on earth now uses AI. Very few own any of it. That distinction, between being a consumer of artificial intelligence and being a sovereign participant in it, is quickly becoming one of the defining economic and strategic questions of this decade. Pakistan needs to decide, urgently, which side of that line it wants to be on.
The Five Layers of the AI Stack
To understand what “owning” AI actually means, it helps to break the technology down into five layers, each one more foundational than the last.
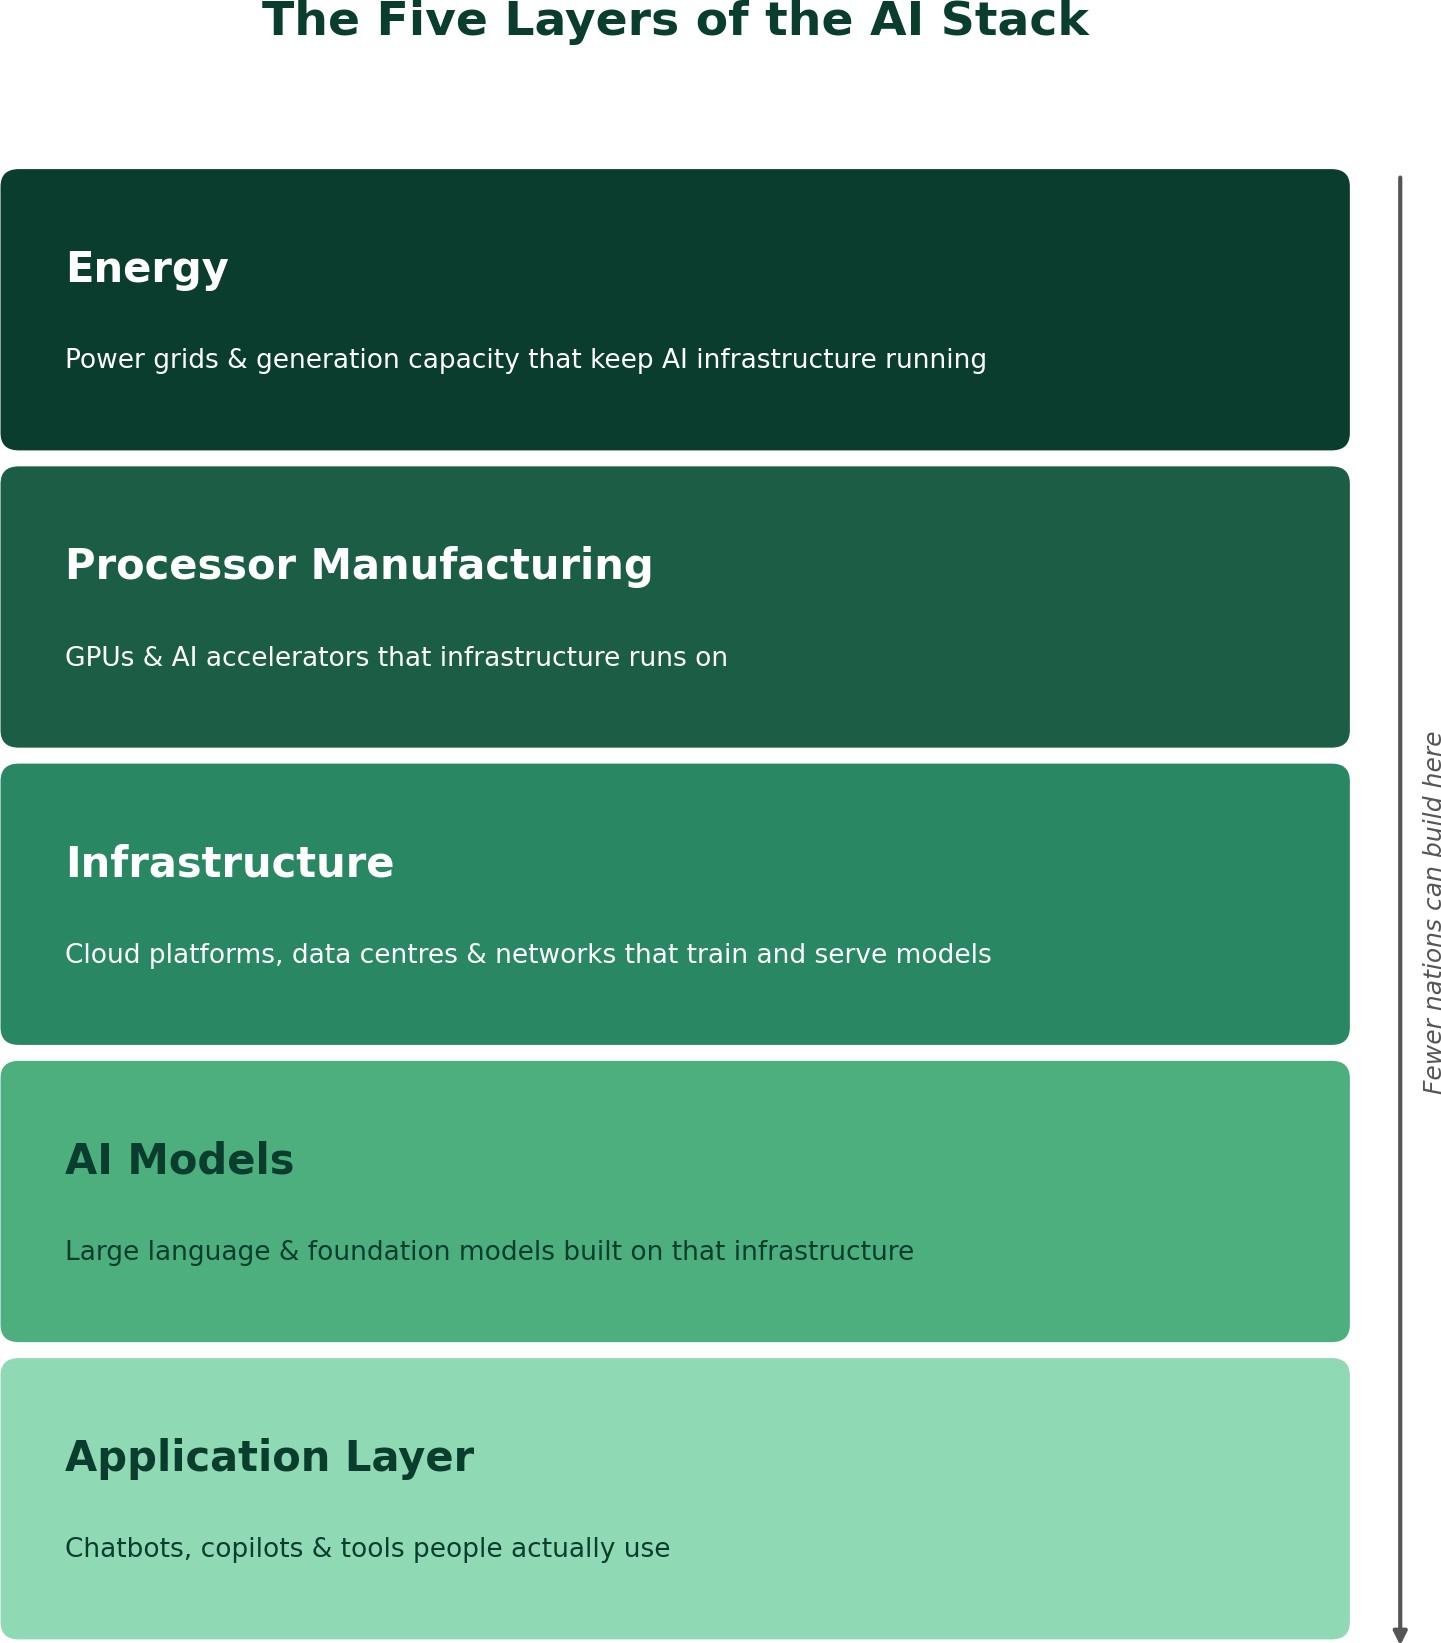
- Application Layer. the chatbots, copilots, and domain tools people actually use.
- AI Models. the large language and foundation models that power those applications.
- Infrastructure. the cloud platforms, data centres, and networks that train and serve those models.
- Processor Manufacturing. the GPUs and AI accelerators that infrastructure runs on.
- Energy. the power grids and generation capacity that keep all of the above running. A single modern AI training cluster can draw as much electricity as a small city.
Almost every country can build at Layer 1. A shrinking number can meaningfully operate at Layer 2 or 3. Only a handful of nations compete at Layers 4 and 5. The realistic question for a country like Pakistan is not “how do we compete at every layer.” It is “where in this stack can we build genuine, defensible capability, and how do we secure fair access to the layers we cannot own outright.”
The Global Race for Sovereign AI
Sovereign AI, the ability of a nation to develop, host, and govern AI on its own infrastructure, in its own languages, over its own data, has become a formal policy goal for dozens of governments.
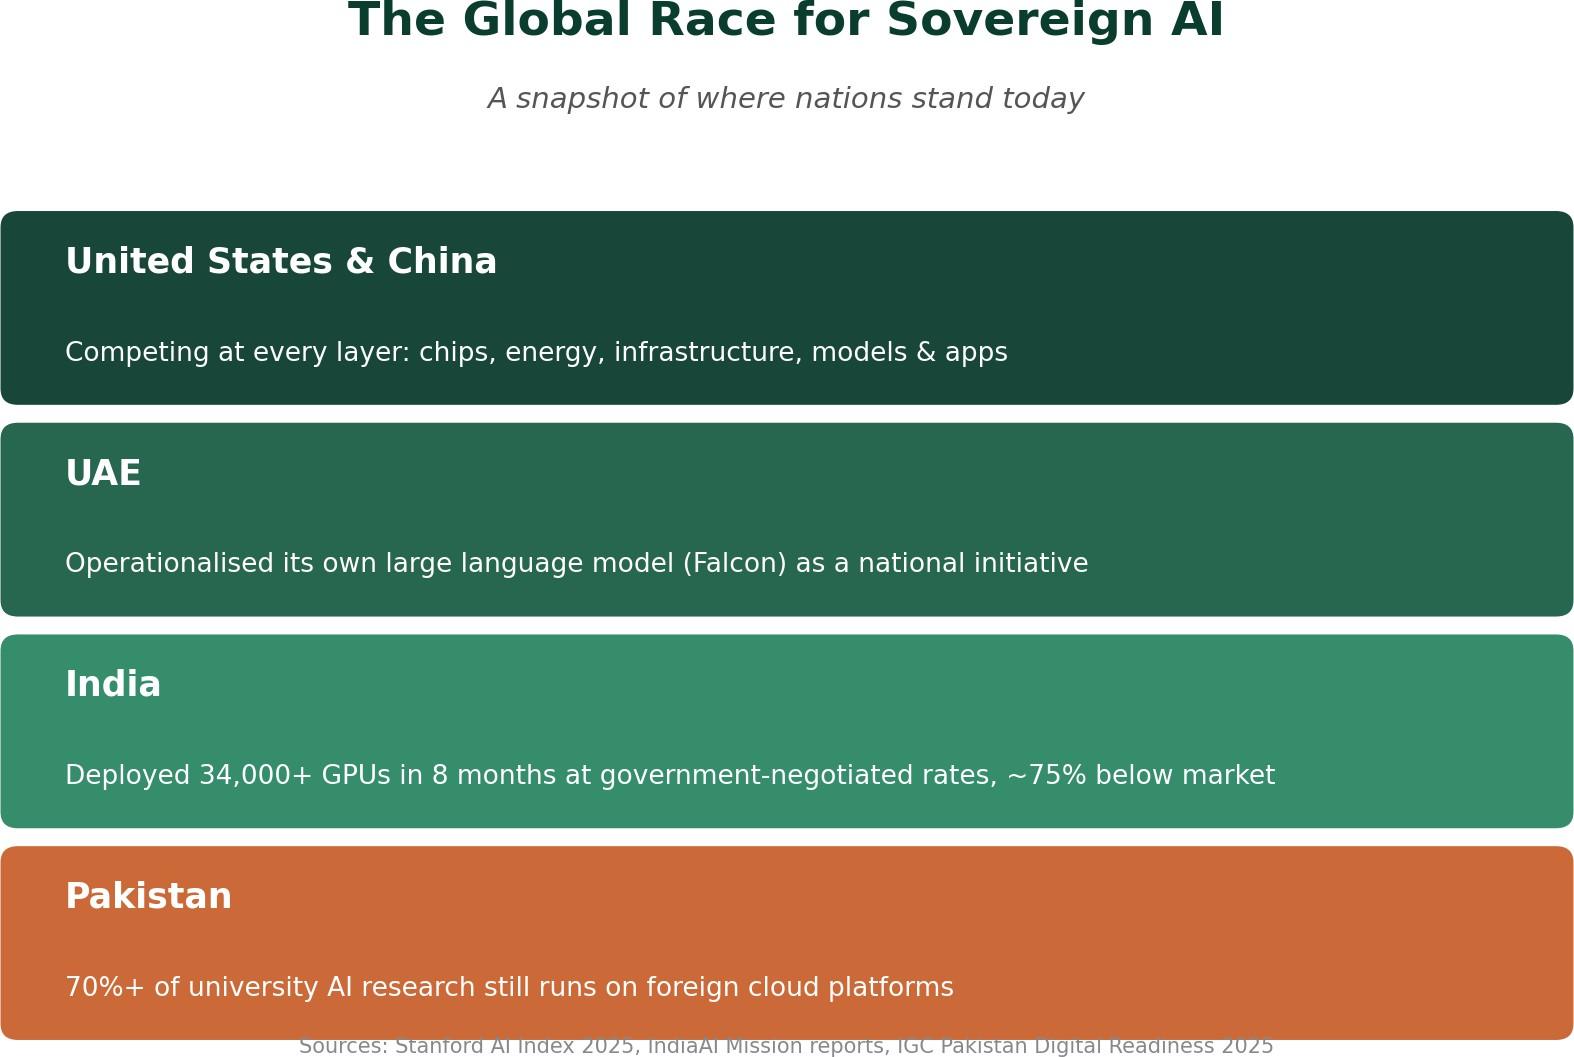
The US and China are racing at every layer of the stack at once. The UAE has operationalised its own Falcon large language model and is positioning itself as a regional AI hub. India's national AI mission deployed over 34,000 H100 and H200 class GPUs in just eight months, backed by a roughly ■10,372 crore (about USD 1.25 billion) government investment, and negotiated public-sector compute rates of about ■67 per GPU-hour, roughly 75% below global market prices. That is a masterclass in how a large, resource-constrained country can still build a public compute layer without trying to out-spend the hyperscalers dollar for dollar. Global corporate AI investment crossed USD 252.3 billion in 2024 alone, up 26% year on year. The gap between countries with a domestic AI stack and those without one is not closing. It is compounding.
Where Pakistan Stands Today
The honest picture is sobering. Pakistan currently ranks 97th out of 133 countries on digital infrastructure, skills, and usage, and 149th out of 197 on openness of government data. Pakistan's own university sector reports over 70% reliance on foreign commercial cloud platforms just to train and experiment with AI models. Sensitive national data, including health records, census data, education
data, and agricultural data, has for years been processed on servers outside Pakistan's jurisdiction, beyond the reach of domestic data protection law. And most large language models in wide use today have little to no meaningful grounding in Urdu or Pakistan's regional languages, which means a large share of the population is effectively invisible to the AI systems increasingly shaping commerce, governance, and public services.
As of mid-2026, Awareness and Readiness remains the only fully operationalised pillar of Pakistan's National AI Policy 2025. The Fifth Pillar, AI Infrastructure, calls explicitly for a national AI compute grid, national and provincial data repositories, and regulatory sandboxes, but the public-interest research, data, and talent layer this pillar envisions remains largely unbuilt, even as commercial GPU hosting has begun to emerge.
Why Sovereign AI Isn't Optional
This matters for four concrete reasons.
- Economics. Research suggests AI adoption could add up to 12% to Pakistan's GDP and create over 3.5 million jobs by 2030, but only if it is backed by genuine domestic capability and not just imported tools.
- Security and data sovereignty. A nation that cannot train or host its own models on its own sensitive data stays permanently dependent on foreign infrastructure for decisions that affect its citizens.
- Linguistic and social inclusion. AI that doesn't understand Urdu, Punjabi, Sindhi, Pashto, or Balochi simply doesn't work for most Pakistanis, no matter how capable the underlying model is.
- Economic leakage. Every dollar spent on foreign AI APIs and foreign cloud compute is a dollar that never builds local capacity, local jobs, or local intellectual property.
The Encouraging Part: Pakistan Isn't Starting From Zero
The good news is that real groundwork already exists, and the eighteen months to mid-2026 in particular saw fast movement, on both the policy and the commercial hardware side.
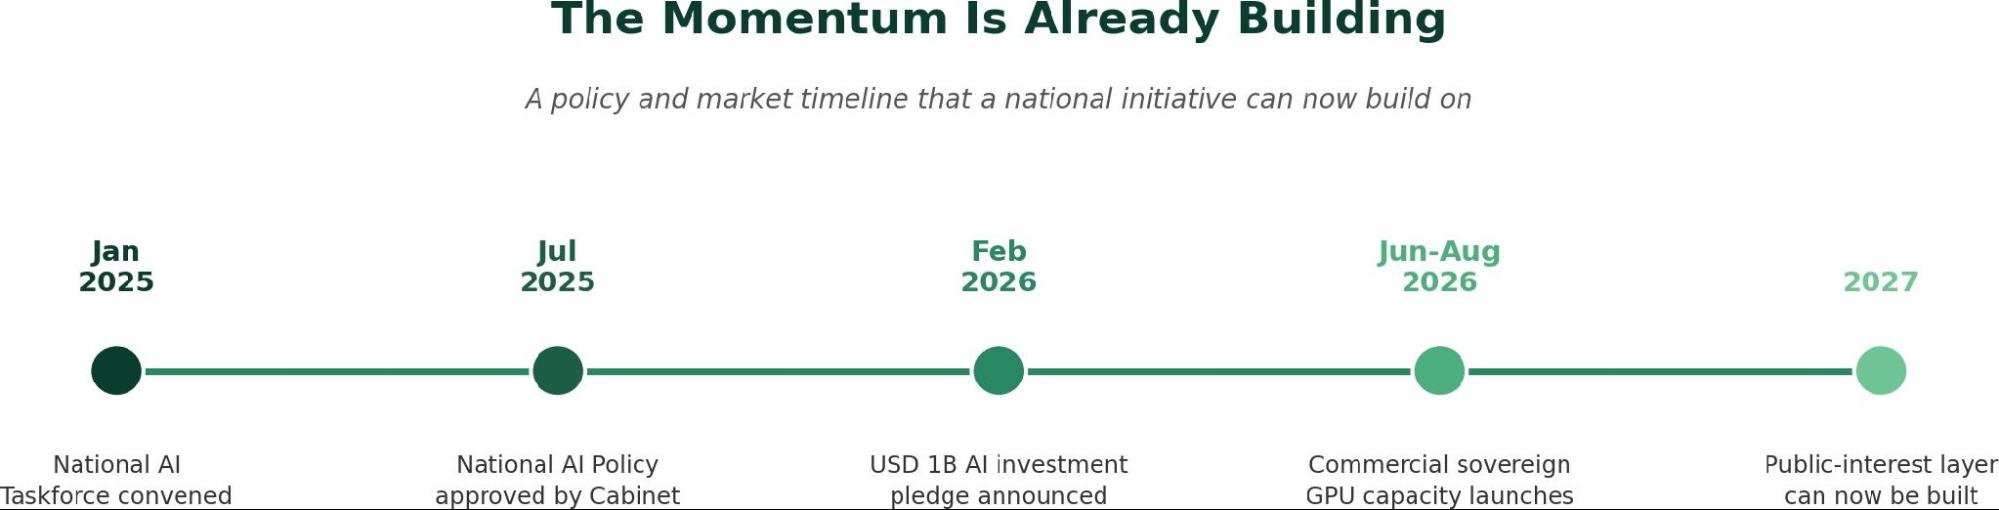
A premier government-backed AI research centre already operates nine laboratories across six universities and has shipped over 220 AI products spanning smart cities, precision agriculture, healthcare, and judiciary applications. A leading university's language engineering lab has spent decades building foundational Urdu NLP toolkits, morphological analysers, and speech corpora. A telecom operator, a major university, and the national IT board have jointly begun work on the country's first locally hosted large language model. A philanthropically funded AI hub, backed by a major international foundation grant, has just launched with a flagship focus on maternal and child health. A national open data portal has published over 1,100 public datasets across 14 sectors.
Most importantly, Pakistan's private sector has moved fast on the hardware side. Sky47's Karakoram-01 facility in Islamabad, an 8.5 MW Tier III/IV carrier-neutral sovereign cloud data centre, was inaugurated by the Prime Minister in July 2026, with a second facility in Karachi and a third city already planned. Data Vault Pakistan, based in Karachi, launched the country's first solar-powered GPU-as-a-Service data centre in mid-2025 and now runs a three-year sovereign AI services contract with the National Telecommunication Corporation for federal government workloads. Indus Cloud, run by the Master Group, brought online Pakistan's first Cisco AI GPU cluster built on NVIDIA H200 chips in August 2026, the first availability of brand-new H200 hardware on Pakistani soil. GPU prices have also fallen sharply, from over USD 25,000 to roughly USD 8,000 to 15,000 per unit, lowering the cost of building serious compute capacity. For the first time, the hardware half of the sovereign AI equation is genuinely being built on Pakistani soil.
The Problem: Fragmentation, Not Absence
These efforts are scattered. They are concentrated in one or two cities, running independently of one another, with no shared dataset repository, no common governance framework, and no deliberate mechanism connecting academia, government, and the private compute providers now coming online.
Commercial GPU hosting solves the hardware half of the problem. It does not, on its own, produce local-language models, curated public-sector datasets, or a pipeline of trained AI talent, because no commercial provider is commercially incentivised to build any of that. What Pakistan needs now is not another isolated initiative. It needs deliberate diversification: a footprint that spans provinces rather than a single city, that formally binds academia and industry together instead of leaving them to collaborate informally, and that is organised as a consortium-led national initiative rather than a single institution's project, so the effort survives beyond any one team, campus, or funding cycle.
The Way Forward: A Layered Build, Not a Single Product
The most credible path forward mirrors the five-layer stack itself, built from the bottom up, and at a scale that is modest by global standards but catalytic for a public-interest layer: a federated academic compute grid of several hundred GPUs, paired with negotiated access to the country's much larger new commercial capacity, can be enough to make the rest of the stack possible.
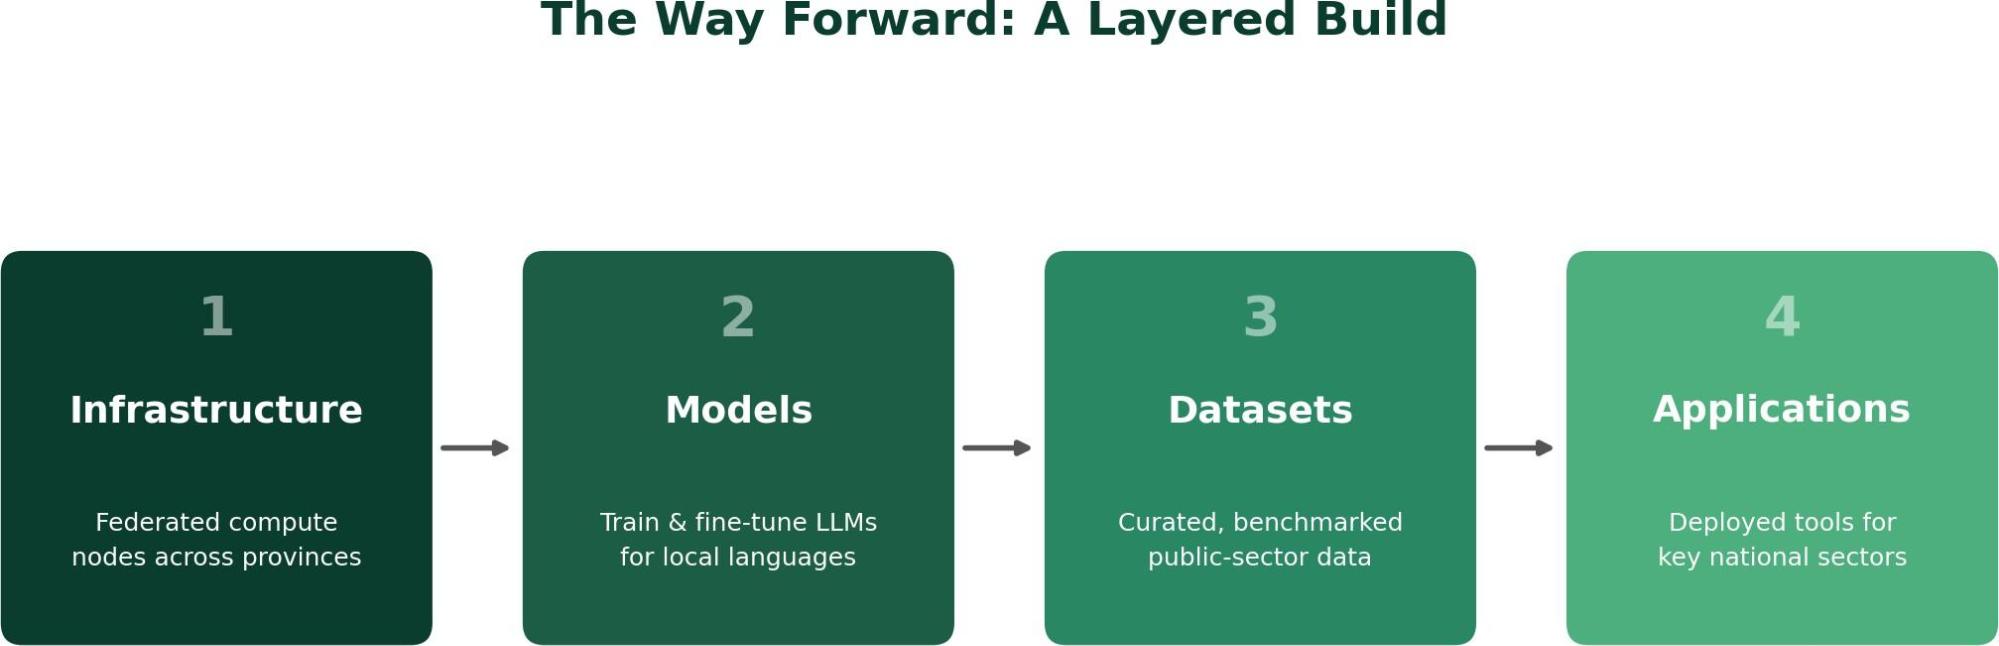
- Infrastructure first. federated, GPU-equipped compute nodes hosted across multiple universities in different provinces, paired with negotiated public-sector access to the country's new commercial GPU capacity for burst-scale training, so the public sector rents capacity intelligently instead of duplicating it.
- Models next. training and fine-tuning large language models covering six or more of Pakistan's languages, built on infrastructure the public sector actually controls, with open interfaces so researchers and startups can customise and extend them.
- Datasets. a secure, benchmarked, and versioned national repository of dozens of public-sector datasets across health, agriculture, water, climate, education, and governance, curated with proper academic custodianship and data protection compliance. This is the fuel without which no model, however well trained, can serve real national needs.
- Applications. tools piloted and deployed for both domestic impact and export revenue, so the stack ultimately serves citizens, industry, and international markets alike.
Where This Kind of Effort Can Deliver Impact
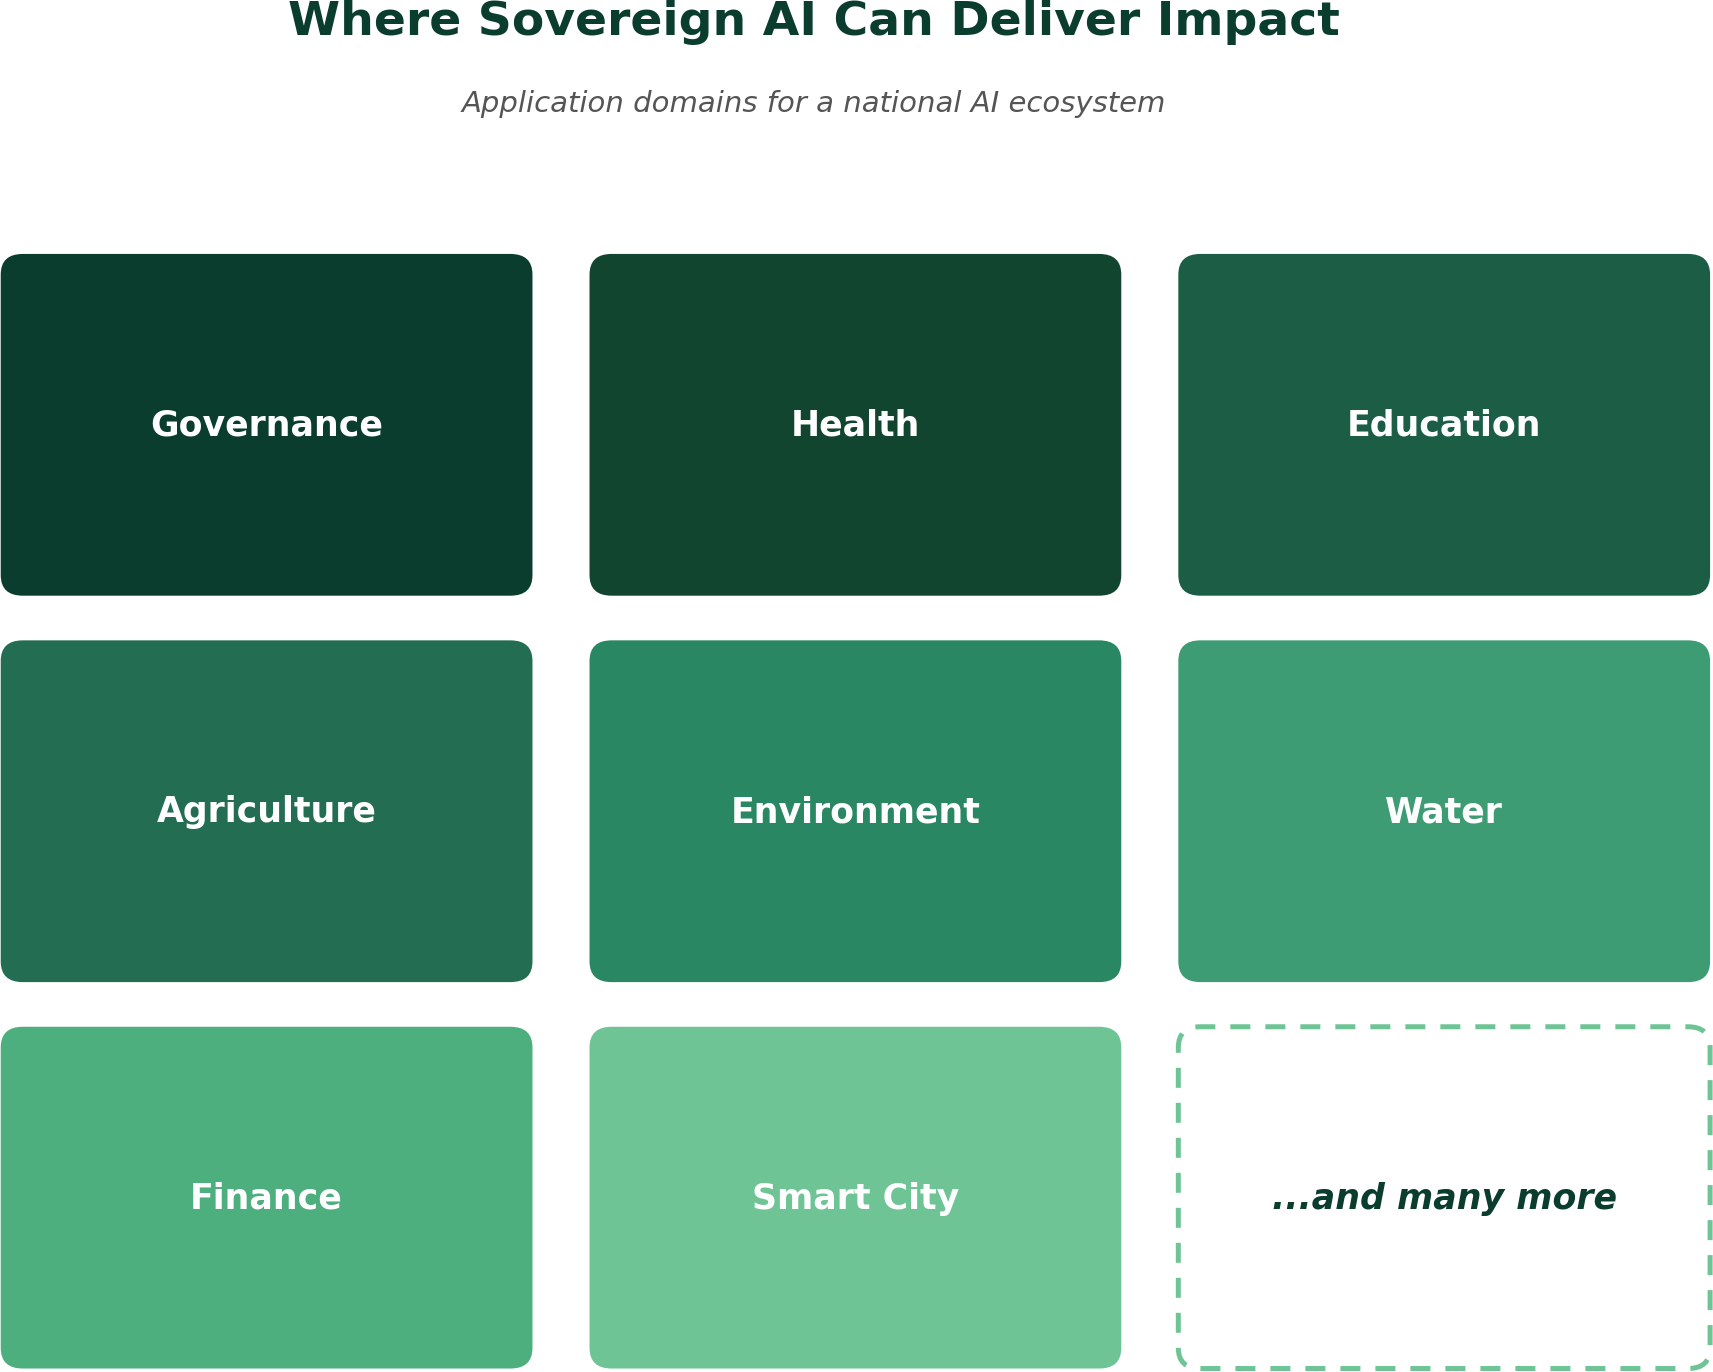
A national AI ecosystem built this way has clear application domains to aim at, each grounded in concrete, piloted use cases rather than abstract ambition, and this list is only a starting point:
- Governance. multilingual citizen-query assistants for e-governance portals, and smarter, data-driven policymaking.
- Health. multilingual AI-assisted triage and diagnostic support for frontline health workers in underserved districts.
- Education. adaptive, native-language AI tutors aimed at closing foundational literacy and numeracy gaps in rural schools.
- Agriculture. voice-enabled crop advisory and pest and disease identification for smallholder farmers in their own languages.
- Environment. climate risk mapping, land-use analysis, and remote-sensing tools built on local geospatial data.
- Water. flood forecasting and groundwater monitoring for water-stressed districts, grounded in local hydrological data.
- Finance. multilingual financial inclusion tools, credit-risk scoring, and fraud detection built for underserved and unbanked communities.
- Smart city. traffic and utility management, urban planning analytics, and municipal service delivery tools for growing urban centres.
- And many more. accessibility and inclusion tools, judiciary, media, and other domains are all within reach once the underlying models, datasets, and talent exist.
The Scale of Potential Impact
Done well, and funded at a modest scale (comparable initiatives elsewhere have been costed in the USD 10 to 15 million range over three years), an initiative structured this way could plausibly deliver the following by 2029 to 2031:
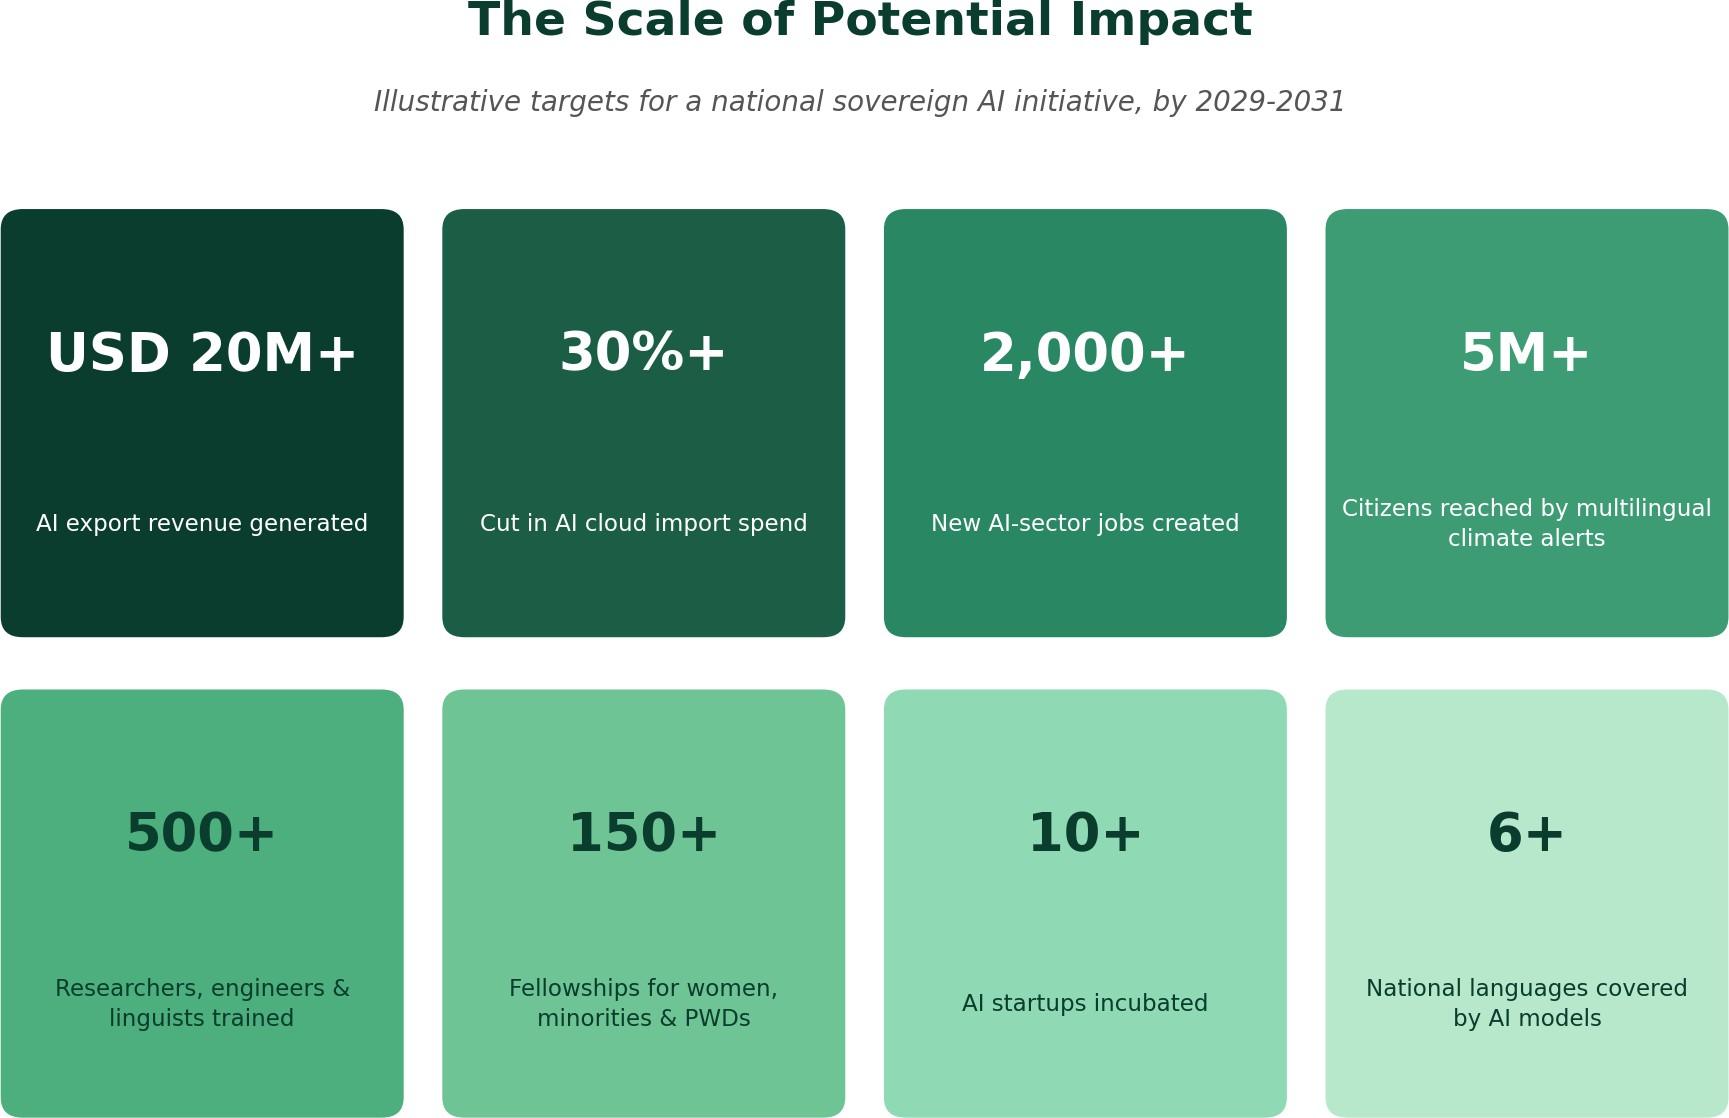
It would also do something harder to quantify but arguably more important. It would prove that Pakistan's universities, government, and private compute providers can build durable public infrastructure together, at national scale, without waiting for it to be handed to them from abroad.
The Bottom Line
Sovereign AI is not about competing with the US or China at every layer of the stack. That ambition would be unrealistic for almost any country outside those two. It is about making sure that at the layers where sovereignty is achievable, namely models, infrastructure access, datasets, and applications, a country like Pakistan is a builder and not merely a customer.
The hardware is starting to arrive. The policy exists on paper. What's missing is the connective tissue: a coordinated, geographically distributed, academia-industry-government consortium that turns scattered pockets of excellent work into a genuine national capability. That is the gap worth closing next, and the window to close it is now, while the foundational layers are still being poured.
What's your view: should sovereign AI be treated as a national infrastructure priority on par with energy and telecom, or is this better left to the market? I would be glad to hear your thoughts.
Ready to Go Beyond the Article?
Technology is
in our DNA


